A courier company's API documentation shows how to create a shipment as a cURL command: curl -X POST https://api.example.com/v1/shipments -H "Authorization: Bearer TOKEN" -H "Content-Type: application/json" -d '{"recipient": "Ayse Demir", "weight_kg": 3}'. It returns 201 Created in the terminal. You move it into Python as requests.post(url, data=json.dumps(body), headers={"Authorization": ...}), and the server answers 415 Unsupported Media Type: with a string in data=, Requests sends no Content-Type, and the line that set it stayed in the cURL command.
This guide covers json=, data= and files=, query parameters, headers and Bearer tokens, reading the response, and the Requests argument for each common cURL option. It ends with a checklist for requests that work in cURL but not in Python, and a small API client that retries safely. Every example ran on Python 3.13.9, Requests 2.34.2 and curl 8.21.0 (Windows 11), against httpbin.org and a local server that echoes the bytes it receives.
How do you send a POST request with Python Requests?
Install the package with pip install requests. PyPI lists 2.34.2, released on 14 May 2026, as the current version; it needs Python 3.10 or newer. Choosing between libraries is covered in HTTPX vs. Requests vs. AIOHTTP.
A POST with a JSON body is one call. httpbin.org/post sends back what it received:
import requests

payload = {"recipient": "Ayse Demir", "weight_kg": 3}
r = requests.post("https://httpbin.org/post", json=payload, timeout=20)

print(r.status_code)                         # 200
print(r.json()["headers"]["Content-Type"])   # application/json
print(r.json()["data"])                      # {"recipient": "Ayse Demir", "weight_kg": 3}
print(r.json()["json"])                      # the same body, parsed back into a dict
The data field is the body as sent, with a space after each colon and comma. requests.put(), requests.patch() and requests.delete() take the same arguments. Always pass timeout: Requests has no default, so a silent server leaves your script waiting (Max Retries Exceeded With URL covers timeout errors).
What is the difference between json=, data= and files=?
Each argument builds the body differently and sets a different Content-Type. We sent the same dict four ways:
import json
import requests

url = "https://httpbin.org/post"
body = {"recipient": "Ayse Demir", "weight_kg": 3}

for label, kwargs in [
    ("json=body", {"json": body}),
    ("data=body", {"data": body}),
    ("data=json.dumps(body)", {"data": json.dumps(body)}),
    ("json= and data=", {"json": body, "data": {"note": "x"}}),
]:
    echo = requests.post(url, timeout=20, **kwargs).json()
print(f"{label:22} {echo['headers'].get('Content-Type')!s:34} form={echo['form']} json={echo['json']}")json=body application/json form={} json={'recipient': 'Ayse Demir', 'weight_kg': 3}
data=body application/x-www-form-urlencoded form={'recipient': 'Ayse Demir', 'weight_kg': '3'} json=None
data=json.dumps(body) None form={} json={'recipient': 'Ayse Demir', 'weight_kg': 3}
json= and data= application/x-www-form-urlencoded form={'note': 'x'} json=NoneWhat the four lines show:
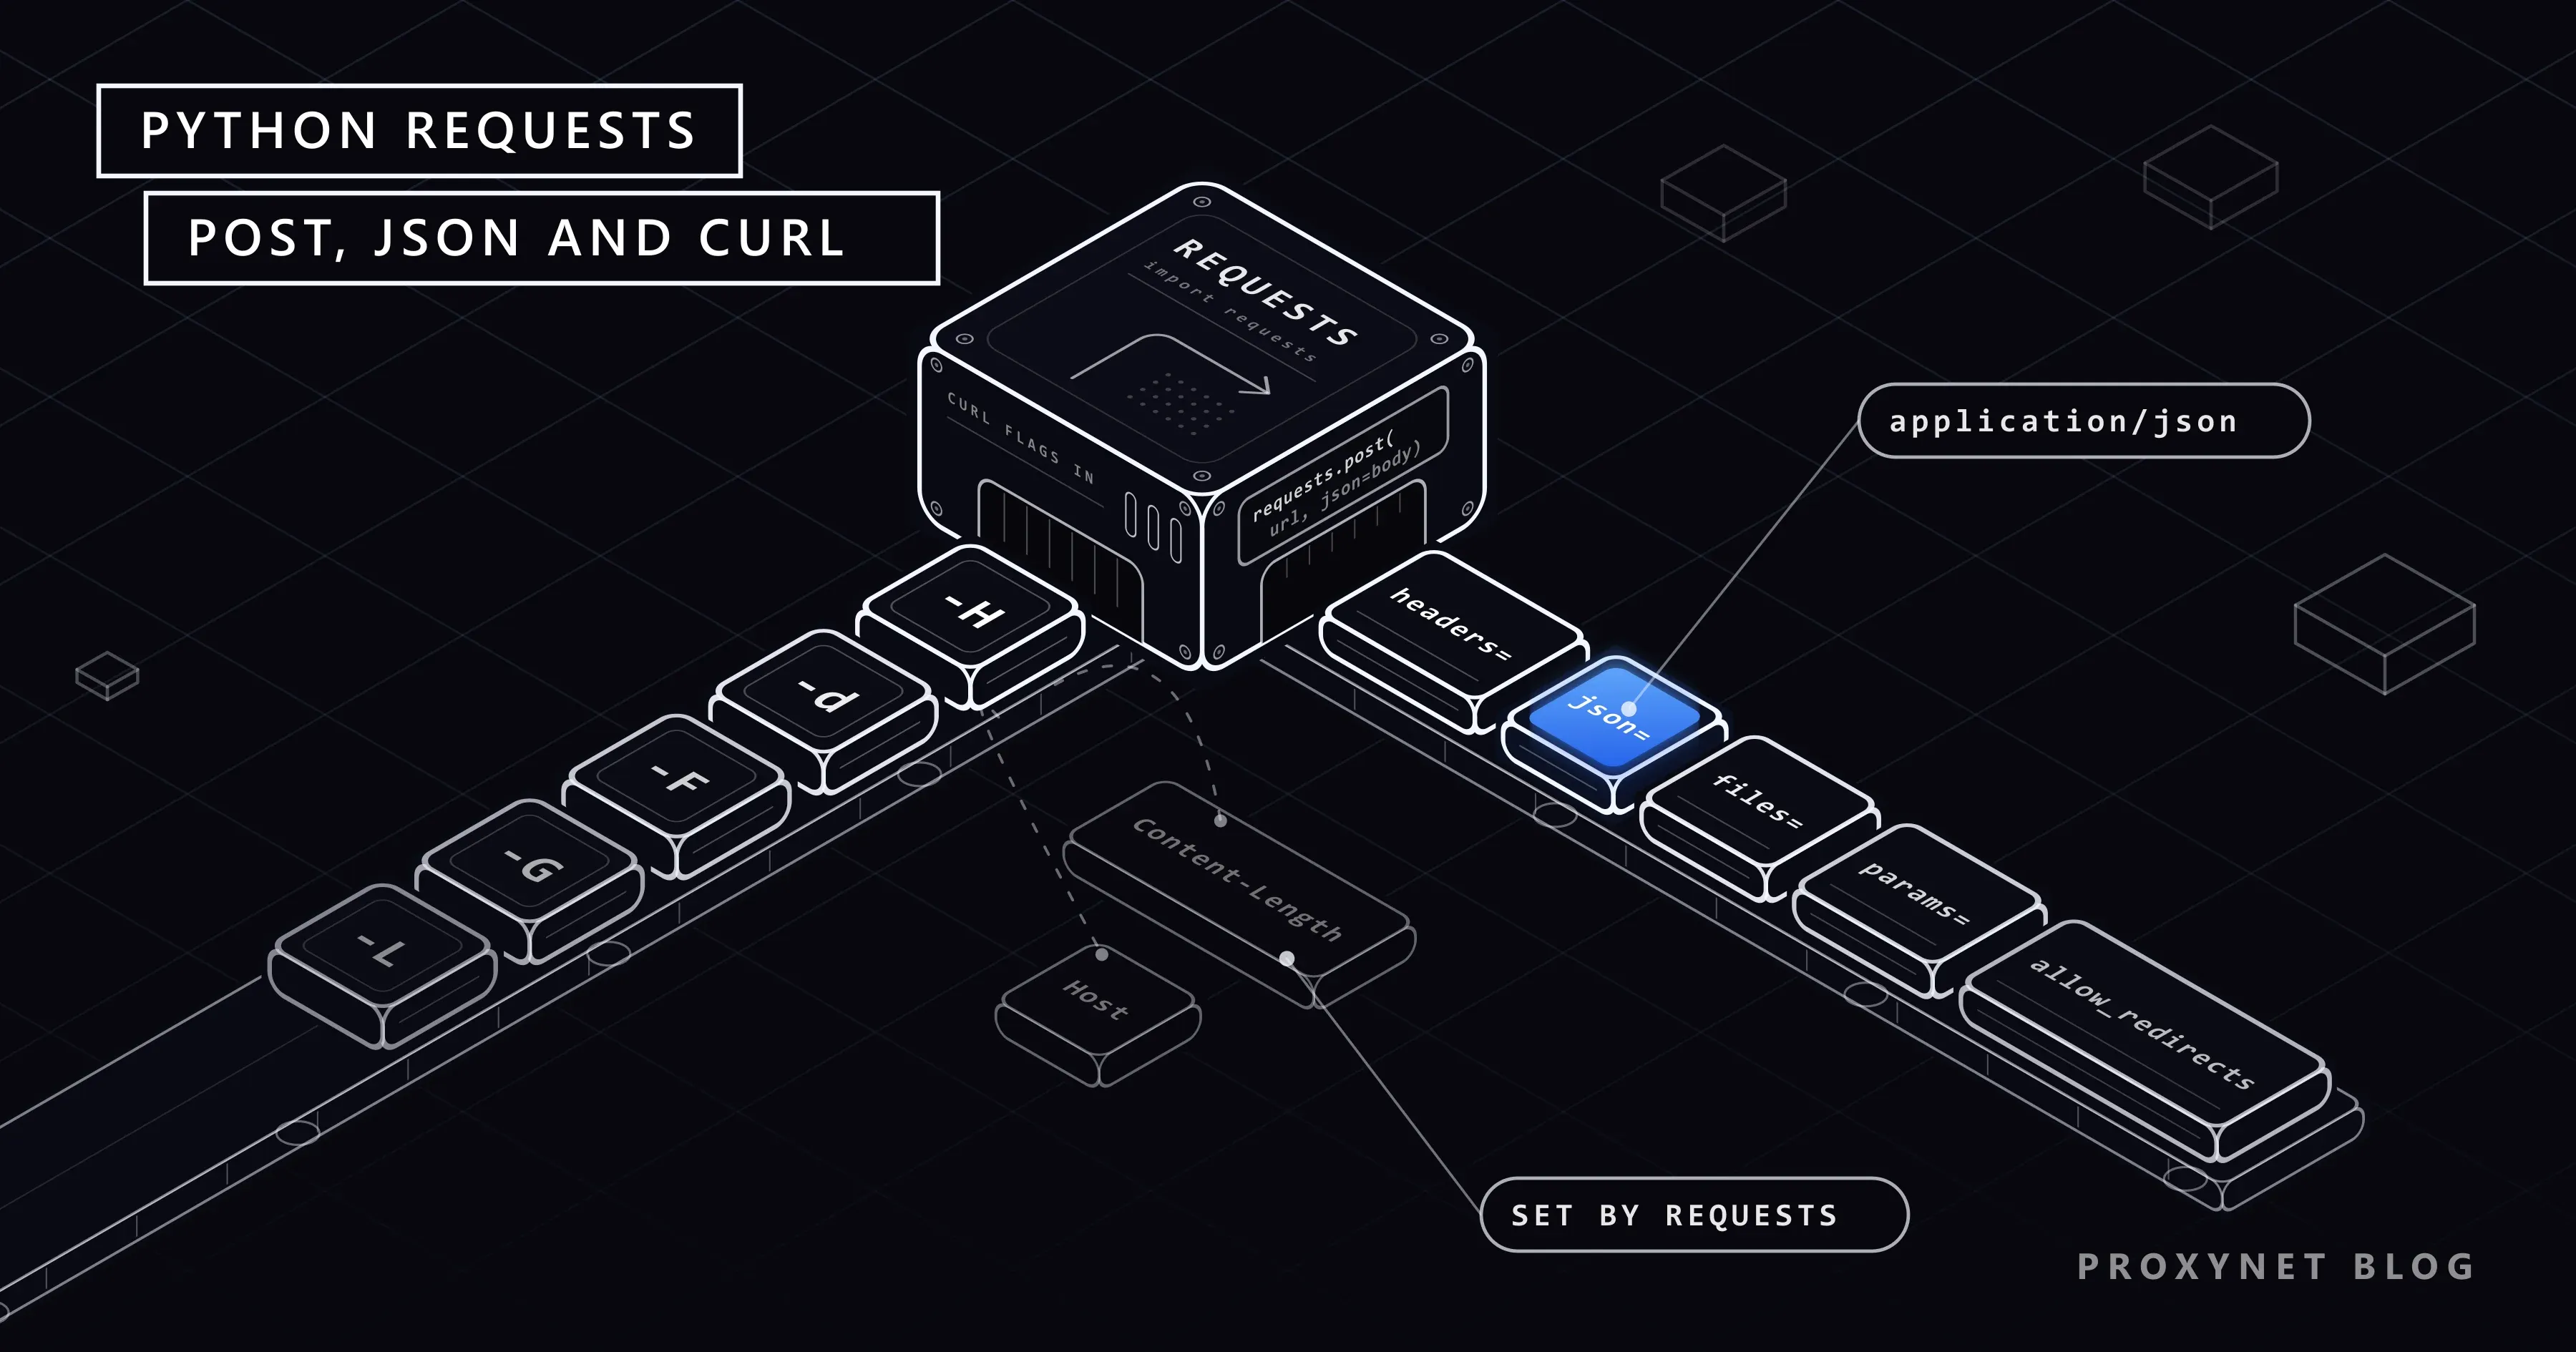
json=serialises the dict and setsContent-Type: application/json. Use it for JSON APIs.data=with a dict sends a form, and every value becomes text:weight_kgarrived as'3'.data=with a string sends noContent-Type. httpbin parsed it anyway; a strict API answers415or400. Set the header yourself.json=withdata=orfiles=loses the JSON without an error. The Requests quickstart says thejsonparameter is ignored if eitherdataorfilesis passed.
Send JSON text through data= only when the exact bytes matter. An API that signs the body with an HMAC checks the bytes it receives, and json= adds spaces and escapes non-ASCII characters ("İzmir" goes out as "\u0130zmir"). Build the bytes yourself:
import json
import requests

body = {"recipient": "Ayse Demir", "city": "İzmir", "weight_kg": 3}
raw = json.dumps(body, separators=(",", ":"), ensure_ascii=False).encode("utf-8")

r = requests.post("https://httpbin.org/post", data=raw,
                  headers={"Content-Type": "application/json"}, timeout=20)
print(r.json()["data"])  # {"recipient":"Ayse Demir","city":"İzmir","weight_kg":3}
These bytes had the same SHA-256 hash as the body curl --data-binary @body.json sent from the same UTF-8 file. Form logins with CSRF tokens are covered in Sessions and Cookies in Python, and files= below.
How do you translate a cURL command to Requests, step by step?
The same request, copied from the courier's web dashboard in the browser's Network panel, has a few extra lines. Finding such a request is covered in Static vs Dynamic Pages.
curl -X POST "https://api.example.com/v1/shipments?notify=false" \
  -H "Authorization: Bearer TOKEN" \
  -H "Content-Type: application/json" \
  -H "Accept-Encoding: gzip, deflate, br" \
  -H "Cookie: session=abc123" \
--data-raw '{"recipient": "Ayse Demir", "weight_kg": 3}'- Undo the shell syntax. Remove the
\line breaks (^in a copy made for Windowscmd) and the quotes. - Move the query string into
params=.?notify=falsebecomesparams={"notify": "false"}. - Filter the headers. Keep what the API needs:
Authorization,Accept, API keys. DropAccept-Encoding, which Requests handles, andContent-Typewhen you usejson=. Never copyHostorContent-Length; Requests works them out. Browser lines such assec-fetch-*are rarely needed, and aCookieline belongs incookies=or aSession. - Pick the body argument. JSON becomes
json=(ordata=with exact bytes if signed),-d "a=1&b=2"becomesdata={"a": "1", "b": "2"}, and-Fbecomesfiles=. - Pick the method.
-d,--data-raw,--jsonand-Fmean POST unless-Xsays otherwise;-Gmakes a GET query. - Add a
timeout=and callr.raise_for_status(). - Compare. Send the cURL command and your Python call to
https://httpbin.org/anythingand compare the echoed method, URL, headers and body.
The result, with the token read from an environment variable:
import os
import requests

r = requests.post(
    "https://api.example.com/v1/shipments",
    params={"notify": "false"},
    headers={"Authorization": f"Bearer {os.environ['API_TOKEN']}"},
    json={"recipient": "Ayse Demir", "weight_kg": 3},
    timeout=20,
)
r.raise_for_status()
print(r.status_code, r.headers.get("Location"))
curlconverter does steps 1 to 5, with Python Requests as its default output. Install it with npm and replace curl with curlconverter in the command. For the command above, version 4.12.0 moved notify into params, the cookie into cookies= and the body into json=, and commented out Content-Type and Accept-Encoding. It added no timeout, and its README warns that the generated code follows redirects unless the command sets a redirect policy. A browser command holds your live session cookie and token, so convert it locally, not on a website.
Which Requests argument matches each cURL option?
| cURL option | Requests | What differs |
|---|---|---|
-d '{"a":1}' with Content-Type: application/json | json={"a": 1} | Requests adds spaces; use data= for exact bytes |
--json '{"a":1}' | json={"a": 1}, headers={"Accept": "application/json"} | --json (curl 7.82.0+) also sets Accept |
-d "a=1&b=2" | data={"a": "1", "b": "2"} | Same bytes |
--data-binary @body.json | data=open("body.json", "rb") | -d @file would strip line breaks; both of these keep them |
-F "file=@report.csv" | files={"file": open("report.csv", "rb")} | curl labels the part application/octet-stream; Requests adds a type only from a 3-tuple |
-G --data-urlencode "q=kargo takip" | params={"q": "kargo takip"} | Same query: ?q=kargo+takip |
-X PUT | requests.put(url, ...) | Same for PATCH, DELETE |
-H "Name: value" | headers={"Name": "value"} | Values must be strings; an int raises InvalidHeader |
-A "ShipmentSync/1.0" | headers={"User-Agent": "ShipmentSync/1.0"} | Otherwise each tool sends its own name |
-b "session=abc123" | cookies={"session": "abc123"} | Same Cookie header |
-u user:pass | auth=("user", "pass") | Same Basic header |
-L | Default | cURL needs -L; allow_redirects=False turns it off in Requests |
--max-redirs 5 | session.max_redirects = 5 | Requests default: 30 |
--connect-timeout 3 -m 20 | timeout=(3.05, 20) | -m caps the whole transfer; the read timeout is the gap between bytes |
-k / --cacert ca.pem | verify=False / verify="ca.pem" | verify=False only in local tests |
-x http://user:pass@pr.proxynet.io:8000 | proxies={"http": url, "https": url} | See cURL with Proxy |
--compressed | Nothing | Requests handles compression itself |
-I | requests.head(url) | No redirects followed for HEAD |
-i / -v | r.headers / r.request.headers | What was received and sent |
Each option is described in the curl manual. A new proxy on every request is a separate job (How to Rotate Proxies in Python).
How do you pass query parameters and headers?
Give query values to params= as a dict:
import requests

params = {"q": "kargo takip", "status": ["pending", "shipped"], "sort": None}
r = requests.get("https://httpbin.org/get", params=params, timeout=20)
print(r.url)  # https://httpbin.org/get?q=kargo+takip&status=pending&status=shipped
A list repeats the key, None is left out, and spaces and non-ASCII characters are encoded for you. A query string already in the URL stays, with params= added after it. Paging through results is covered in Pagination in Web Scraping.
Headers go into a dict of strings, with the token read from the environment:
import os
import requests

headers = {
    "Authorization": f"Bearer {os.environ['API_TOKEN']}",
    "Accept": "application/json",
}
r = requests.get("https://httpbin.org/headers", headers=headers, timeout=20)
print(r.json()["headers"]["Authorization"])  # Bearer <your token>

r = requests.get("https://httpbin.org/basic-auth/user/pass", auth=("user", "pass"), timeout=20)
print(r.status_code)  # 200
Headers every call needs go on a requests.Session once, through session.headers. Three rules from the Requests documentation, all confirmed in our tests:
.netrcbeatsheaders=. A.netrcentry for the host replaced ourBearerheader with aBasicone;auth=beats both.- Authorization stays on the original host. After a redirect from
127.0.0.1tolocalhost, the header was gone. - Values are strings.
headers={"X-Page": 2}raisedInvalidHeader.
Without your own User-Agent, Requests sends python-requests/2.34.2. What to put there is in What Is a User Agent?, and why one client's headers should stay consistent in How to Scrape Websites Without Getting Blocked.
How do you read the response and catch HTTP errors?
A Response gives you r.status_code, r.headers (a dict that ignores letter case), r.content (raw bytes), r.text (the bytes decoded with r.encoding) and r.json(). Broken characters in r.text mean a wrong encoding guess (Python Encoding Errors).
The Requests documentation warns that a successful r.json() does not mean a successful request: a server can send a JSON error body with a 500. Check the status first:
import requests

r = requests.get("https://httpbin.org/status/404", timeout=20)
try:
    r.raise_for_status()
except requests.HTTPError as exc:
    print(exc)  # 404 Client Error: NOT FOUND for url: https://httpbin.org/status/404
raise_for_status() raises HTTPError for any 4xx or 5xx. When the body is empty or HTML, r.json() fails with JSONDecodeError (JSONDecodeError: Expecting Value lists the causes). Which codes to retry is in HTTP Status Codes in Web Scraping.
How do you upload and download files with Requests?
files= builds a multipart/form-data body. A 3-tuple sets the file name and part type, and data= fields travel as extra parts. Since json= is ignored next to files=, send JSON as its own part:
import json
import requests

with open("report.csv", "rb") as f:
    files = {
        "file": ("report.csv", f, "text/csv"),
        "meta": (None, json.dumps({"source": "warehouse"}), "application/json"),
    }
    r = requests.post("https://httpbin.org/post", files=files, data={"note": "daily"}, timeout=20)

print(r.json()["files"])  # {'file': 'sku,price\n1001,19.90\n'}
print(r.json()["form"])   # {'meta': '{"source": "warehouse"}', 'note': 'daily'}
Open the file in binary mode ("rb"): the documentation explains that Requests may set Content-Length to the file's byte count, and text mode can make it wrong. For very large uploads, the same page points to the requests-toolbelt package, which streams the body.
For downloads, stream=True keeps a large body out of memory:
import requests

url = "https://example.com/export.csv"  # replace with your file's URL
with requests.get(url, stream=True, timeout=(3.05, 60)) as r:
    r.raise_for_status()
    with open("export.csv", "wb") as f:
        for chunk in r.iter_content(chunk_size=64 * 1024):
            f.write(chunk)
Downloading many files from one page is covered in How to Download All Images From a Website.
Why does a request that works in cURL get a different answer in Requests?
Usually the two requests differ. Check in this order:
- Redirects. cURL stops at a
3xxwithout-L; Requests follows it for every method exceptHEAD. When either tool follows, a POST answered with301,302or303becomes a GET without a body, and307or308keep the POST, in line with RFC 9110. One exception: with-X POSTand-L, cURL sent a POST without the body after a302;--follow(curl 8.16.0+) switches to GET. Look atr.history, or passallow_redirects=Falseand readLocation. - Default headers. curl 8.21.0 sent
User-Agent: curl/8.21.0,Accept: */*and noAccept-Encoding. Requests sentpython-requests/2.34.2,Accept: */*,Connection: keep-aliveandAccept-Encoding: gzip, deflate(plusbrwith brotli installed,zstdon Python 3.14). Compare withr.request.headers. - HTTP version. Requests speaks HTTP/1.1 only:
r.raw.versionreturned11for an HTTPS site. curl negotiates HTTP/2 for HTTPS by default when its build supports it (curl -VlistsHTTP2), and-w "%{http_version}"prints the version used. Our Windows build lacks it and used1.1. - Environment. With
Session.trust_envat its defaultTrue, Requests readsHTTP_PROXY,HTTPS_PROXYandNO_PROXY, the system proxy settings on Windows and macOS when no variable is set, and.netrc. cURL reads the variables (http_proxyonly in lower case) but not the system settings, and.netrconly with--netrc.requests.utils.get_environ_proxies(url)shows what Requests picked; the variables are explained in Using a Proxy with wget. - Certificates. Requests uses the
certifibundle; curl on Windows with Schannel uses the Windows store. Behind a company proxy that inspects TLS, cURL can pass while Requests raisesSSLError(fix in Max Retries Exceeded With URL). - Body bytes.
json=re-serialises the body, and-d @filestrips line breaks. Hash both bodies if the API signs them. - The wire. A local MITM proxy shows both requests side by side.
If everything matches and the answer still differs, the site is judging the client itself, for example its TLS handshake, which headers do not change. Cloudflare Scraper explains how to read such an answer, and TLS Fingerprinting and JA3 what the handshake reveals. The way forward is the site's official API or the owner's permission; we do not cover tools that disguise a script as a browser.
Full example: a small API client with safe retries
The script keeps the Bearer token and shared headers on one Session, sends params= with a GET and json= with a POST, and checks every status. It retries only the GET: MDN describes POST as not idempotent, so a repeat can create a second shipment. The urllib3 Retry class already leaves POST out by default; the script spells it out.
"""A small API client: GET with params, POST with json=, retries for GET only."""
import os

import requests
from requests.adapters import HTTPAdapter
from urllib3.util import Retry

API = os.environ.get("API_BASE", "https://api.example.com/v1")
TIMEOUT = (3.05, 20)  # connect timeout, read timeout (seconds)


def make_session():
    session = requests.Session()
    session.headers.update({
        "Authorization": f"Bearer {os.environ['API_TOKEN']}",  # never hard-code the token
        "Accept": "application/json",
        "User-Agent": "ShipmentSync/1.0 (+https://example.com/contact)",
    })
    retry = Retry(
        total=3,
        backoff_factor=0.5,
        status_forcelist=[502, 503, 504],
        allowed_methods=["GET"],  # a repeated POST could create the same shipment twice
        raise_on_status=False,    # hand back the last response, raise_for_status() reports it
    )
    adapter = HTTPAdapter(max_retries=retry)
    session.mount("https://", adapter)
    session.mount("http://", adapter)
    proxy = os.environ.get("PROXY_URL")  # optional, e.g. http://user:pass@pr.proxynet.io:8000
    if proxy:
        session.proxies = {"http": proxy, "https": proxy}
        session.trust_env = False  # otherwise HTTPS_PROXY or the system proxy wins over session.proxies
    return session


def list_shipments(session, status="pending", page=1):
    r = session.get(f"{API}/shipments", params={"status": status, "page": page}, timeout=TIMEOUT)
    r.raise_for_status()
    return r.json()


def create_shipment(session, recipient, weight_kg):
    body = {"recipient": recipient, "weight_kg": weight_kg}
    r = session.post(f"{API}/shipments", json=body, timeout=TIMEOUT)
    r.raise_for_status()
    return r.status_code, r.headers.get("Location"), r.json()


if __name__ == "__main__":
    with make_session() as s:
        try:
            print(list_shipments(s))
            print(create_shipment(s, "Ayse Demir", 3))
        except requests.HTTPError as exc:
            print("API error:", exc)
Against a local server that imitates the API, the GET returned the list and the POST 201 with a Location header. When the server answered 503, the GET went out four times (waiting 0, 1 and 2 seconds between tries) before raise_for_status() reported it; a POST to the same address went out once. Through a local test proxy set in PROXY_URL, both calls worked, and a wrong password gave 407 Proxy Authentication Required.
urllib3 also honours Retry-After on a 503 by default; handling 429 is covered in HTTP Status Codes in Web Scraping, and many parallel calls in Concurrency vs Parallelism.
Use cases
- Product or price data from an API the site offers (data scraping).
- A JSON endpoint found in the Network panel, called instead of rendering the page (Static vs Dynamic Pages).
- Crawling the pages behind API results at a polite rate (Python Web Crawler).
- Testing your own webhook or internal service from a script rather than a GUI tool (Postman with a proxy).
- Checking an API's answer for another country through a Residential Proxy there.
- An API that accepts only registered IP addresses, called from one fixed exit (Static IP for API Access).
- The same request in Node.js with fetch or Axios (cURL in JavaScript).
Common mistakes
data=json.dumps(body)withoutContent-Type. The server cannot tell it is JSON; usejson=body.json=anddata=in one call. The JSON is dropped silently.- No
timeout. One silent server stops the script. - Gluing the query string by hand. Spaces and non-ASCII characters break the URL.
r.json()before the status check. A500with a JSON error body parses fine.- Uploads opened in text mode. Use
"rb". - Copying
HostandContent-Length. Requests sent a copiedHostunchanged, so a test against another server still named the old one. A copiedContent-Lengthon a GET without a body made our server wait until the read timeout. - Browser commands pasted into online converters. They contain your session cookie and token.
verify=Falsein production. It turns off certificate checks.- Retrying POST blindly. A retry after a timeout can create a second record.
Decision guide
| Need | Recommendation |
|---|---|
| JSON body for an API | requests.post(url, json=data, timeout=20), no manual Content-Type |
| Signed body, byte for byte | data= with bytes you serialised, plus Content-Type |
| Plain form (not a login) | data= with a dict; logins and CSRF in the sessions guide |
| File with extra fields | files= plus data=; JSON as its own application/json part |
| Quick cURL translation | The table above, or curlconverter on your machine |
| Works in cURL, not in Python | Check r.history, r.request.headers, trust_env, HTTP version |
| HTTP/2 or async calls | HTTPX; AIOHTTP for async only |
Frequently asked questions
Do I need to set the Content-Type header when posting JSON with Requests?
Not with json=: Requests sets Content-Type: application/json itself. You need it when you pass JSON text through data=, because a string in data= goes out without one, and a strict API then answers 415 Unsupported Media Type or 400.
What is the difference between json= and data=json.dumps() in Requests?
Both send JSON text, but only json= adds the Content-Type header. The bytes can differ too: json= writes spaces after colons and commas and escapes non-ASCII characters. Use json= by default, and data= with your own bytes when an API signs the body.
How do I send a Bearer token with Python Requests?
Use headers={"Authorization": f"Bearer {token}"}, or set it once in session.headers. Read the token from an environment variable. If a .netrc file has credentials for the same host, Requests uses those instead; Session.trust_env = False turns that off.
Can I convert a cURL command to Python automatically?
Yes. curlconverter turns a cURL command into Requests code and runs on your own machine. Review the output: it adds no timeout, and Requests follows redirects the cURL command did not. Keep commands with cookies or tokens away from online converters.
Does Requests follow redirects, and why does my POST turn into a GET?
Requests follows redirects for every method except HEAD. After a 301, 302 or 303, a POST becomes a GET and loses its body, as in browsers; after 307 or 308, it stays a POST. allow_redirects=False stops at the first answer.
Does Python Requests support HTTP/2?
No. Requests speaks HTTP/1.1 only; in our test r.raw.version returned 11 for an HTTPS site. HTTPX supports HTTP/2 when you install httpx[http2] and create the client with http2=True; it is off by default.
Summary
For a JSON API, requests.post(url, json=data, timeout=20) is the whole job: Requests serialises the body and sets the header. data= sends forms or exact bytes, files= multipart bodies, and params= the query string. A cURL command maps onto these arguments option by option; when the answers still differ, check redirects, default headers, the HTTP version and the environment, in that order. When an API has to be called from a given country or a fixed address, compare the options on our proxy services page.