

































Web Scraping · Proxynet Blog – Page 4

Published
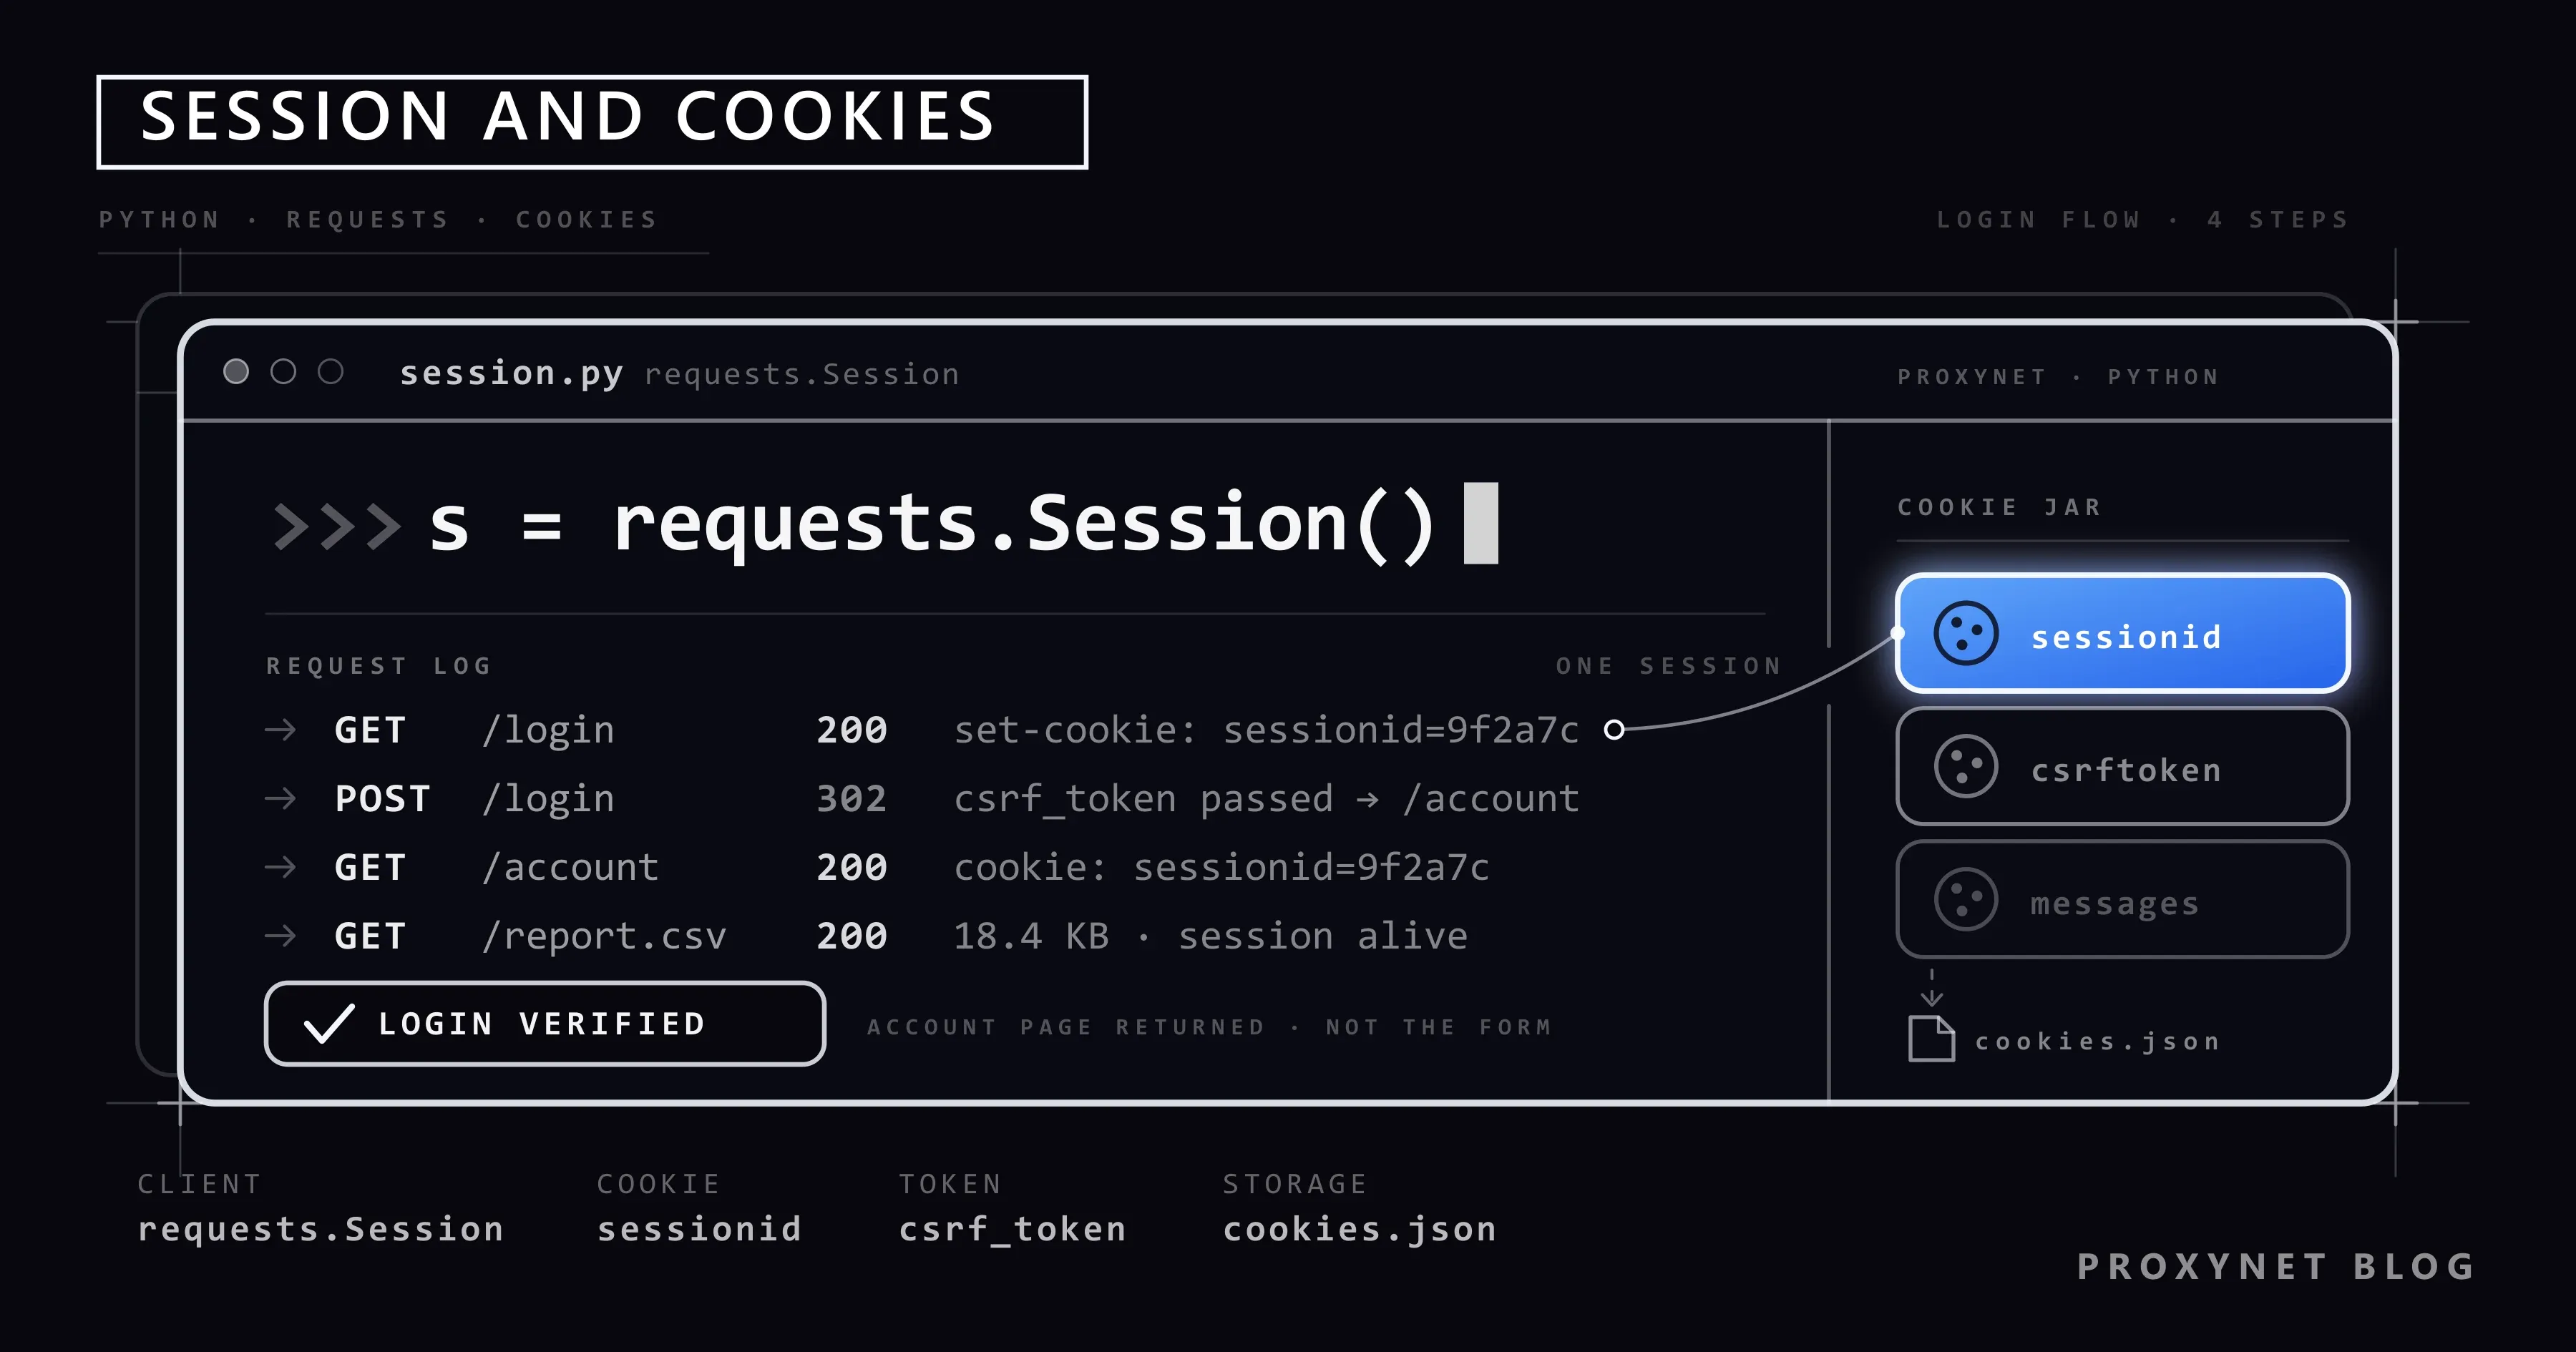
Sessions and Cookies in Python: Logging In With requests
requests.Session carries cookies between requests and keeps a session alive. Read the CSRF token from the form, verify the login and store the session on disk.
Written by: Acar Diveroli
Published
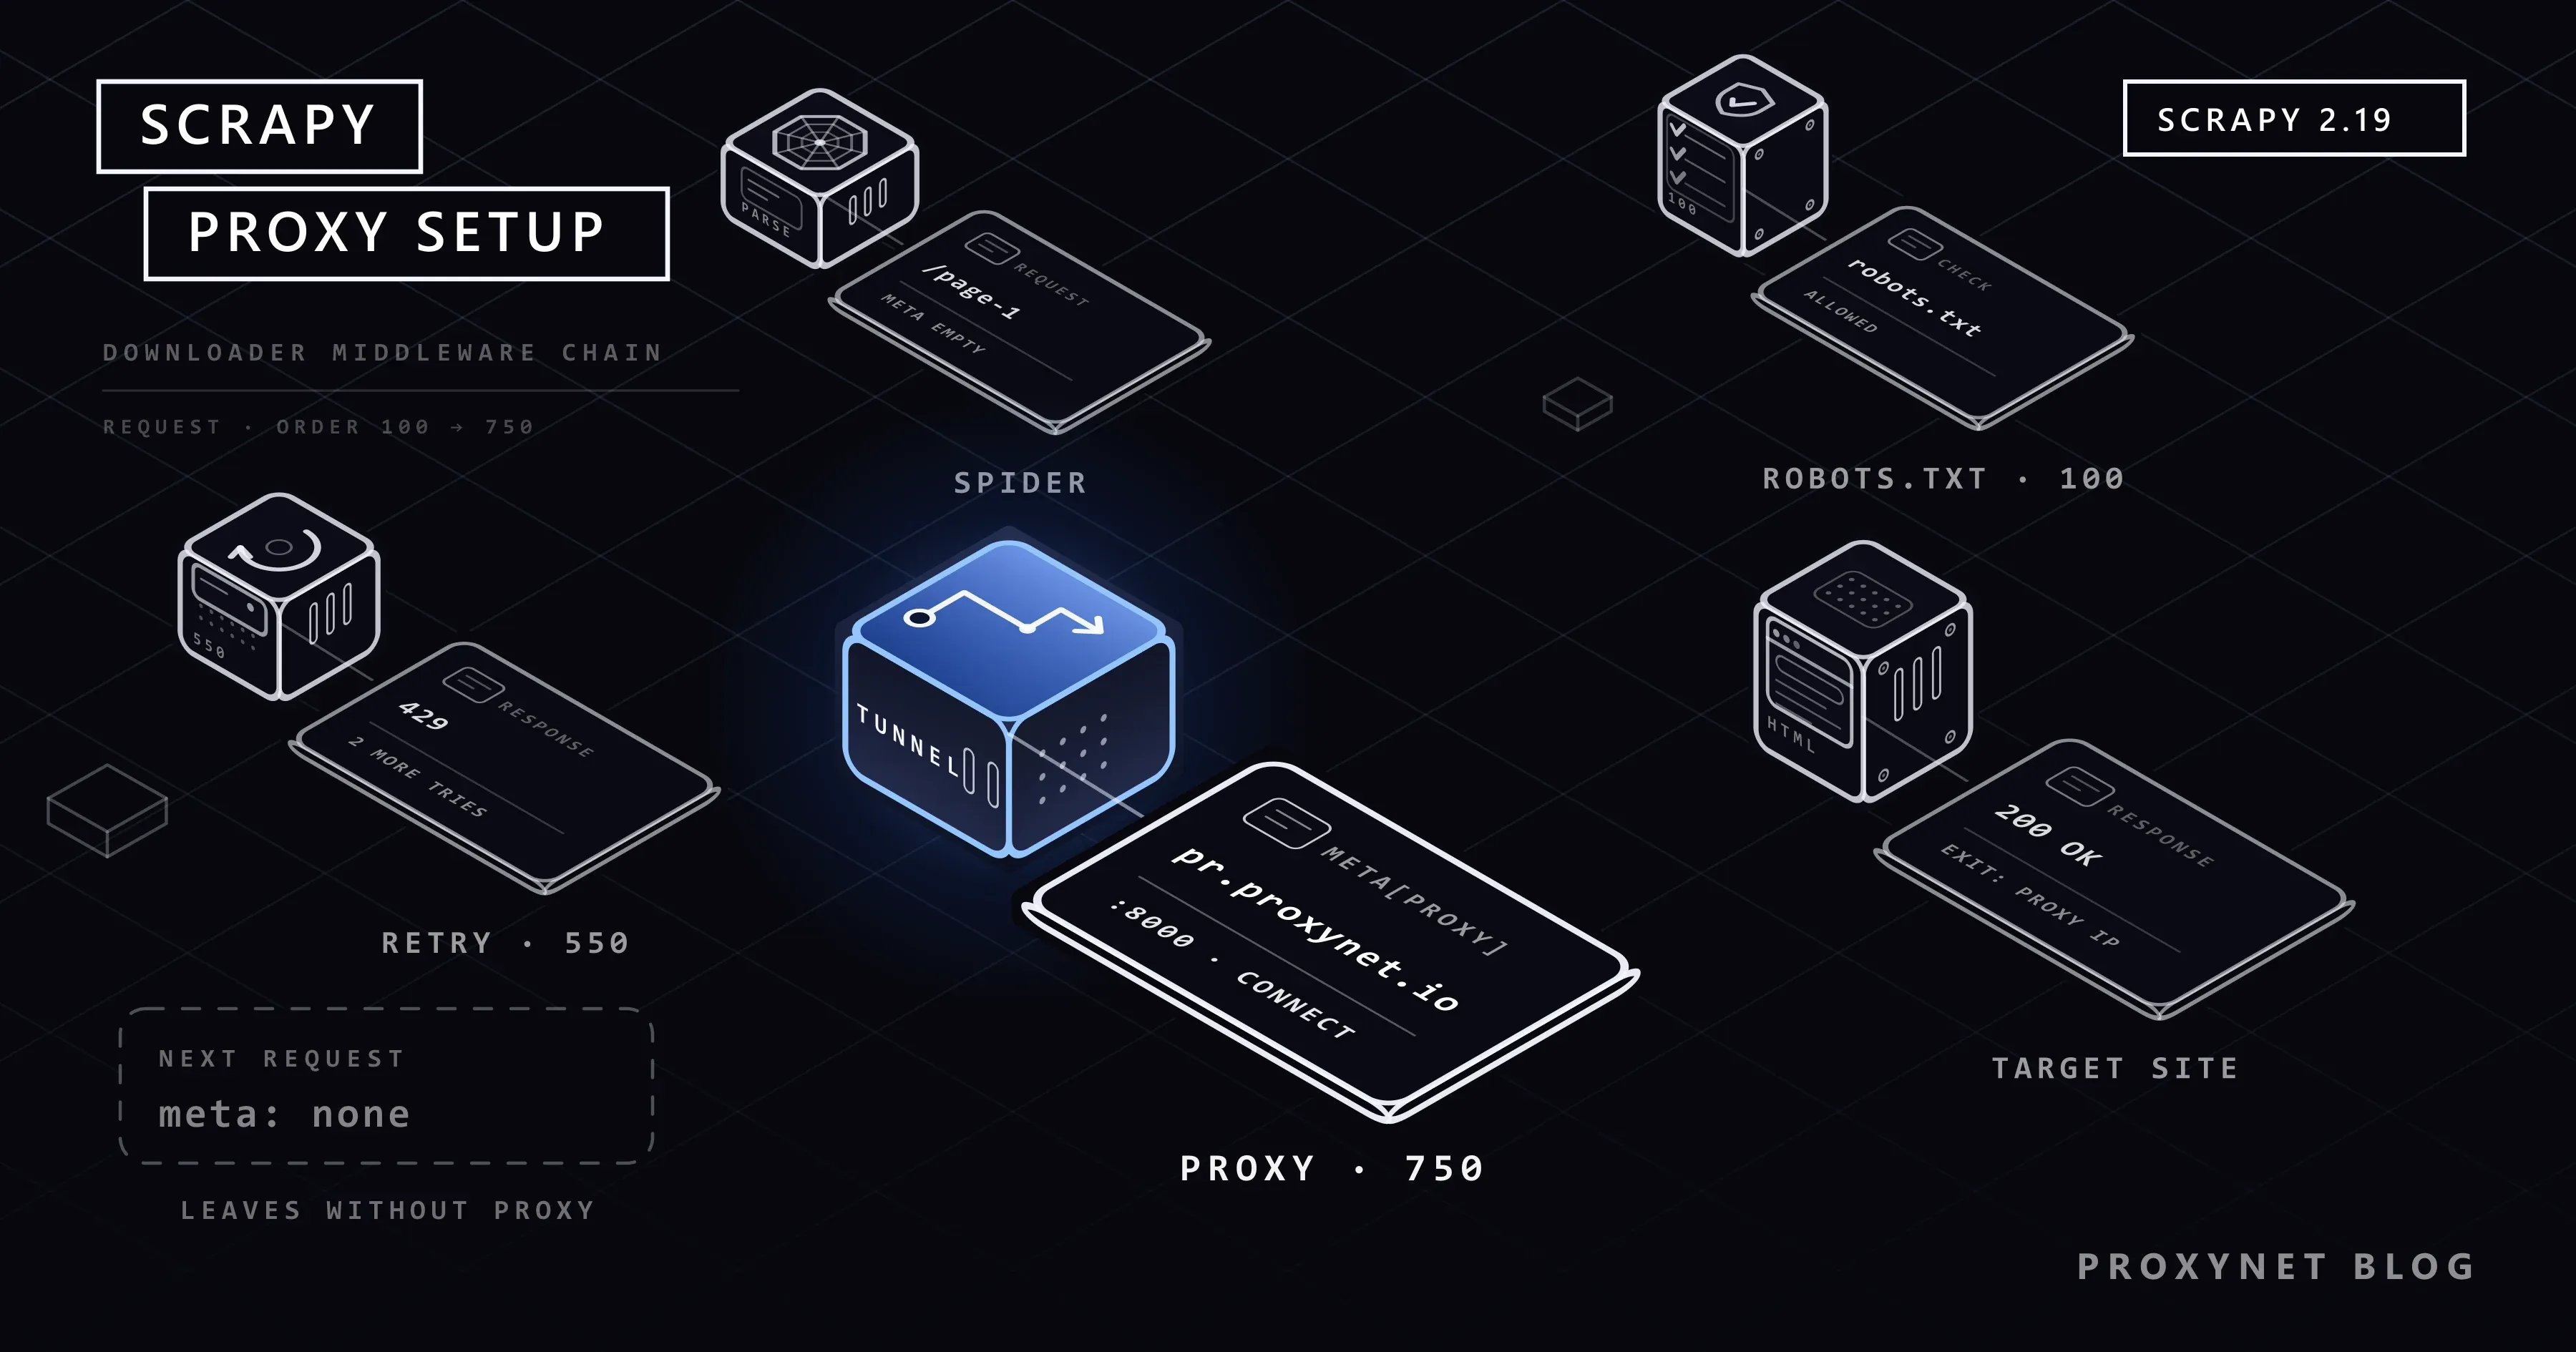
What Is Scrapy and How to Use It With a Proxy
In Scrapy, a proxy is set through the request meta field or a middleware. Setup, authentication, AutoThrottle settings and rotation, explained with code.
Written by:Acar Diveroli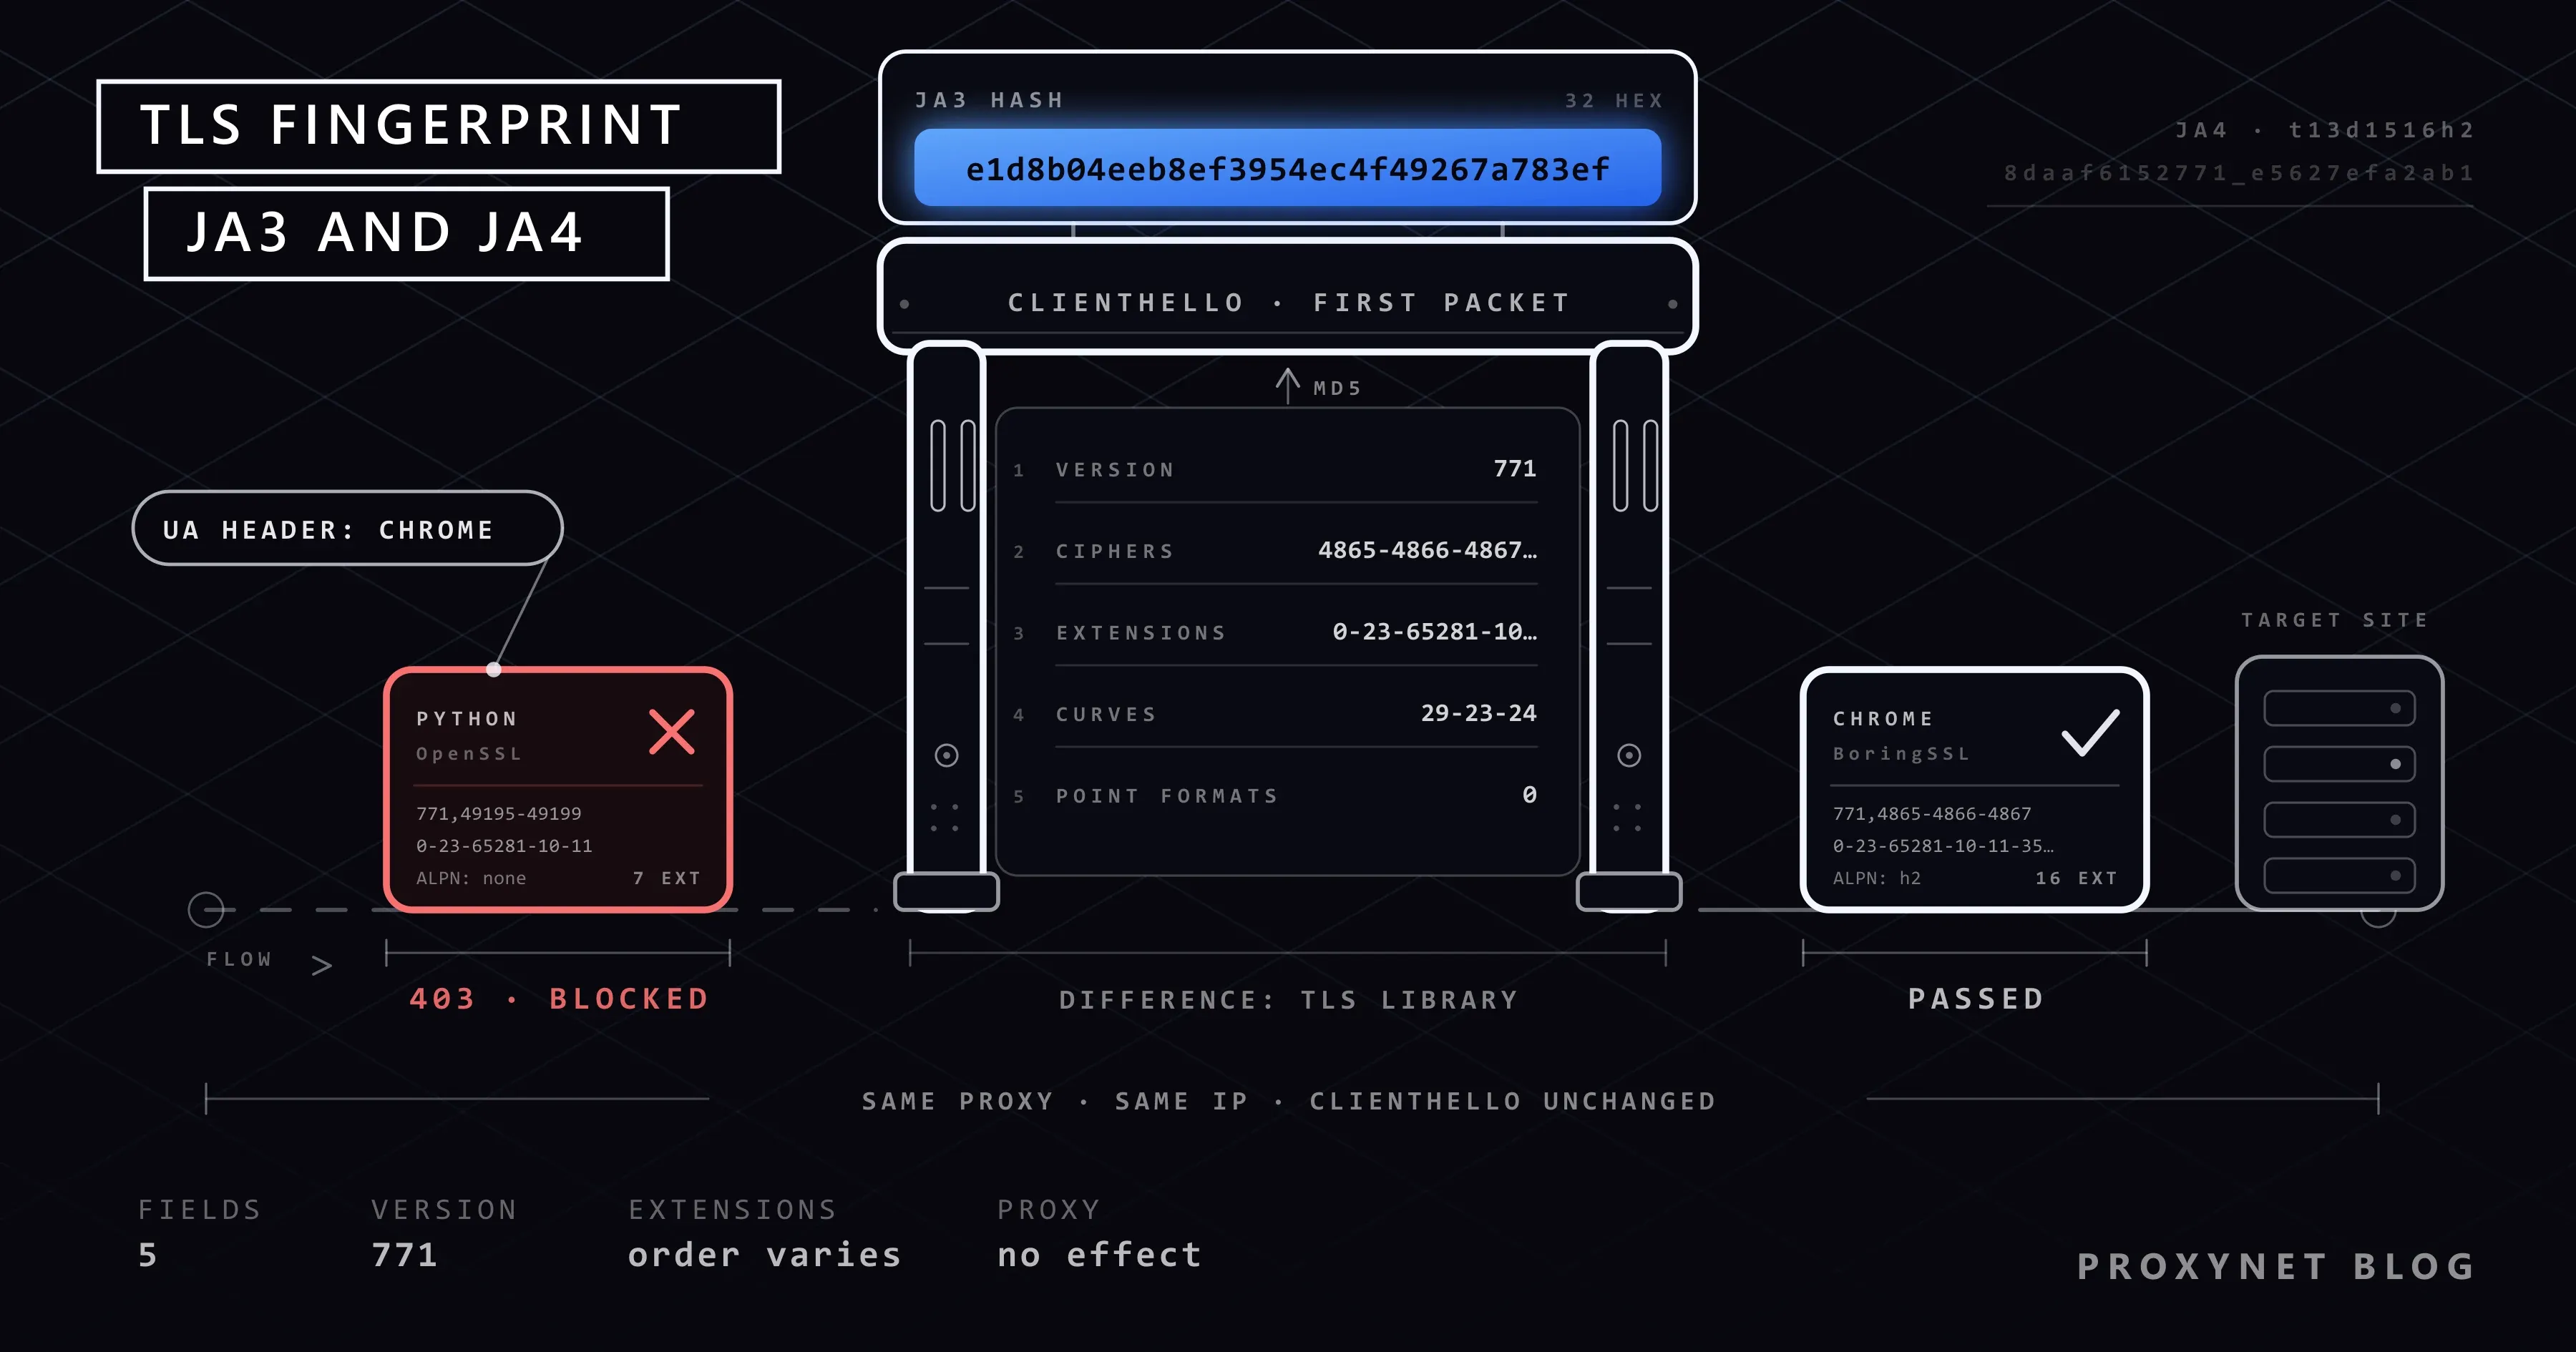
Published
What Is TLS Fingerprinting and JA3? How It Works
A TLS fingerprint is an identifier built from the cipher and extension lists in a client's ClientHello. How JA3 and JA4 are computed, and what a proxy changes.
Written by:Acar Diveroli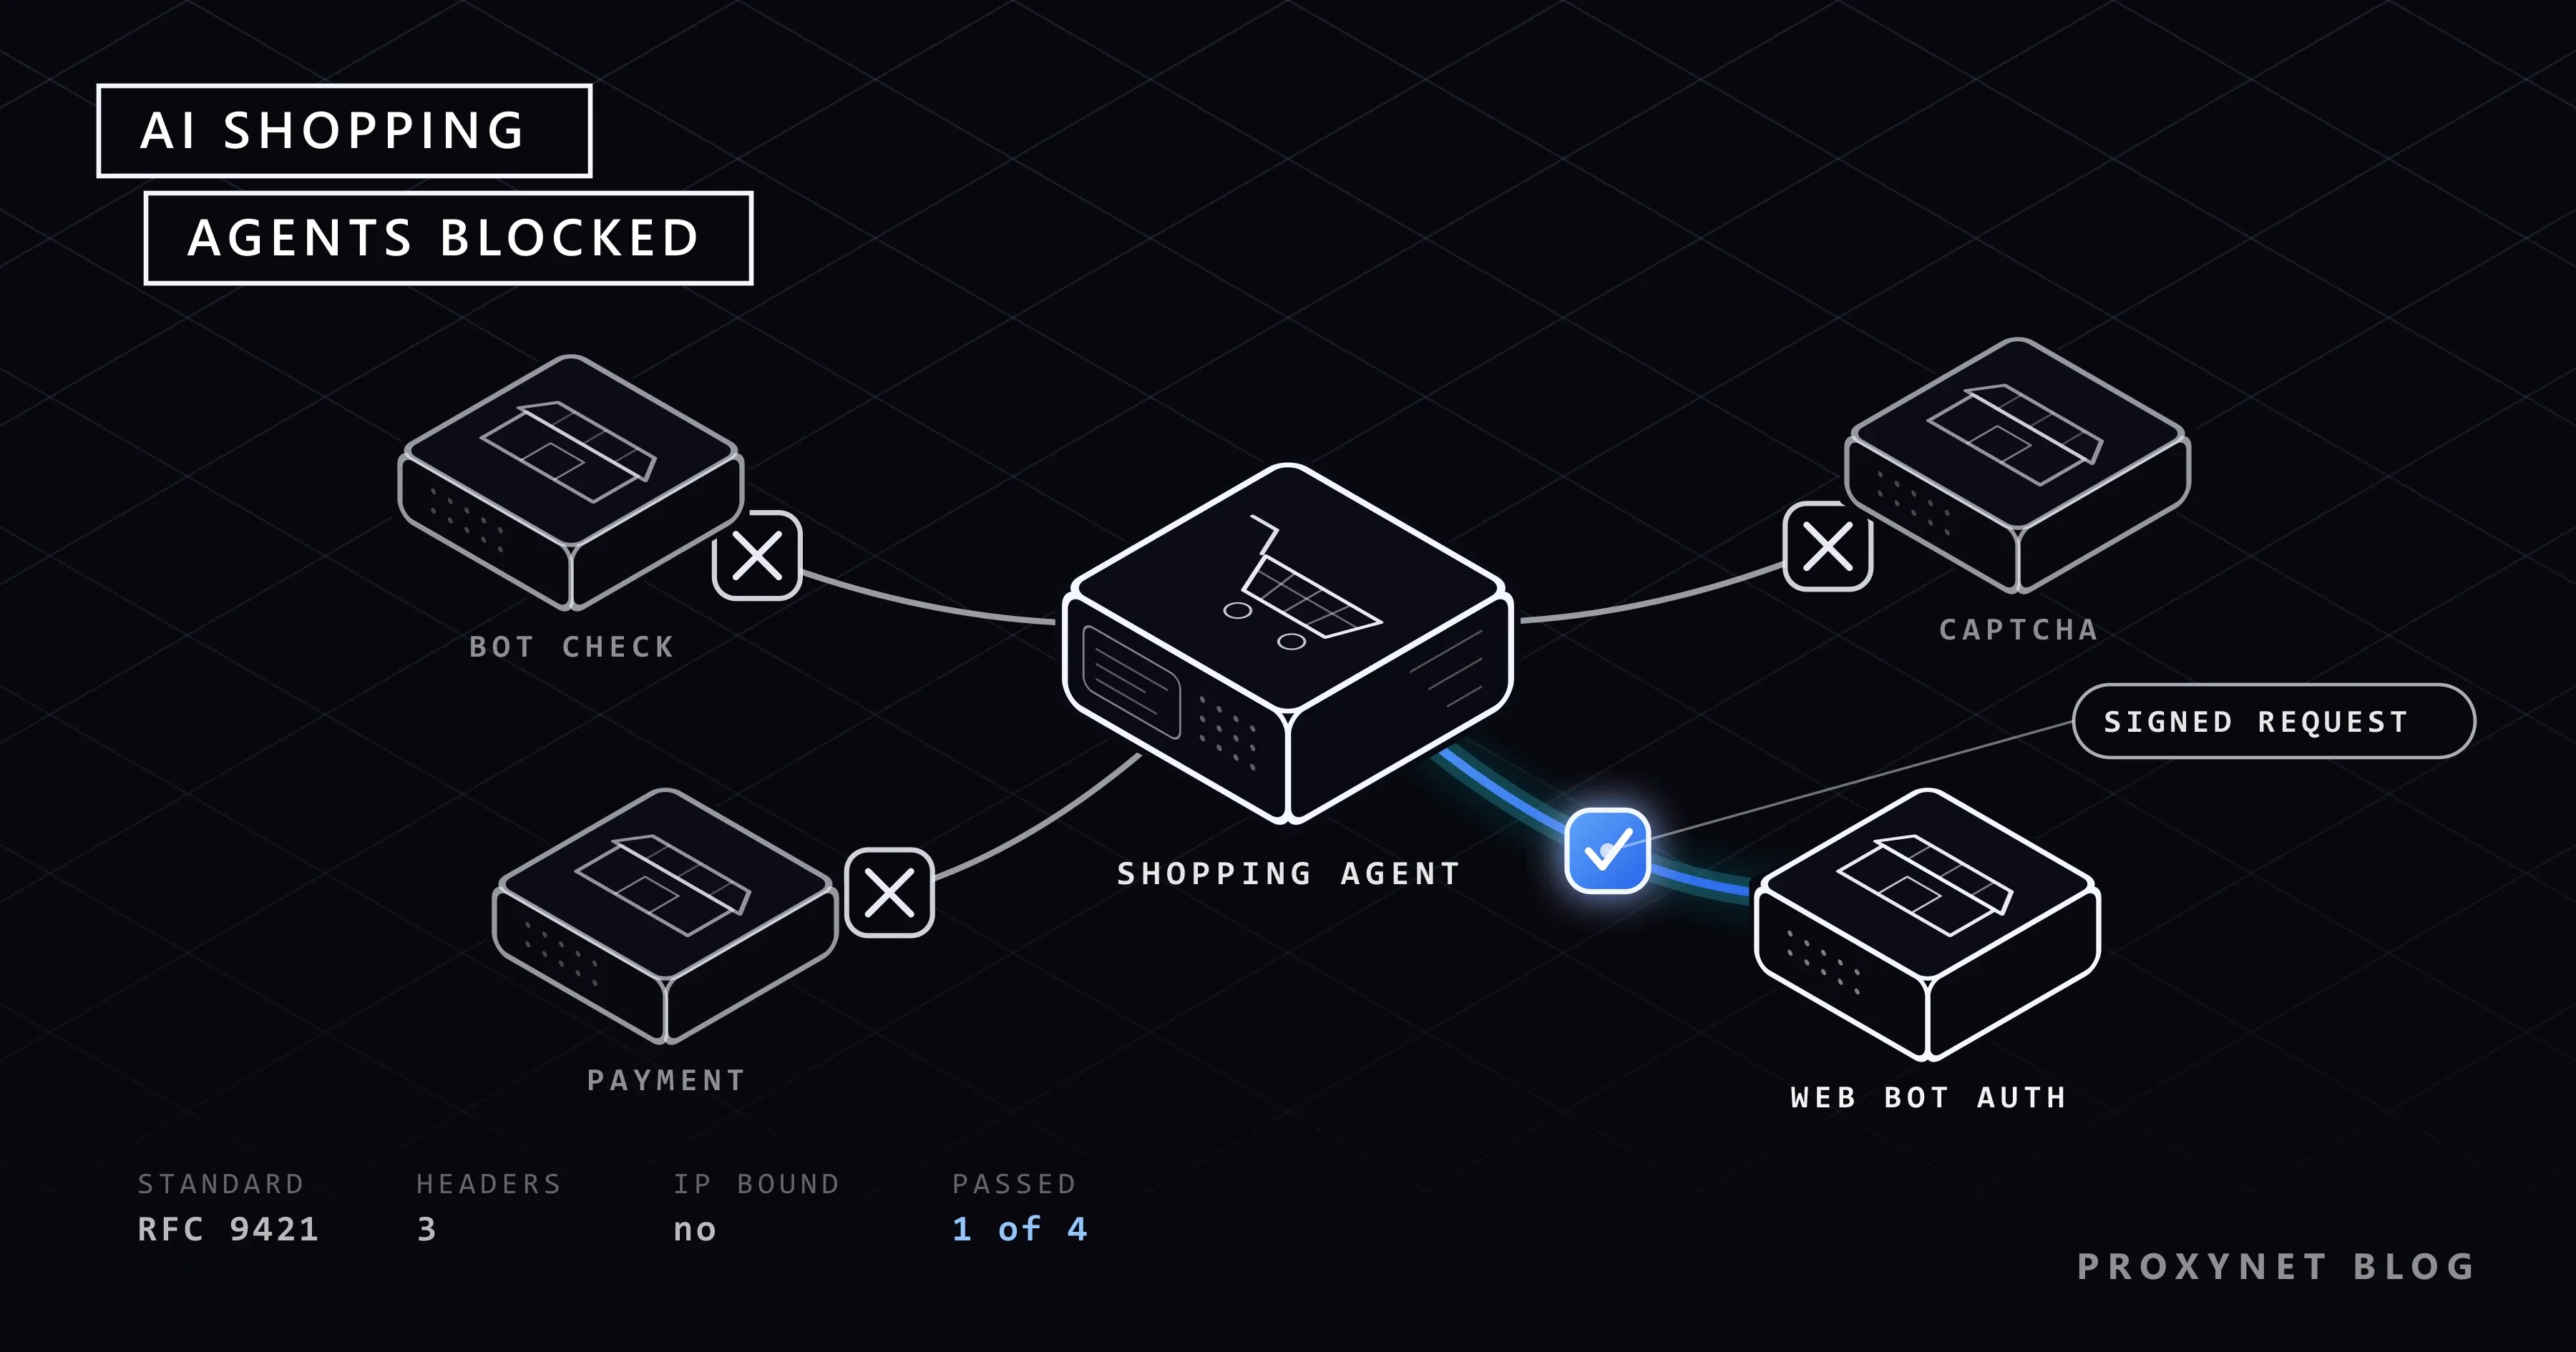
Published
Why Are AI Shopping Agents Blocked on Websites?
Shopping agents hit bot protection because sites can't tell a human from an authorised agent. We explain why, and new fixes such as signed agents.
Written by:Acar Diveroli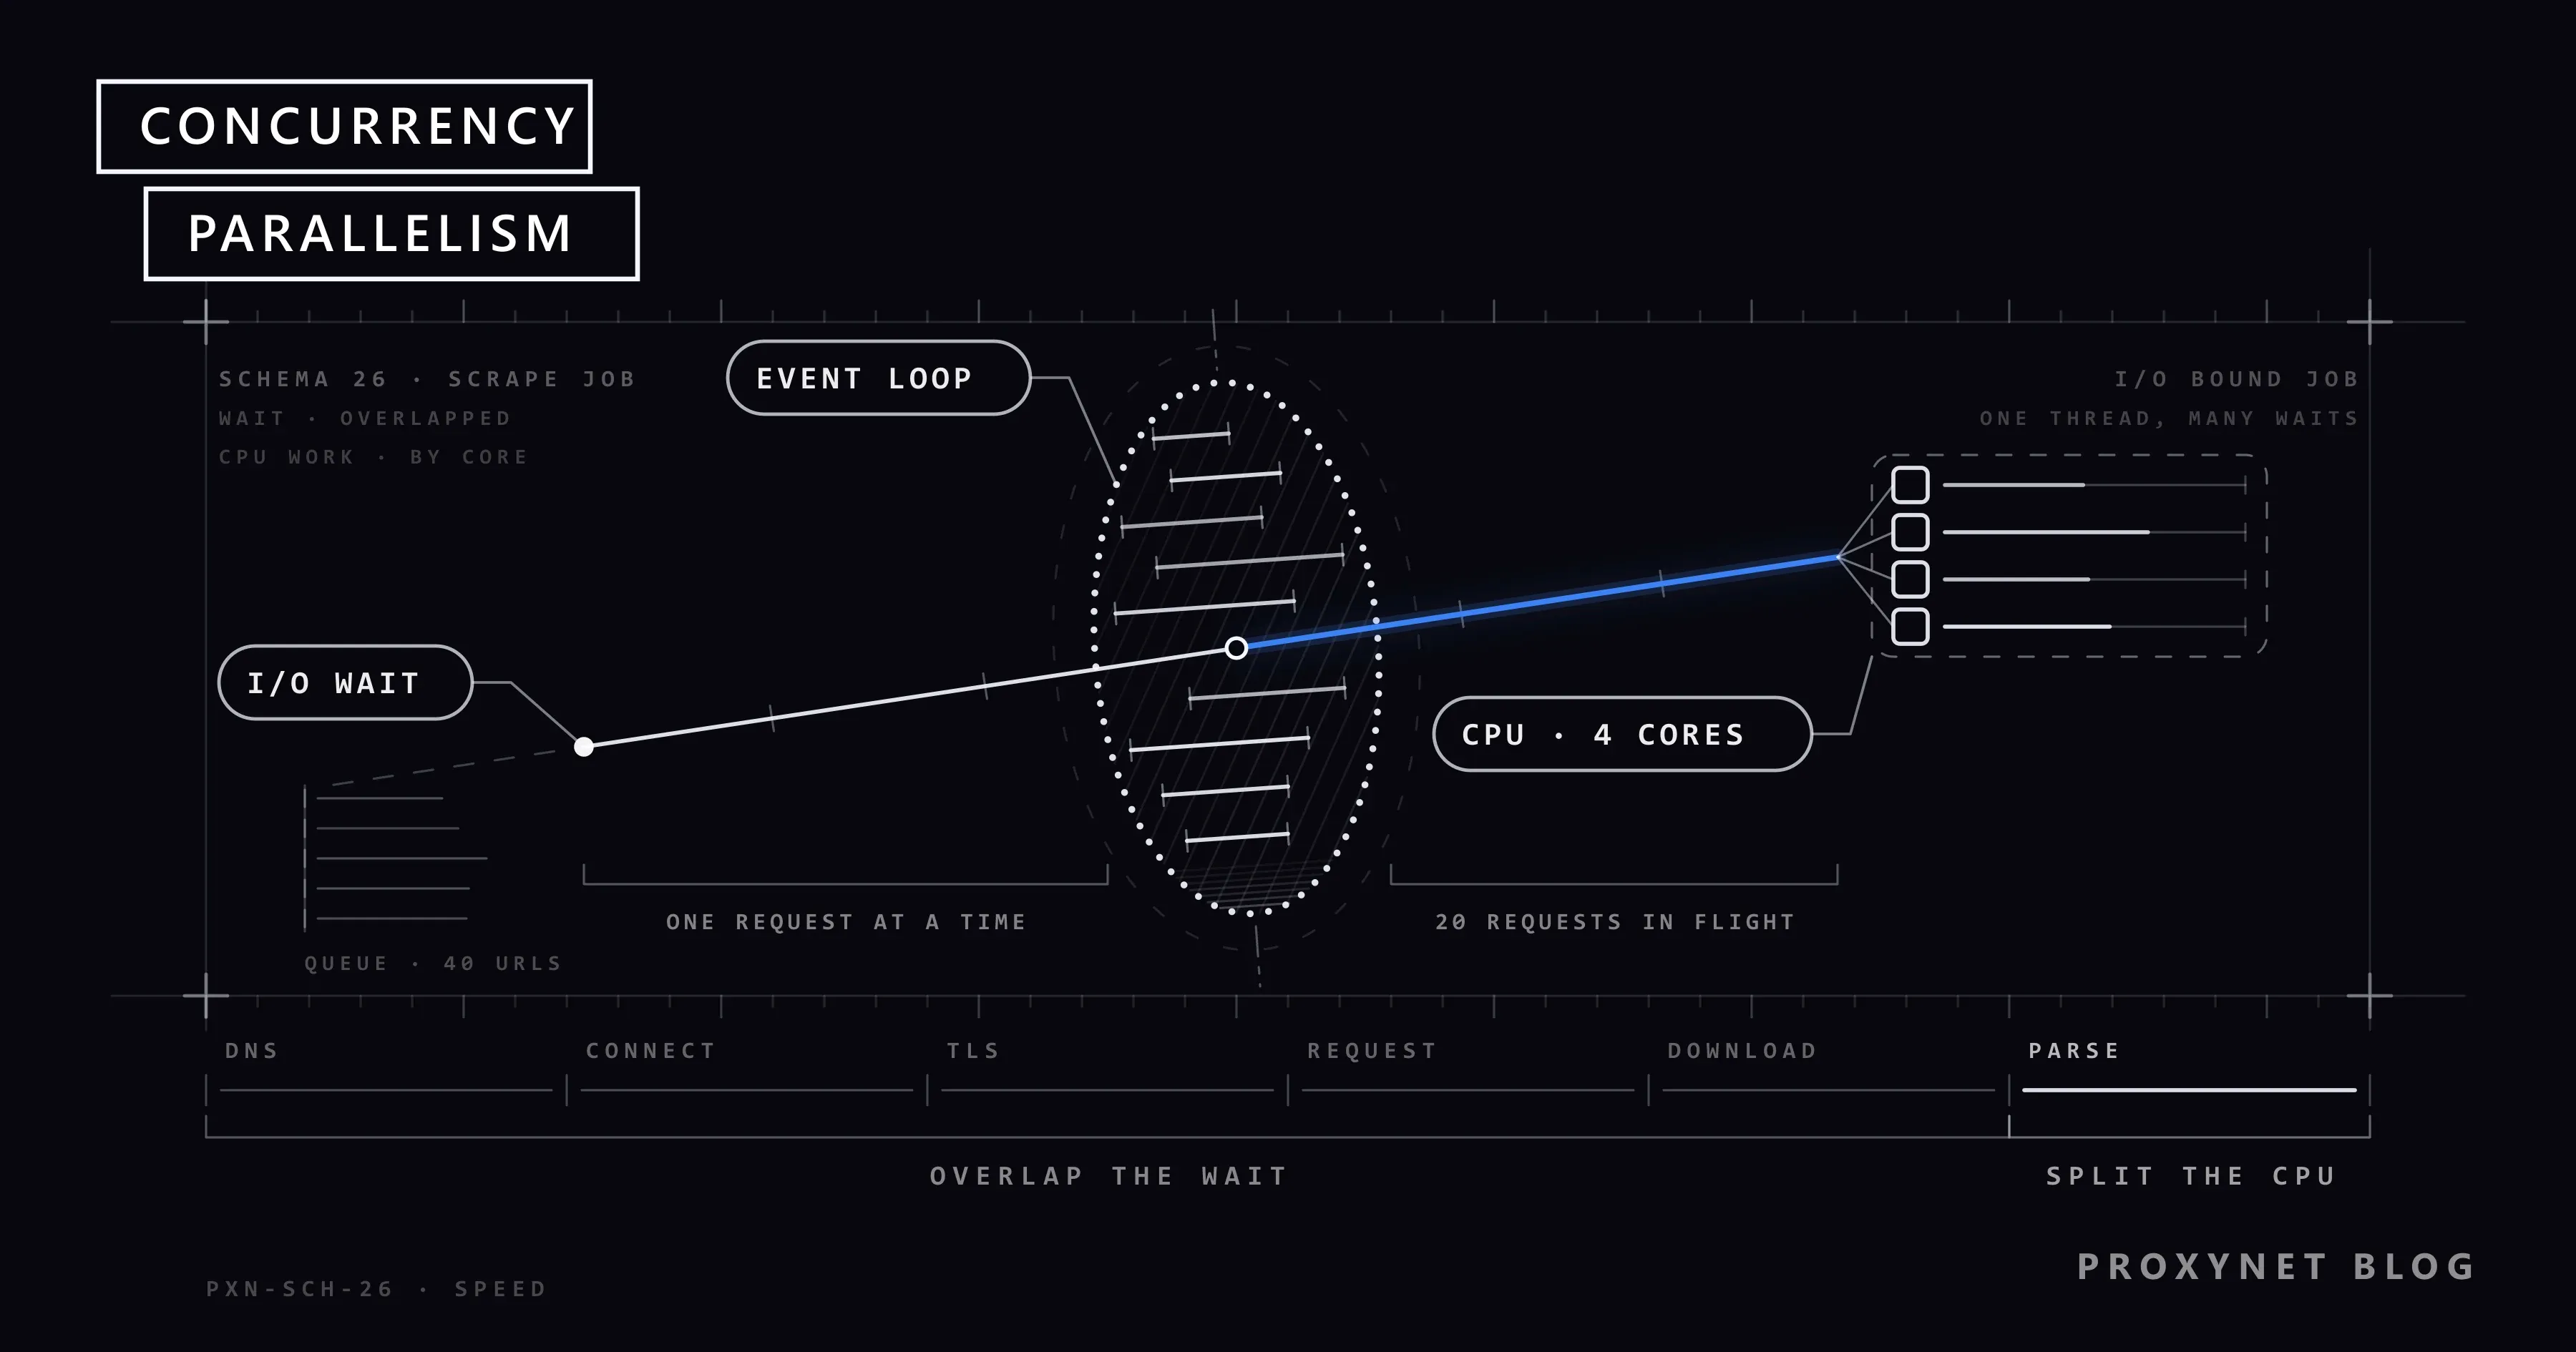
Published
Concurrency vs Parallelism: What Sets Scraping Speed?
Concurrency makes use of waiting time, parallelism makes use of CPU power. We explain which one speeds up scraping, with Python and Node.js examples.
Written by:Acar Diveroli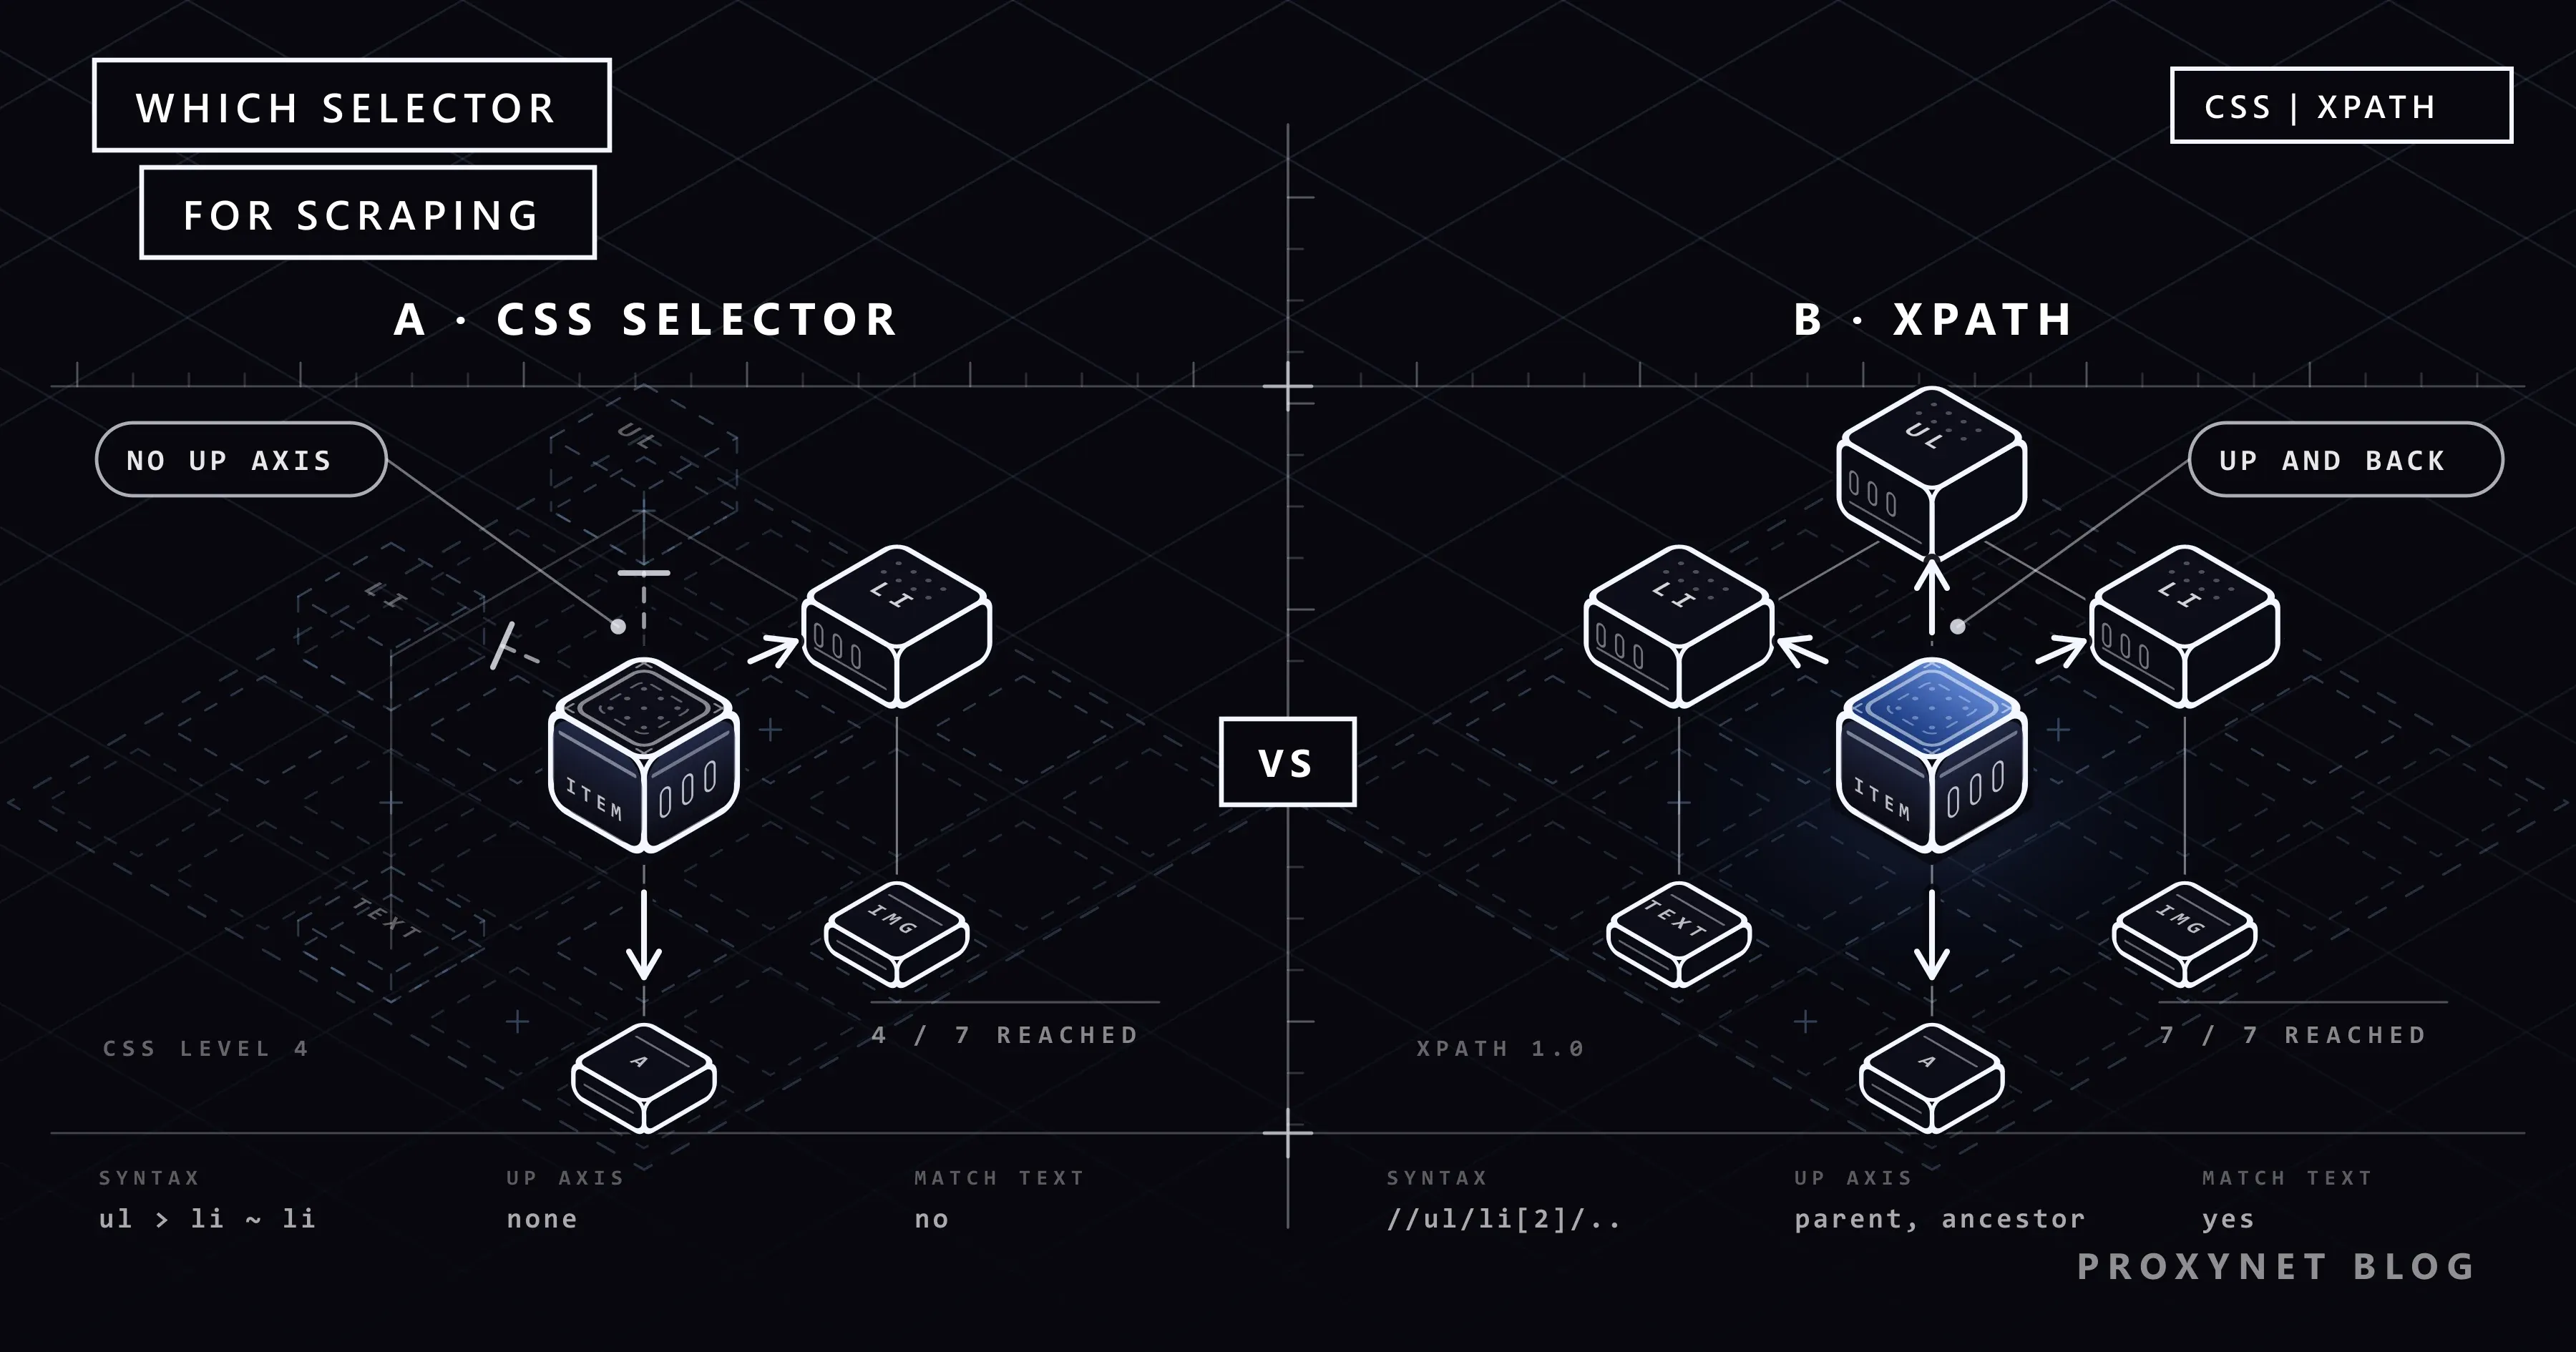
Published
CSS Selector vs XPath: Which One for Web Scraping?
CSS selectors are short and readable, while XPath can also select by text and parent elements. We compare syntax, speed and Python examples for both methods.
Written by:Acar Diveroli
Published
Web Scraping with GPT-6 Astra: What Changed?
GPT-6 Astra improves page understanding and browser control, but it does not solve blocks, CAPTCHAs, or rate limits. Its real place in a scraping flow.
Written by:Acar Diveroli
Published
What Are Honeypot Traps and How Do They Affect Scraping?
Honeypots are hidden links that visitors never see but bots get caught on. We explain how they work and how they flag a scraper, without teaching evasion.
Written by:Acar Diveroli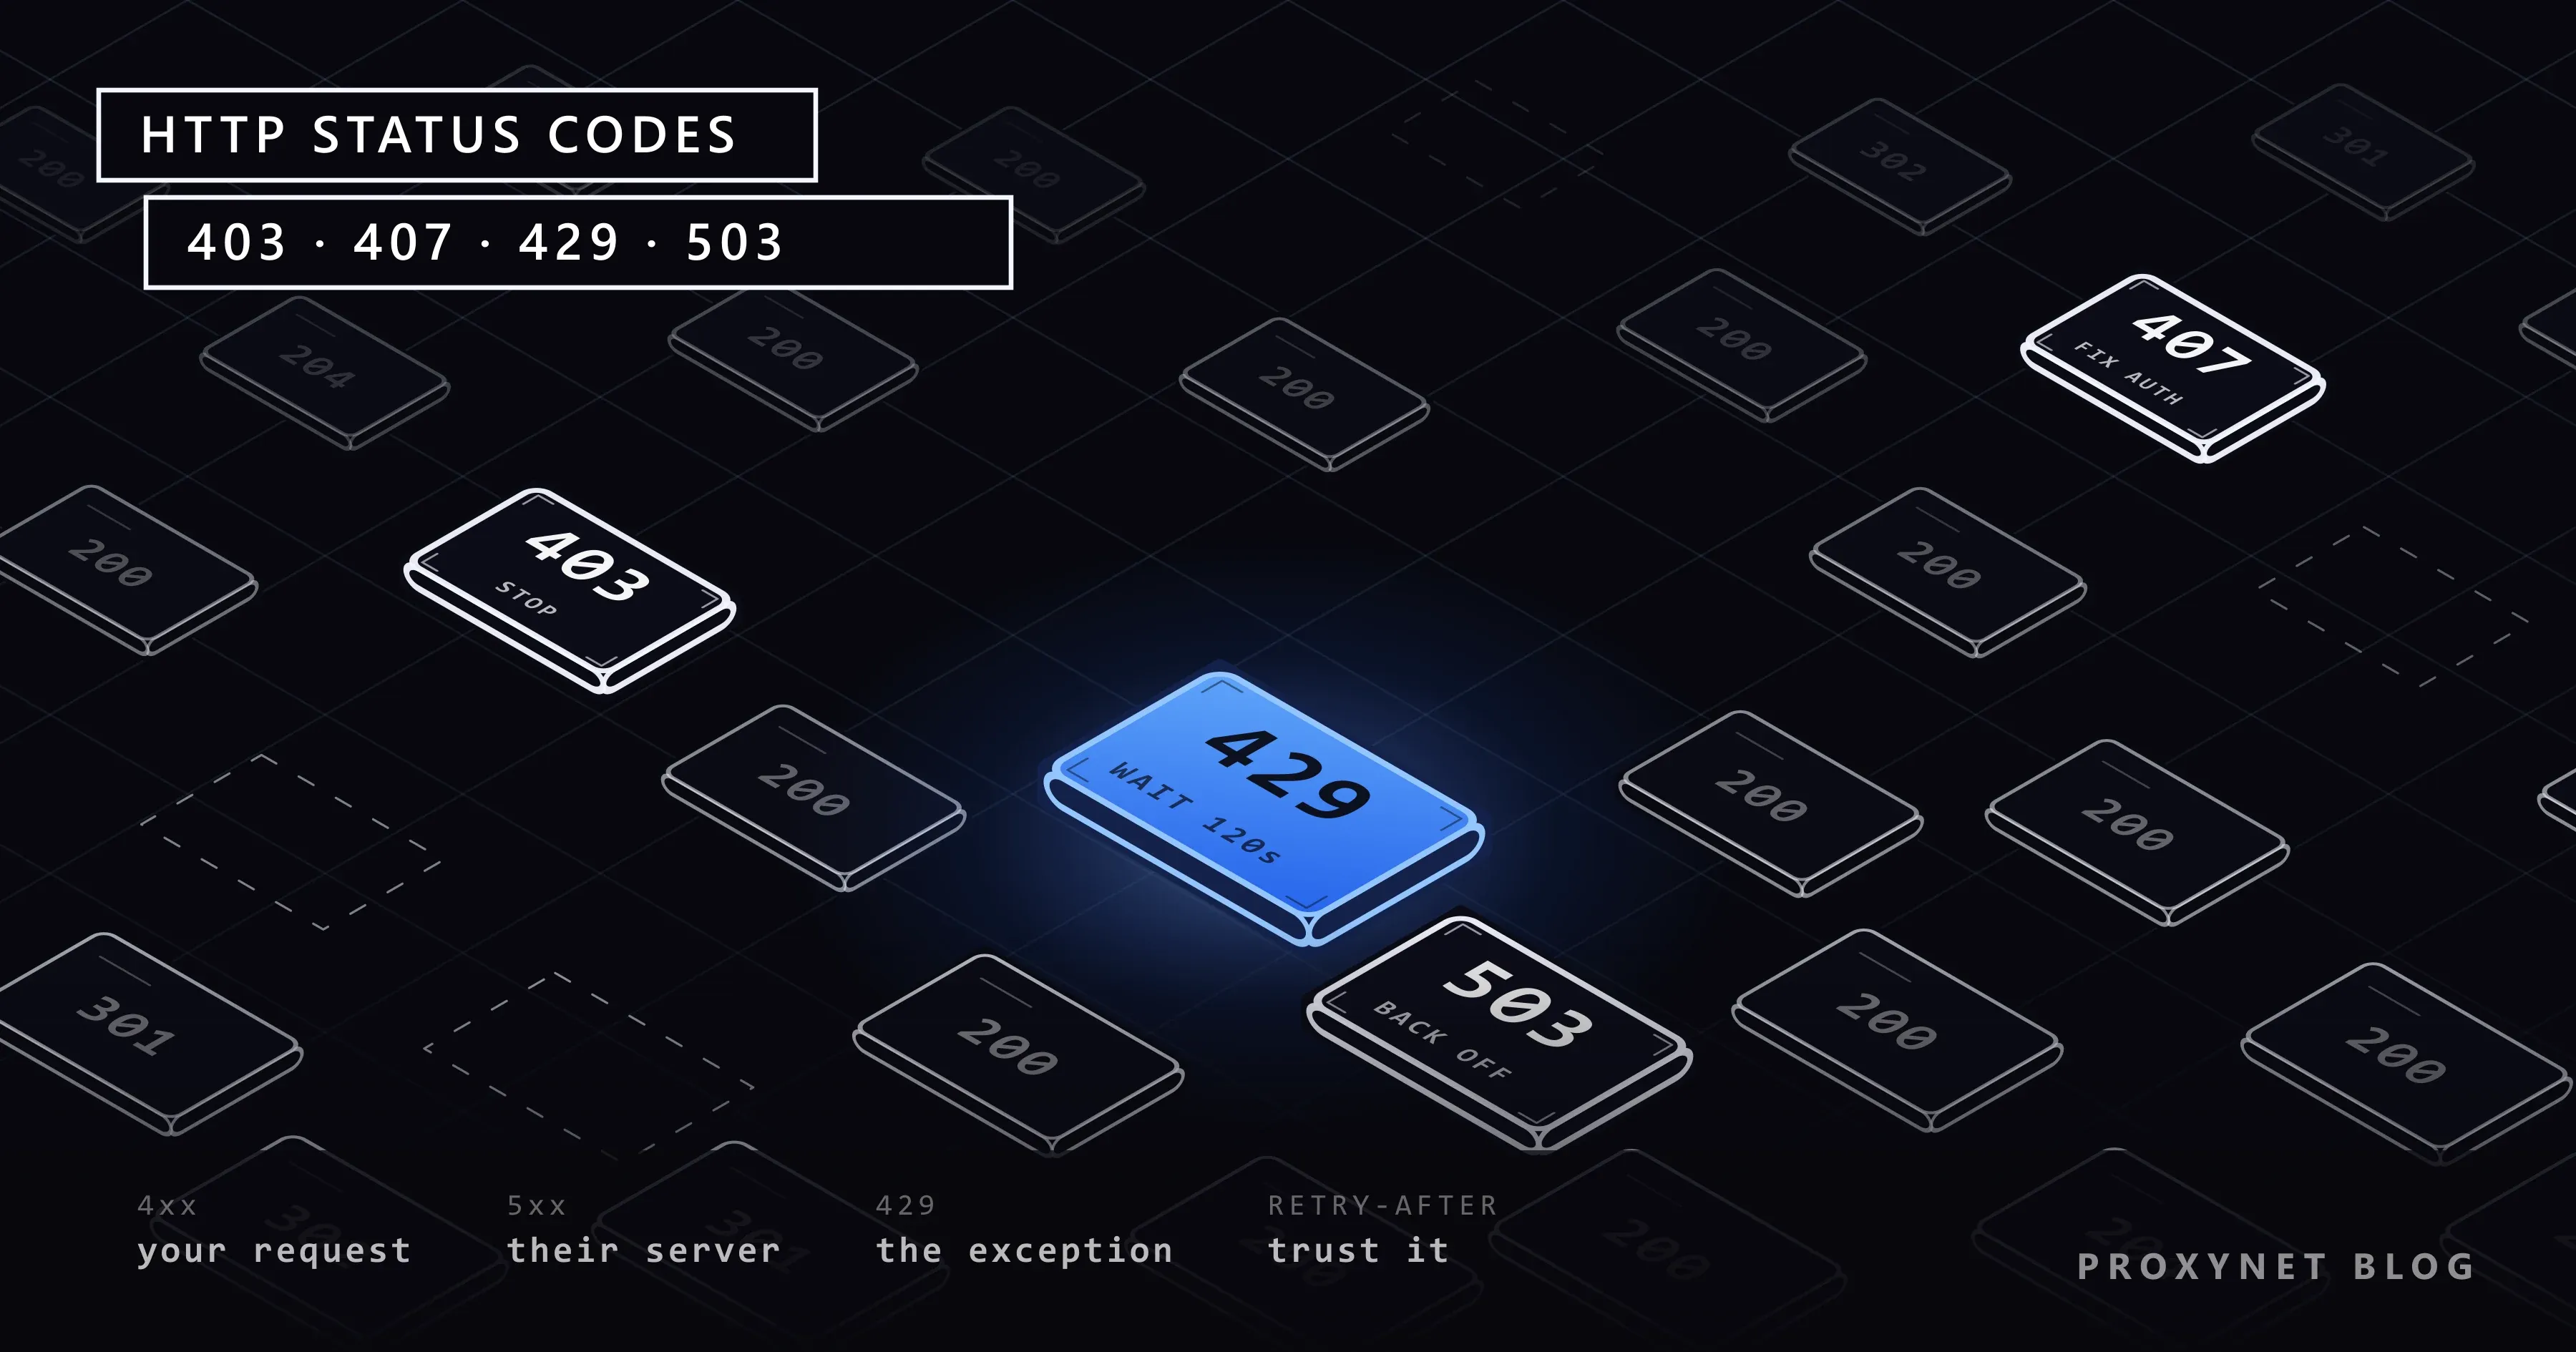
Published
HTTP Status Codes in Web Scraping: 403, 407, 429, 503
403, 407, 429 and 503 responses point to different problems in scraping. We explain what each code means, its causes and how to retry properly with Retry-After.
Written by:Acar Diveroli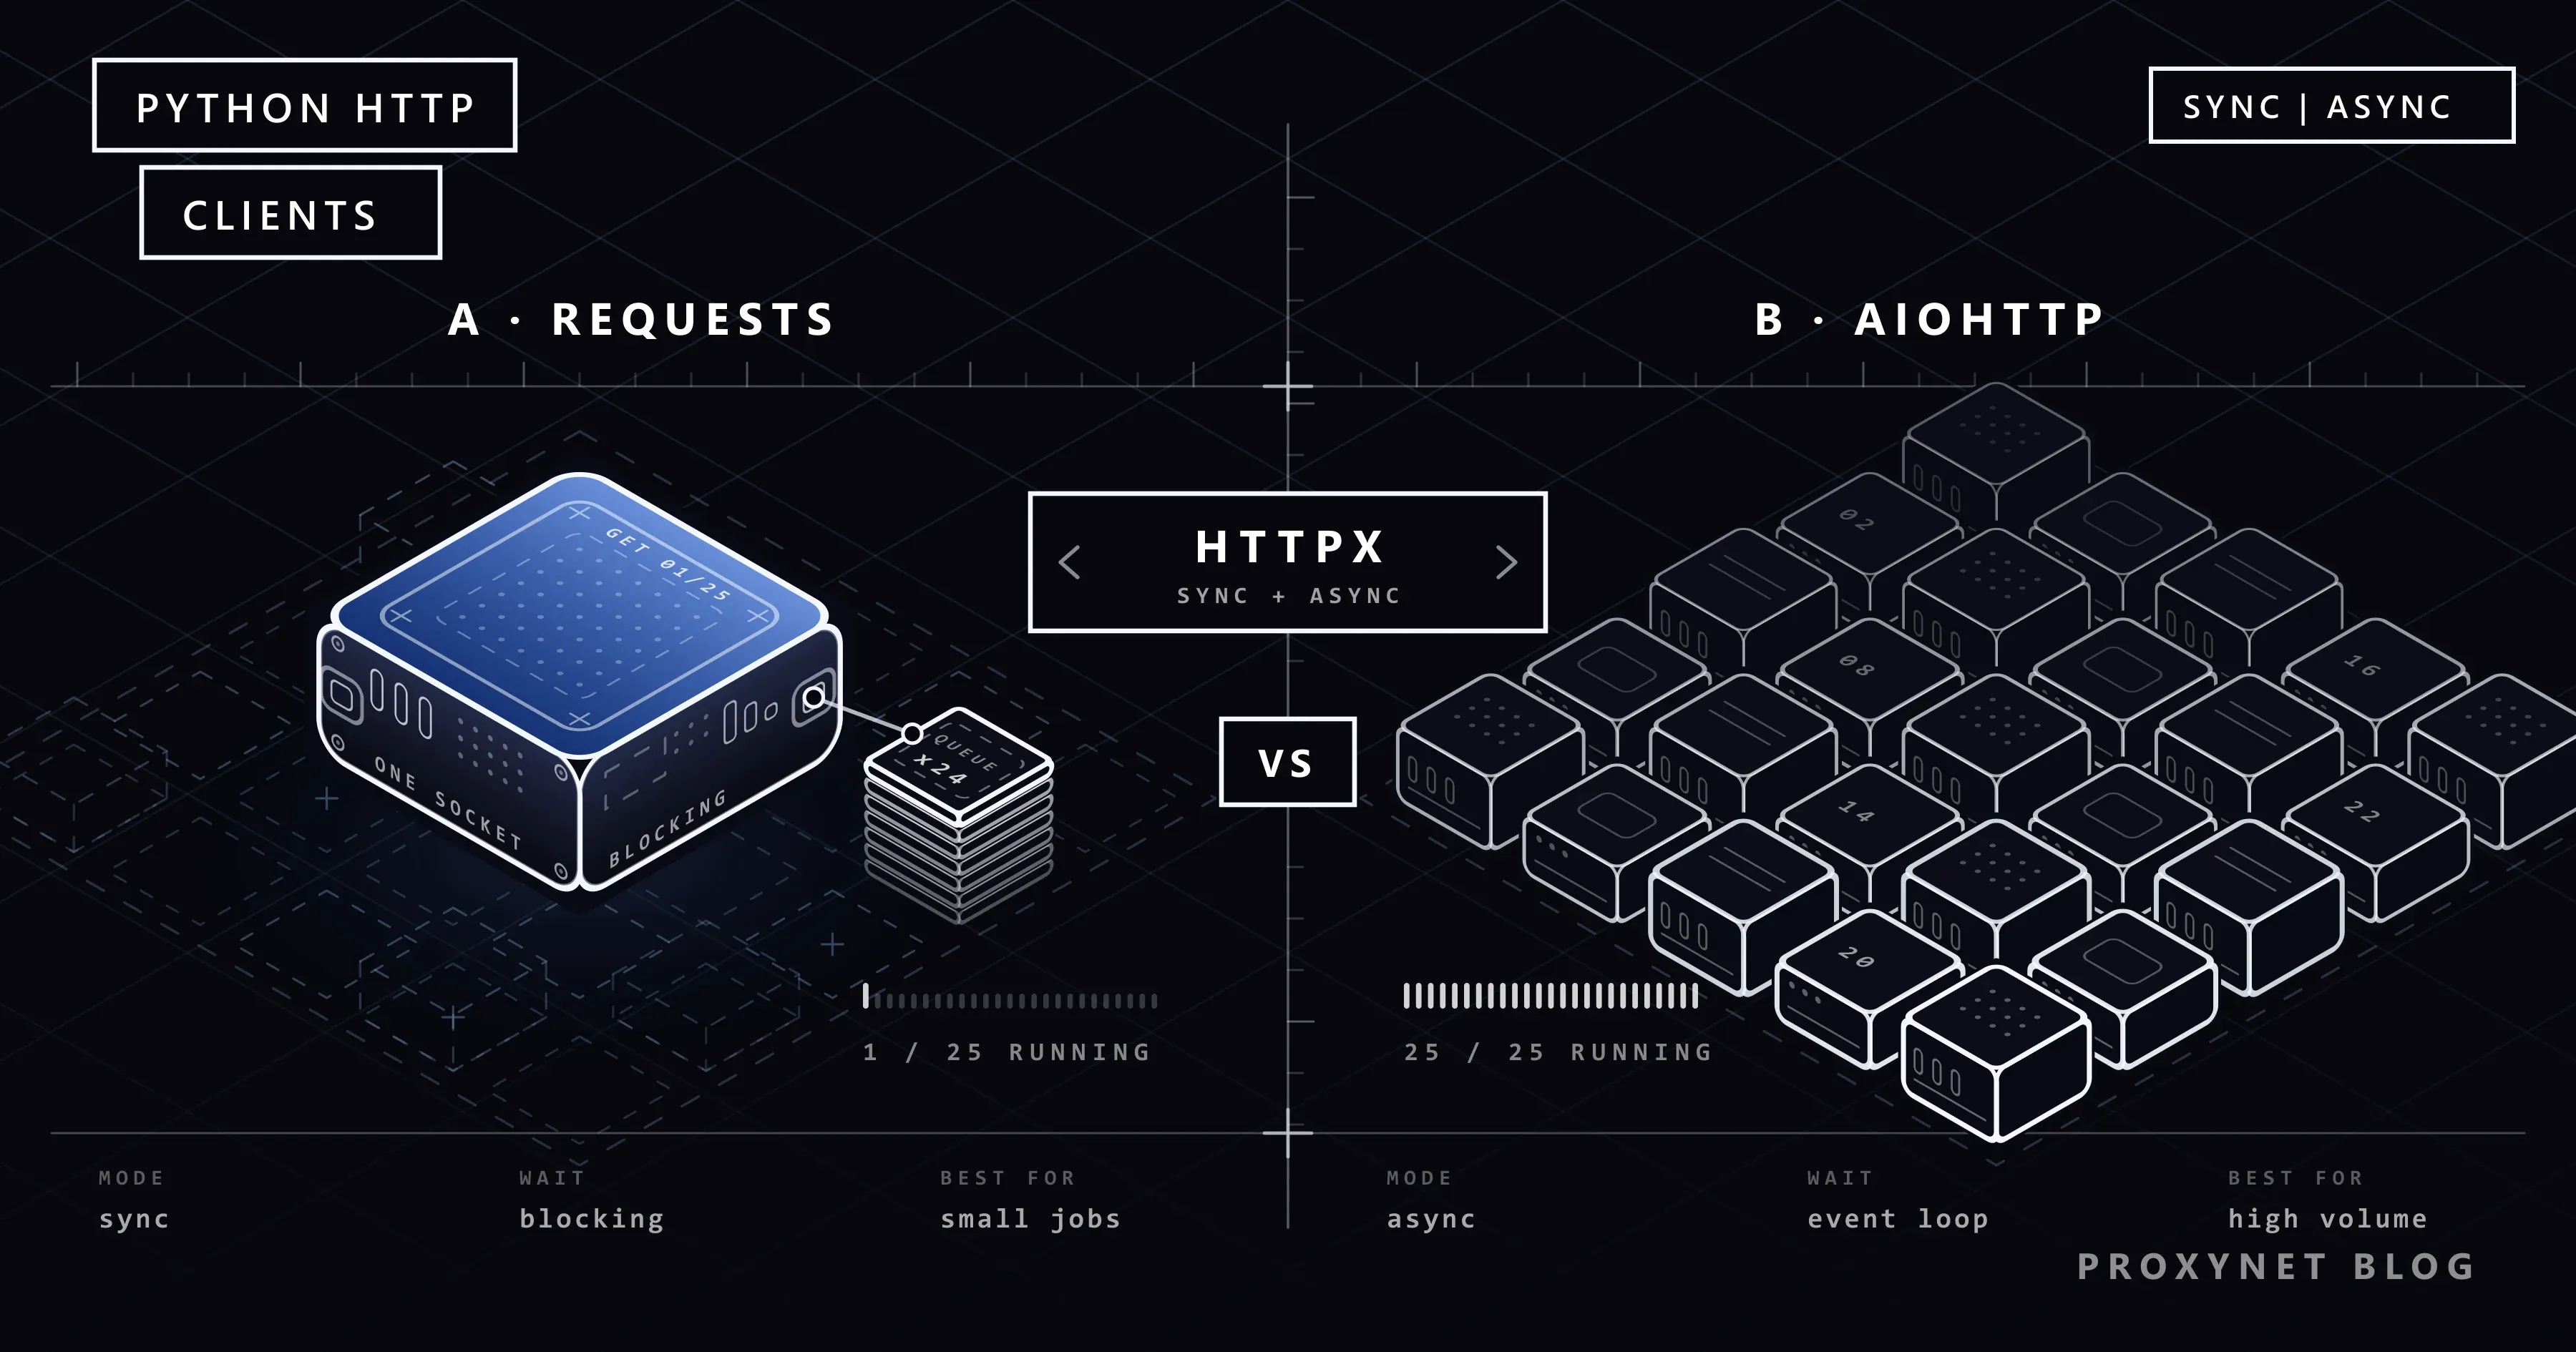
Published
HTTPX vs. Requests vs. AIOHTTP Compared
Requests is simple and synchronous, AIOHTTP is async, and HTTPX offers both. Proxy usage, performance, and which library fits which project, with code examples.
Written by:Acar Diveroli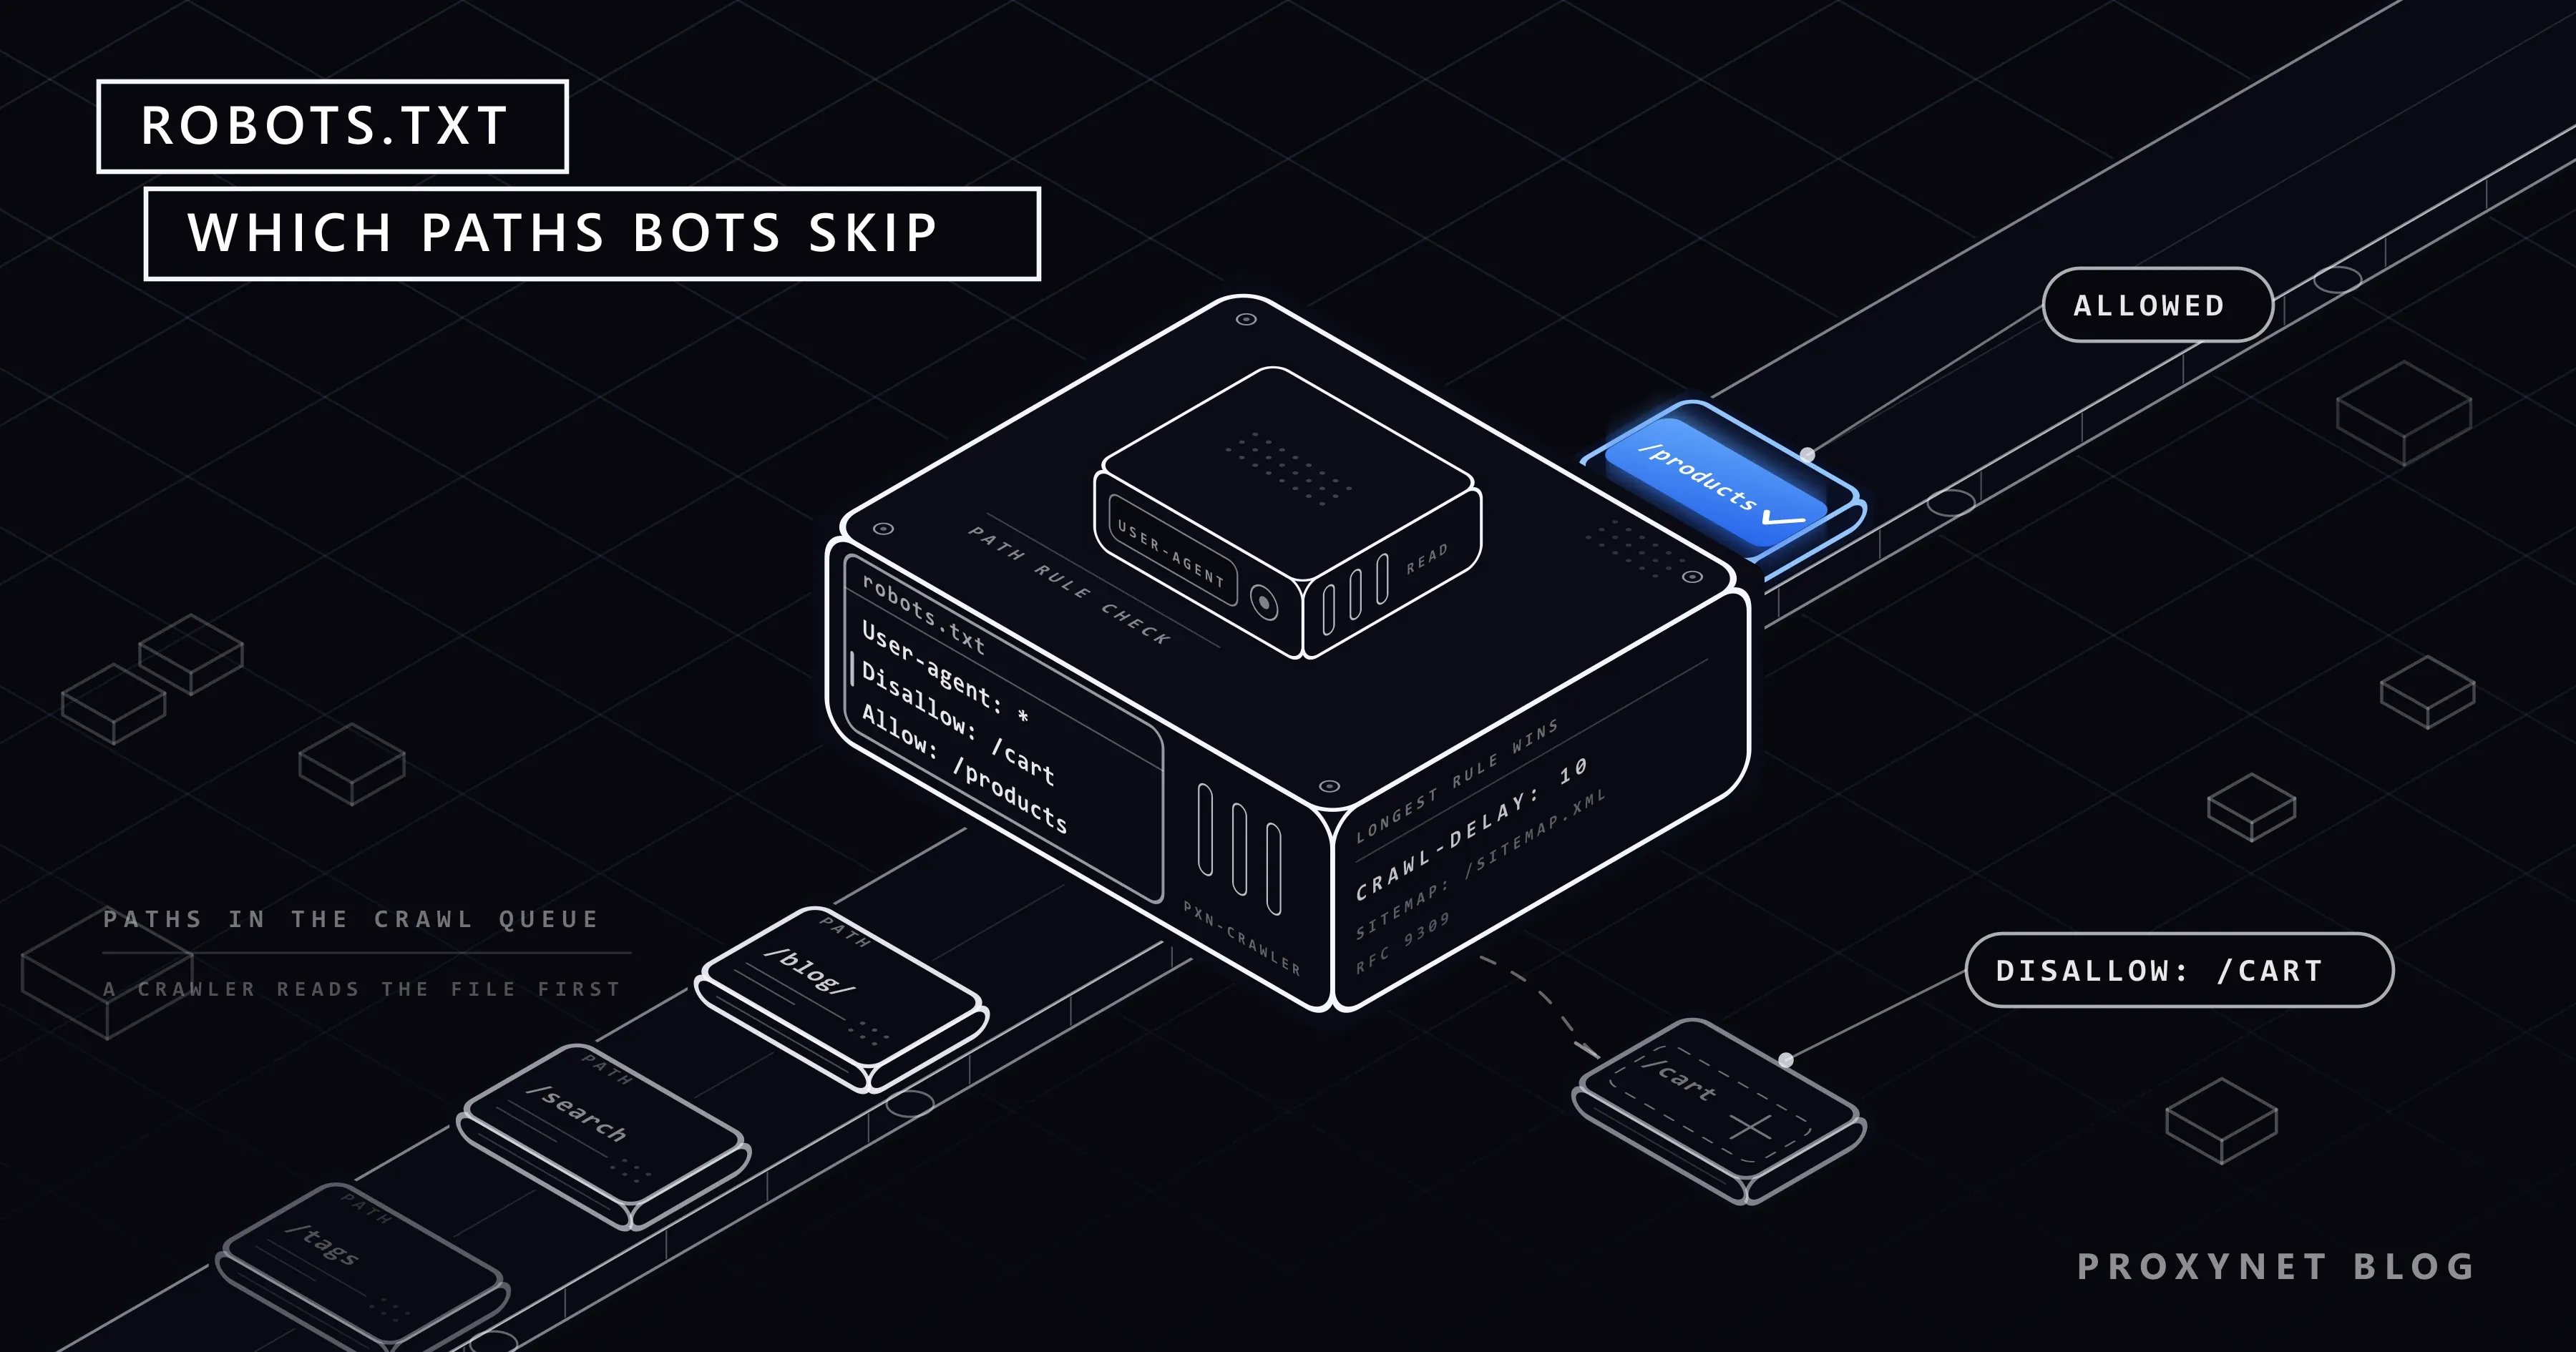
Published
What Is a robots.txt File and How Do You Read It?
robots.txt is the file where a site tells bots which paths not to crawl. We explain the Disallow, Allow and Crawl-delay rules and how to read it with Python.
Written by:Acar Diveroli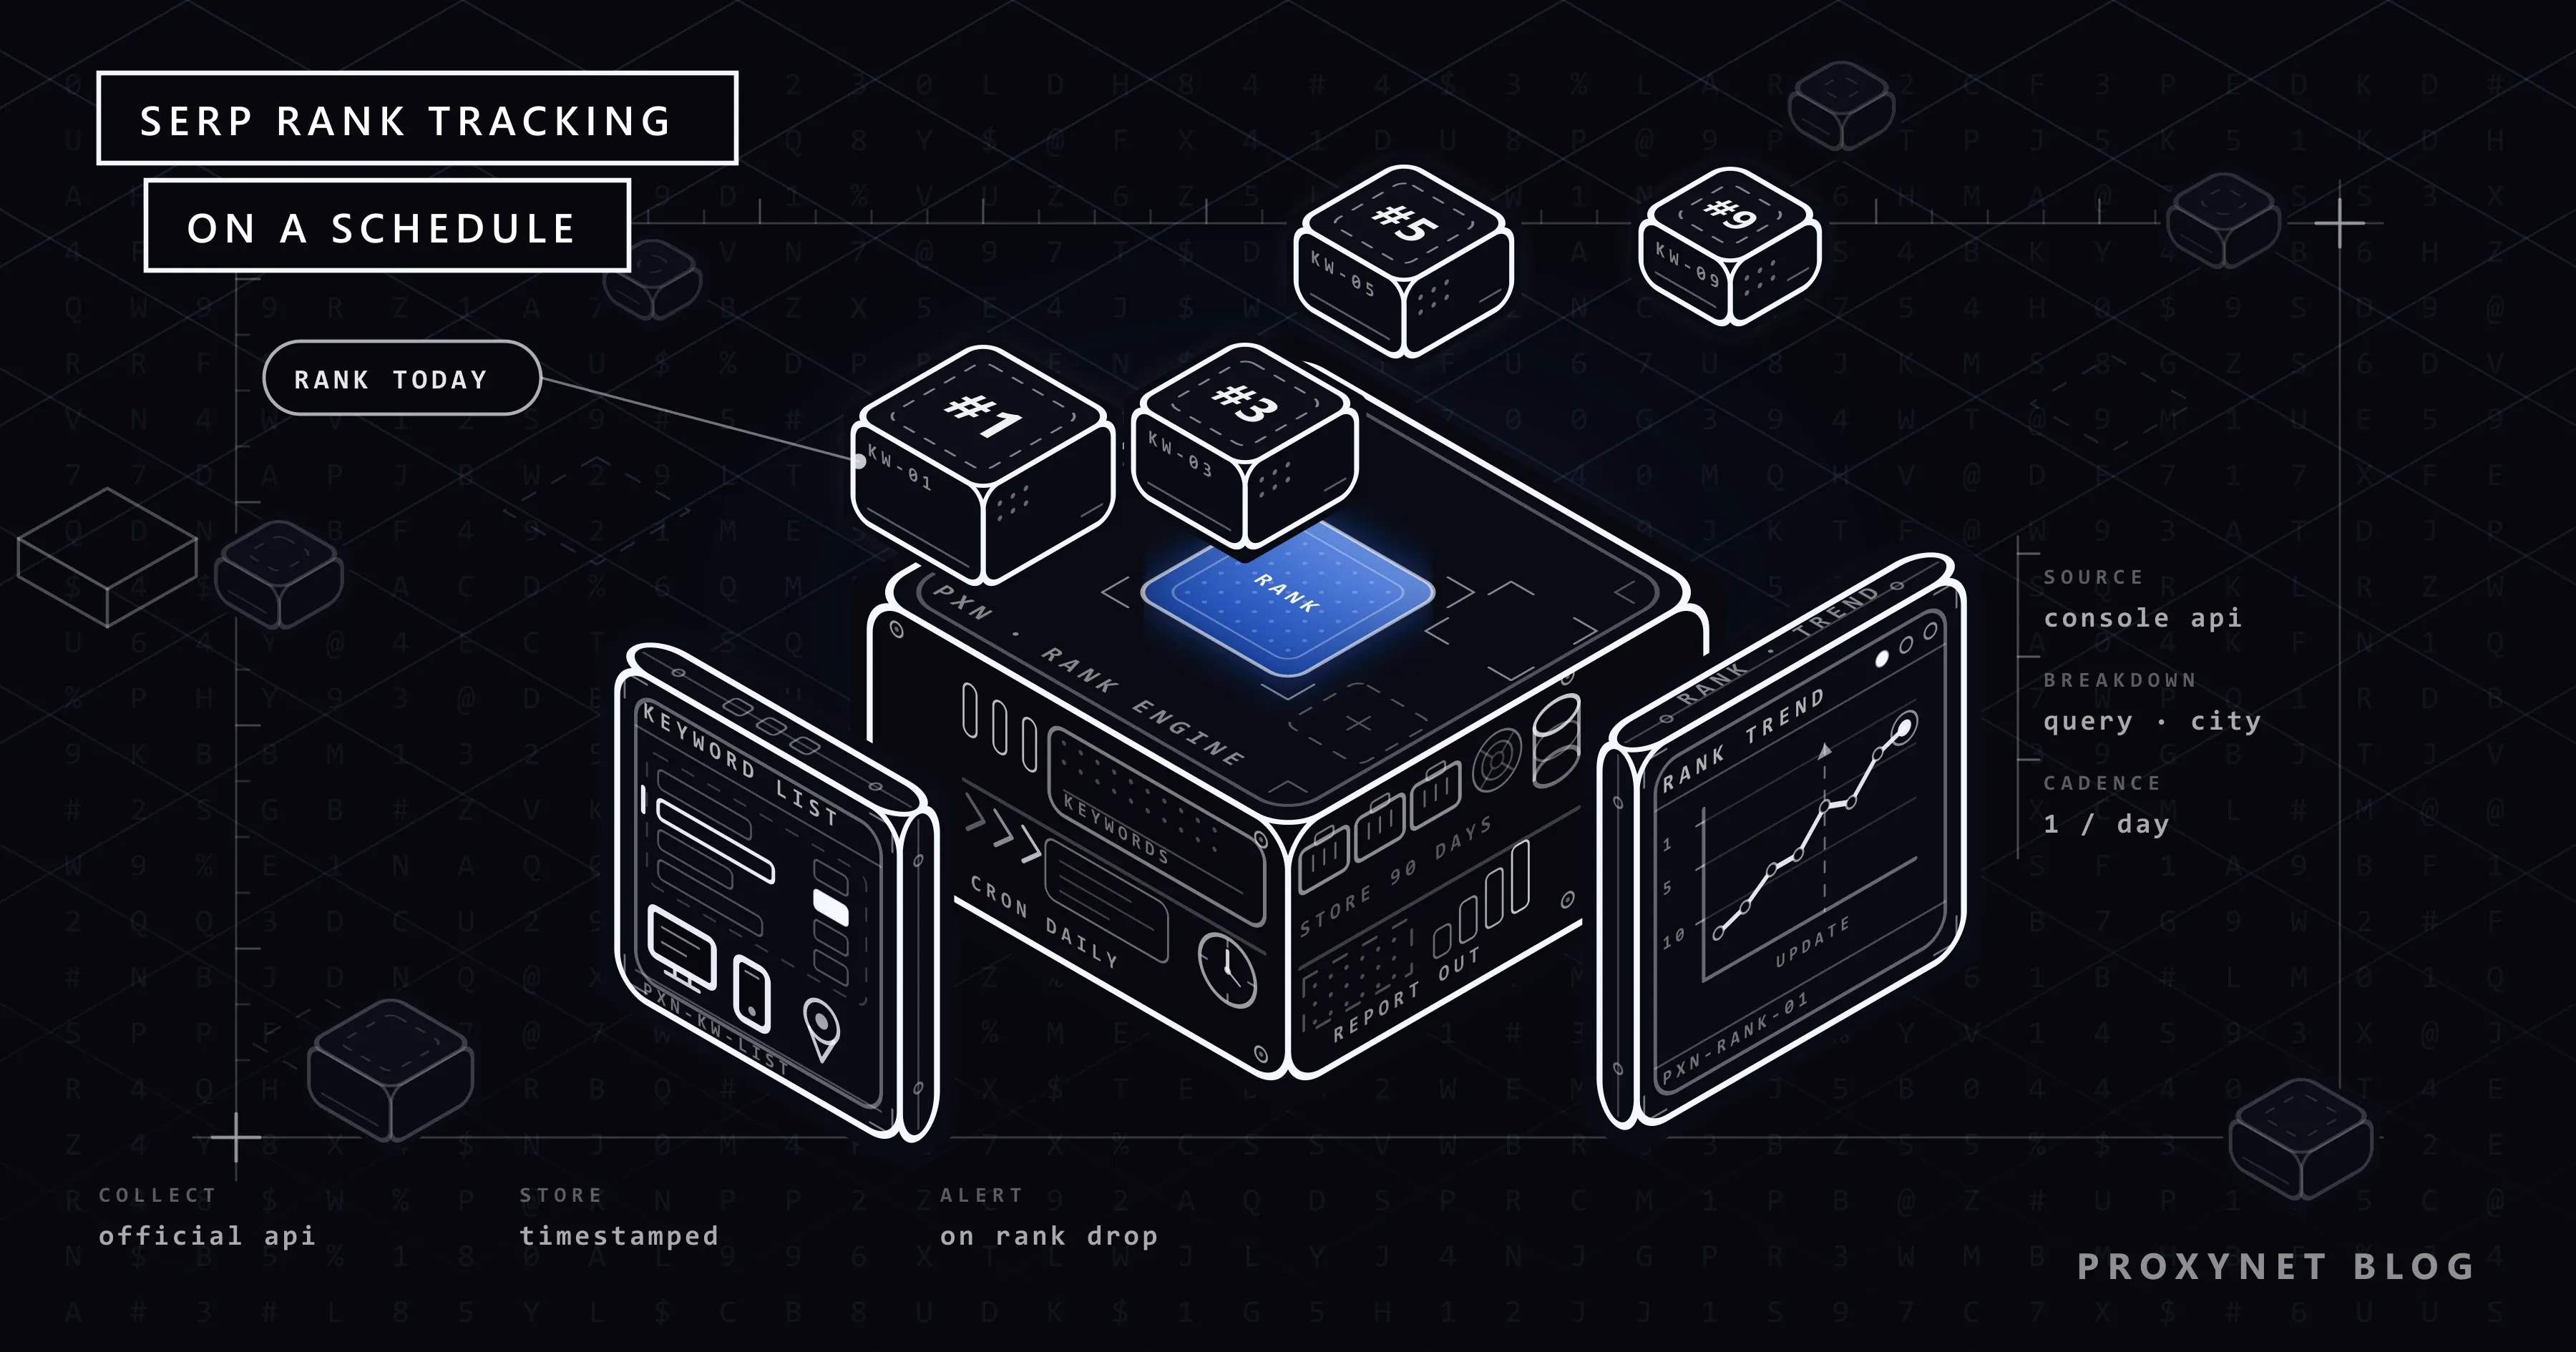
Published
How to Automate SEO Rank Tracking
Checking rankings by hand doesn't scale. We walk through automated rank tracking with the Search Console API, SERP data and location-based queries.
Written by:Acar Diveroli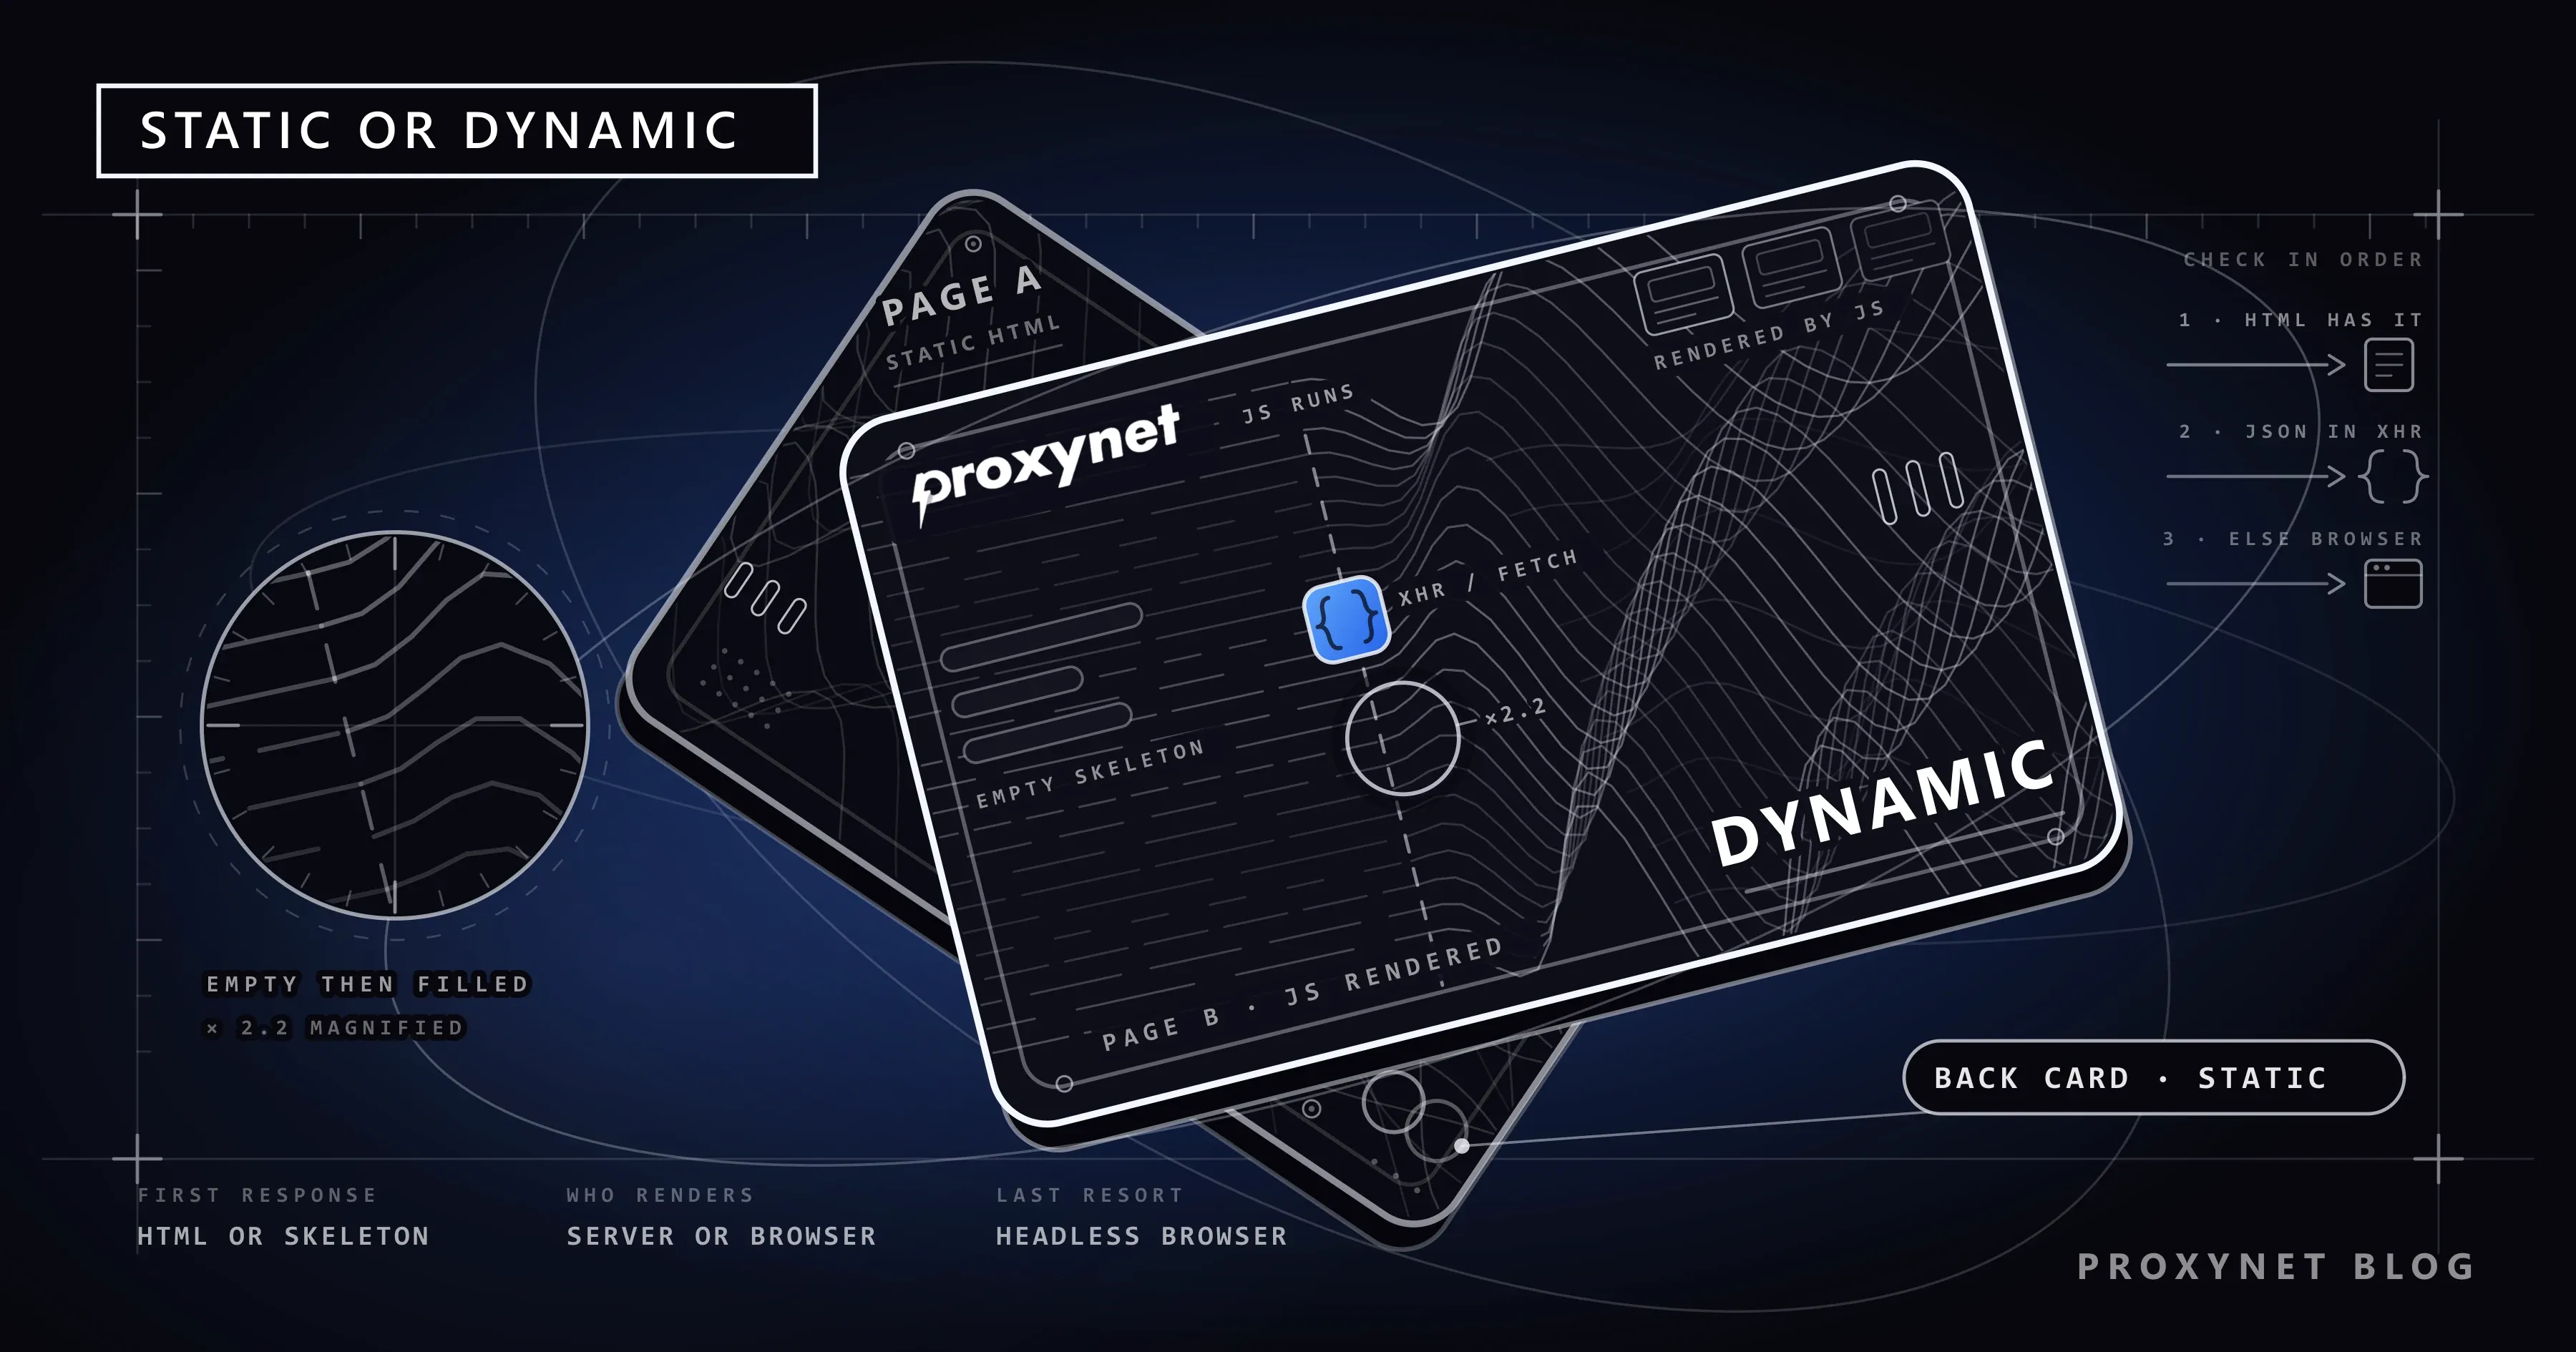
Published
Static vs Dynamic Pages: Do You Need a Headless Browser?
Dynamic pages load their content later with JavaScript, so a simple request comes back empty. We explain with examples when a headless browser is needed.
Written by:Acar Diveroli
Published
Web Scraping: JavaScript or Python?
Python stands out with its data-processing libraries; JavaScript excels at dynamic pages and browser automation. We compare which language suits your project.
Written by:Acar Diveroli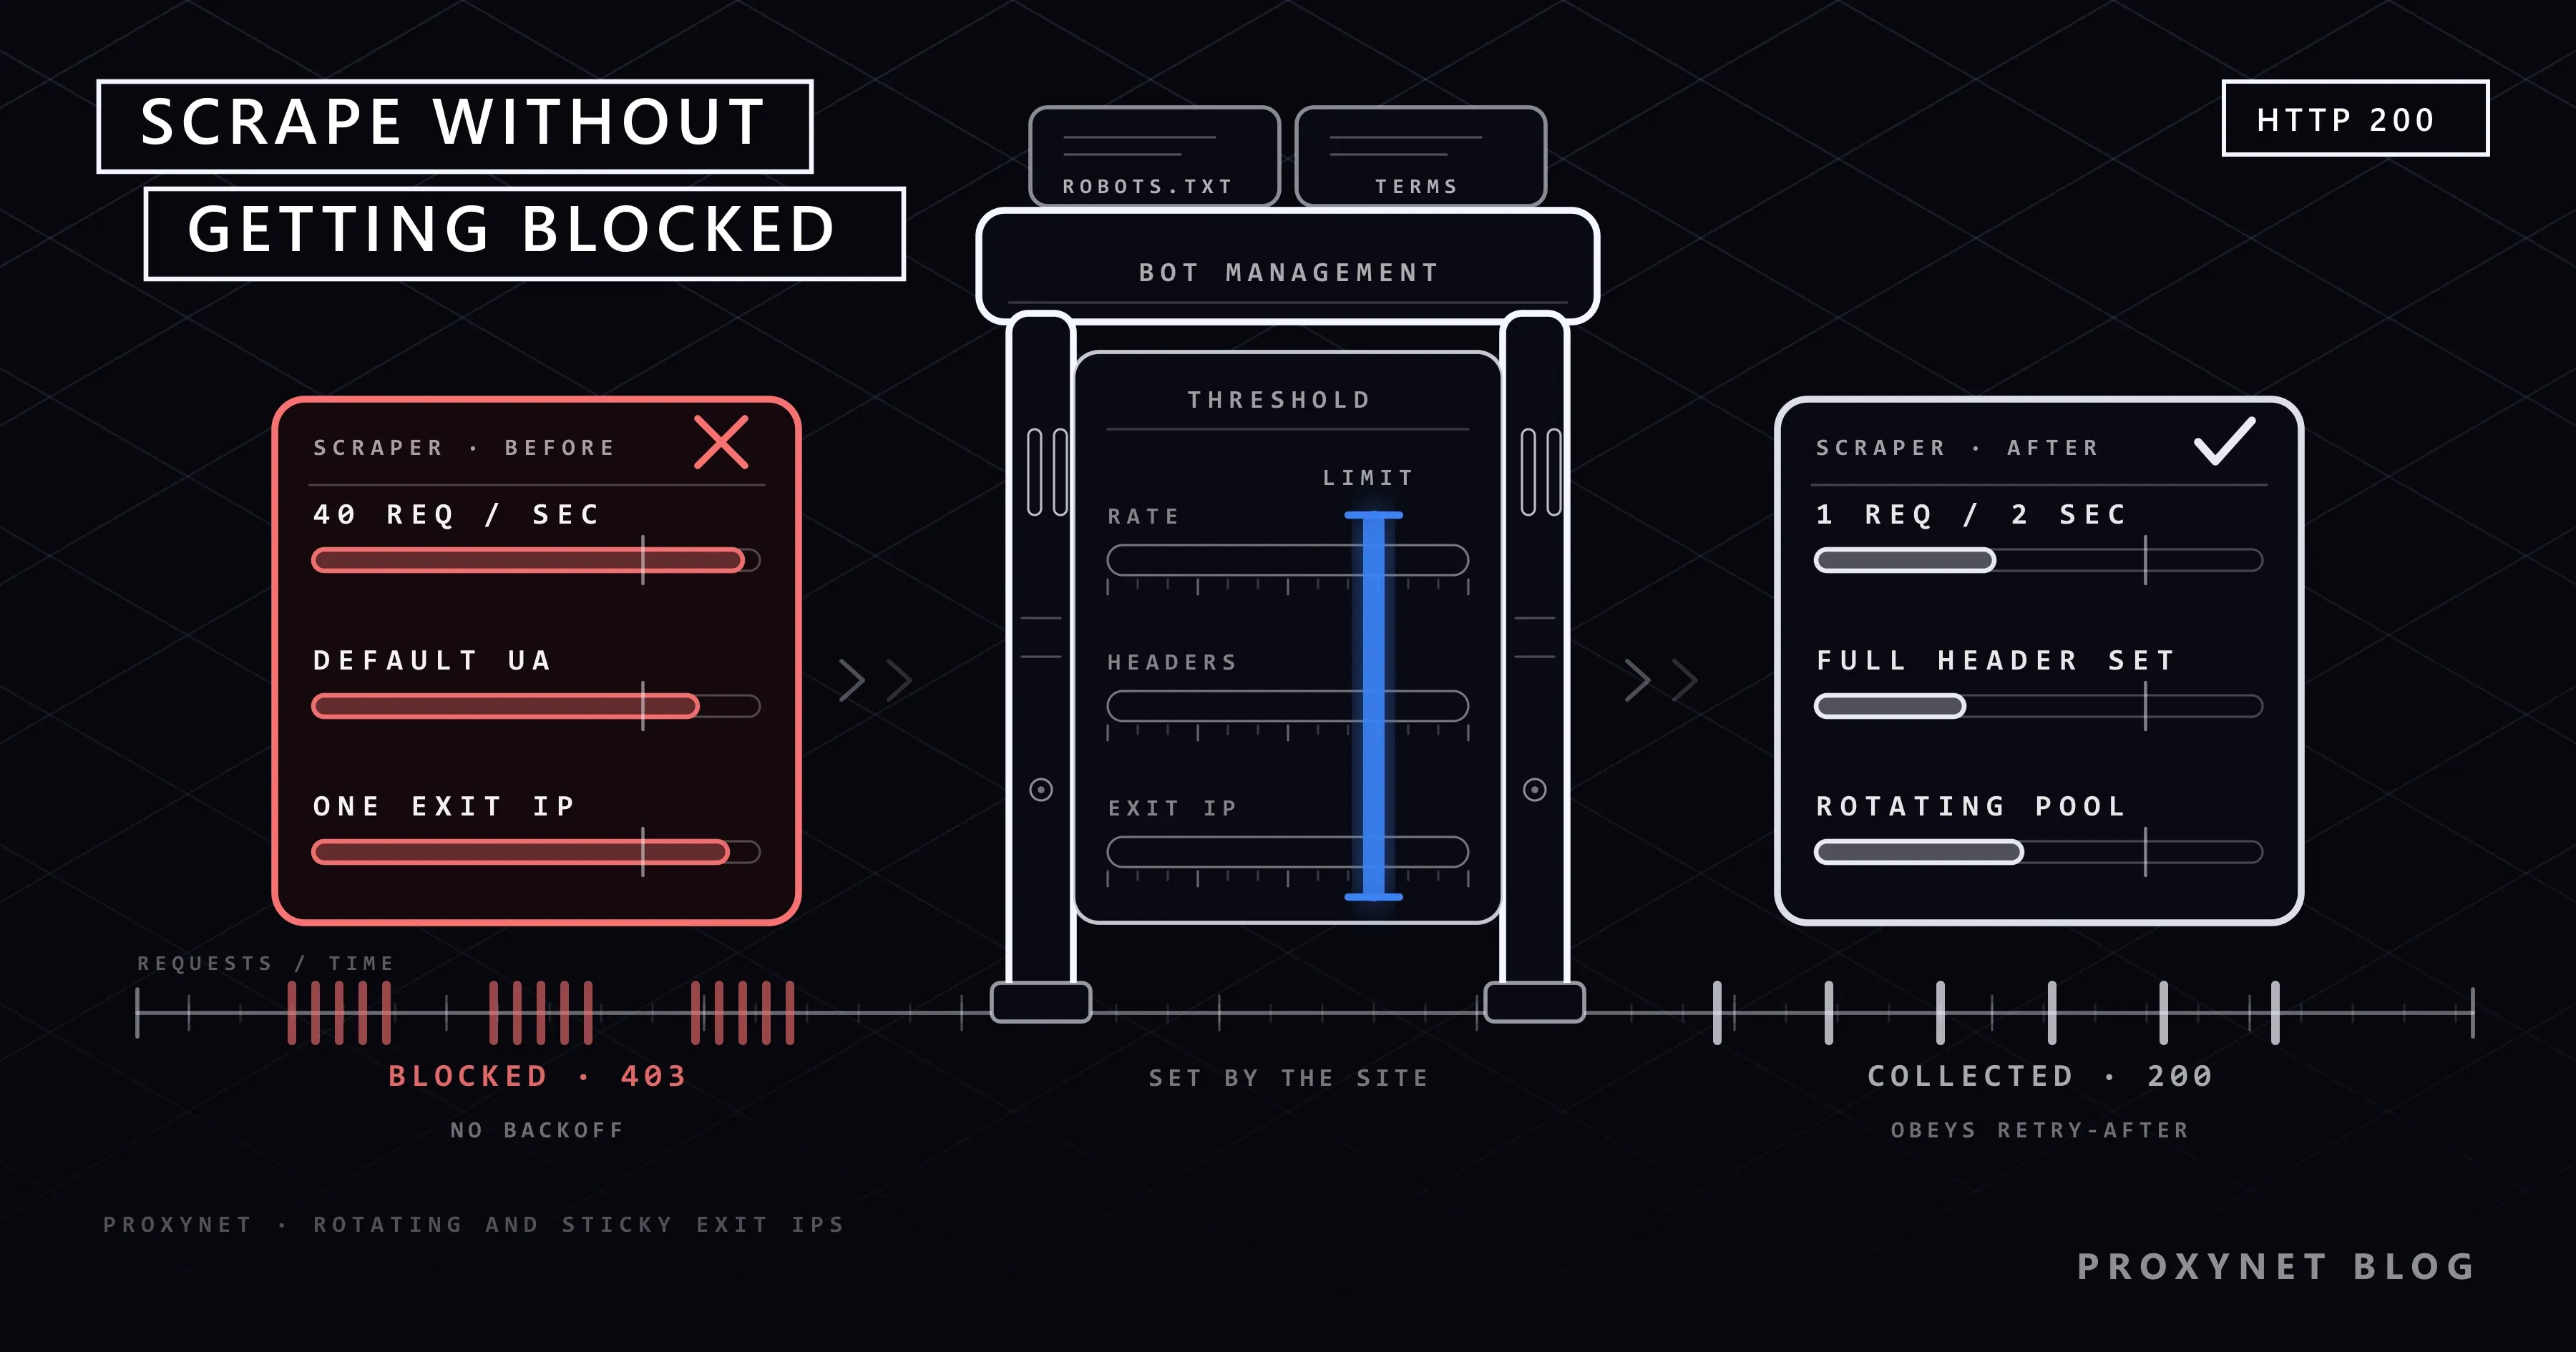
Published
How to Scrape Websites Without Getting Blocked
Scrapers are usually blocked because of rate limits, missing headers and a single IP. We explain how to collect data by the rules without overloading the site.
Written by:Acar Diveroli
Sessions and Cookies in Python: Logging In With requests
Written by: Acar DiveroliTutorialPublished
What Is Scrapy and How to Use It With a Proxy
Written by: Acar DiveroliWeb ScrapingPublished
What Is TLS Fingerprinting and JA3? How It Works
Written by: Acar DiveroliWeb ScrapingPublished
Why Are AI Shopping Agents Blocked on Websites?
Written by: Acar DiveroliAIPublished
Concurrency vs Parallelism: What Sets Scraping Speed?
Written by: Acar DiveroliComparisonPublished
CSS Selector vs XPath: Which One for Web Scraping?
Written by: Acar DiveroliComparisonPublished
Web Scraping with GPT-6 Astra: What Changed?
Written by: Acar DiveroliAIPublished
What Are Honeypot Traps and How Do They Affect Scraping?
Written by: Acar DiveroliWeb ScrapingPublished
HTTP Status Codes in Web Scraping: 403, 407, 429, 503
Written by: Acar DiveroliWeb ScrapingPublished
HTTPX vs. Requests vs. AIOHTTP Compared
Written by: Acar DiveroliComparisonPublished
What Is a robots.txt File and How Do You Read It?
Written by: Acar DiveroliWeb ScrapingPublished
How to Automate SEO Rank Tracking
Written by: Acar DiveroliUse CasesPublished
Static vs Dynamic Pages: Do You Need a Headless Browser?
Written by: Acar DiveroliComparisonPublished
Web Scraping: JavaScript or Python?
Written by: Acar DiveroliComparisonPublished
How to Scrape Websites Without Getting Blocked
Written by: Acar DiveroliWeb ScrapingPublished
No posts match
Published
Published