

































Web Scraping · Proxynet Blog
Published
Why Are AI Shopping Agents Blocked on Websites?
Shopping agents hit bot protection because sites can't tell a human from an authorised agent. We explain why, and new fixes such as signed agents.
Written by: Acar Diveroli
Published
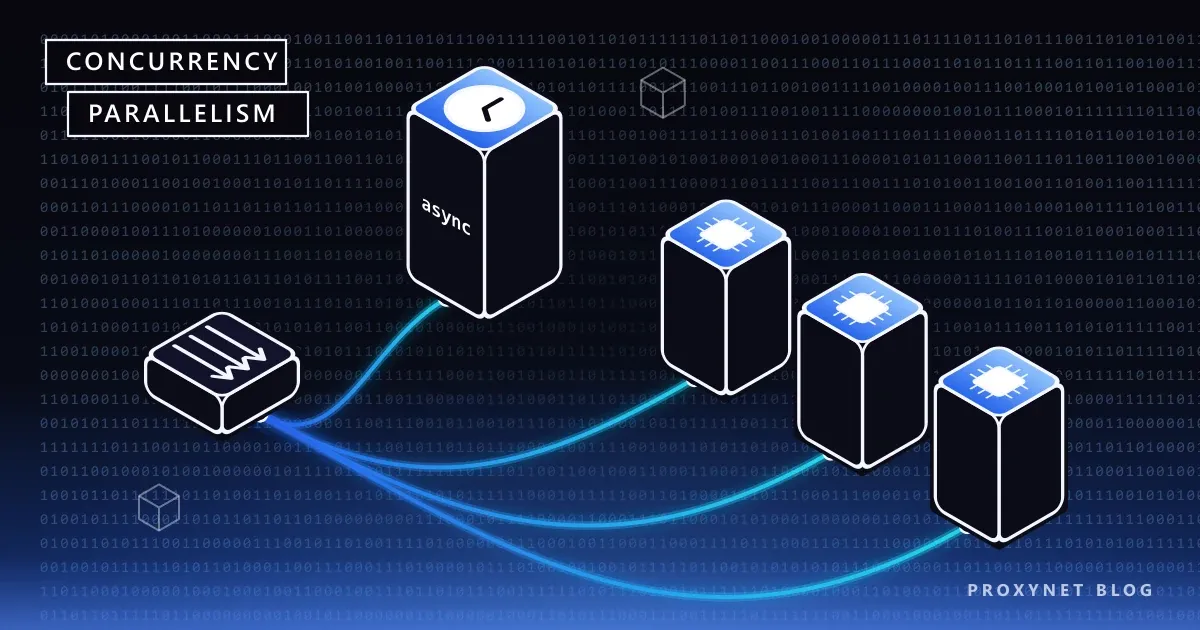
Concurrency vs Parallelism: What Sets Scraping Speed?
Concurrency makes use of waiting time, parallelism makes use of CPU power. We explain which one speeds up scraping, with Python and Node.js examples.
Written by:Acar Diveroli
Published
CSS Selector vs XPath: Which One for Web Scraping?
CSS selectors are short and readable, while XPath can also select by text and parent elements. We compare syntax, speed and Python examples for both methods.
Written by:Acar Diveroli
Published
What Are Honeypot Traps and How Do They Affect Scraping?
Honeypots are hidden links that visitors never see but bots get caught on. We explain how they work and how they flag a scraper, without teaching evasion.
Written by:Acar Diveroli
Published
HTTP Status Codes in Web Scraping: 403, 407, 429, 503
403, 407, 429 and 503 responses point to different problems in scraping. We explain what each code means, its causes and how to retry properly with Retry-After.
Written by:Acar Diveroli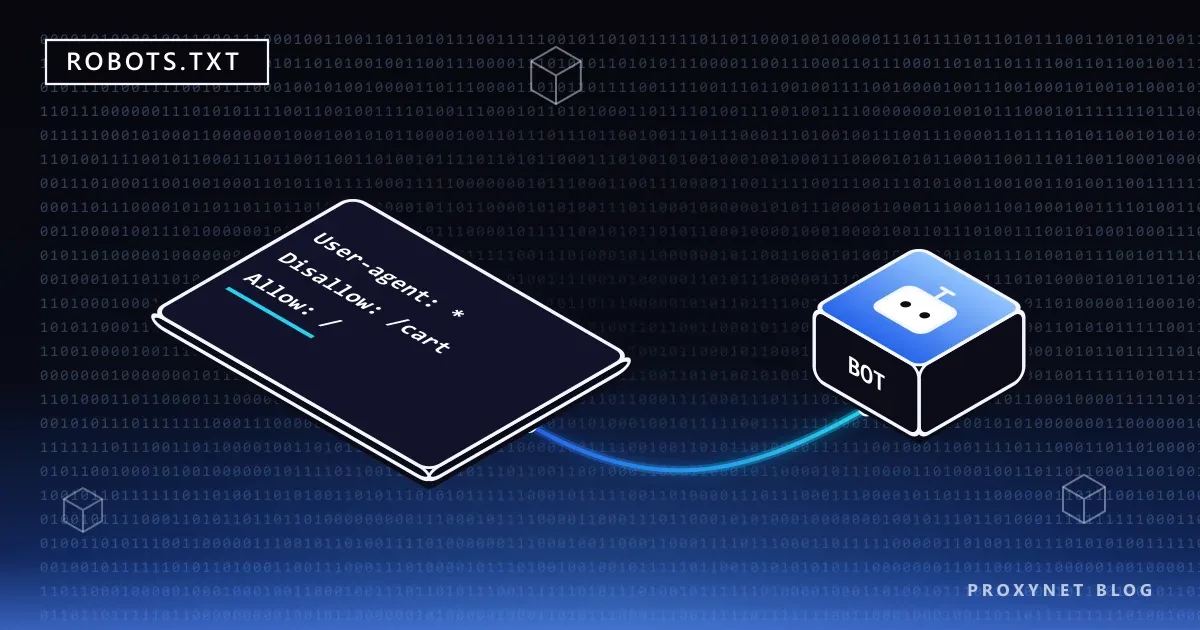
Published
What Is a robots.txt File and How Do You Read It?
robots.txt is the file where a site tells bots which paths not to crawl. We explain the Disallow, Allow and Crawl-delay rules and how to read it with Python.
Written by:Acar Diveroli
Published
How to Automate SEO Rank Tracking
Checking rankings by hand doesn't scale. We walk through automated rank tracking with the Search Console API, SERP data and location-based queries.
Written by:Acar Diveroli
Published
Static vs Dynamic Pages: Do You Need a Headless Browser?
Dynamic pages load their content later with JavaScript, so a simple request comes back empty. We explain with examples when a headless browser is needed.
Written by:Acar Diveroli
Published
How to Scrape Websites Without Getting Blocked
Scrapers are usually blocked because of rate limits, missing headers and a single IP. We explain how to collect data by the rules without overloading the site.
Written by:Acar Diveroli
Why Are AI Shopping Agents Blocked on Websites?
Written by: Acar DiveroliWeb ScrapingPublished
Concurrency vs Parallelism: What Sets Scraping Speed?
Written by: Acar DiveroliWeb ScrapingPublished
CSS Selector vs XPath: Which One for Web Scraping?
Written by: Acar DiveroliWeb ScrapingPublished
What Are Honeypot Traps and How Do They Affect Scraping?
Written by: Acar DiveroliWeb ScrapingPublished
HTTP Status Codes in Web Scraping: 403, 407, 429, 503
Written by: Acar DiveroliWeb ScrapingPublished
What Is a robots.txt File and How Do You Read It?
Written by: Acar DiveroliWeb ScrapingPublished
How to Automate SEO Rank Tracking
Written by: Acar DiveroliWeb ScrapingPublished
Static vs Dynamic Pages: Do You Need a Headless Browser?
Written by: Acar DiveroliWeb ScrapingPublished
How to Scrape Websites Without Getting Blocked
Written by: Acar DiveroliWeb ScrapingPublished
No posts match
Published
Published