
Proxynet Blog – Page 10
Published
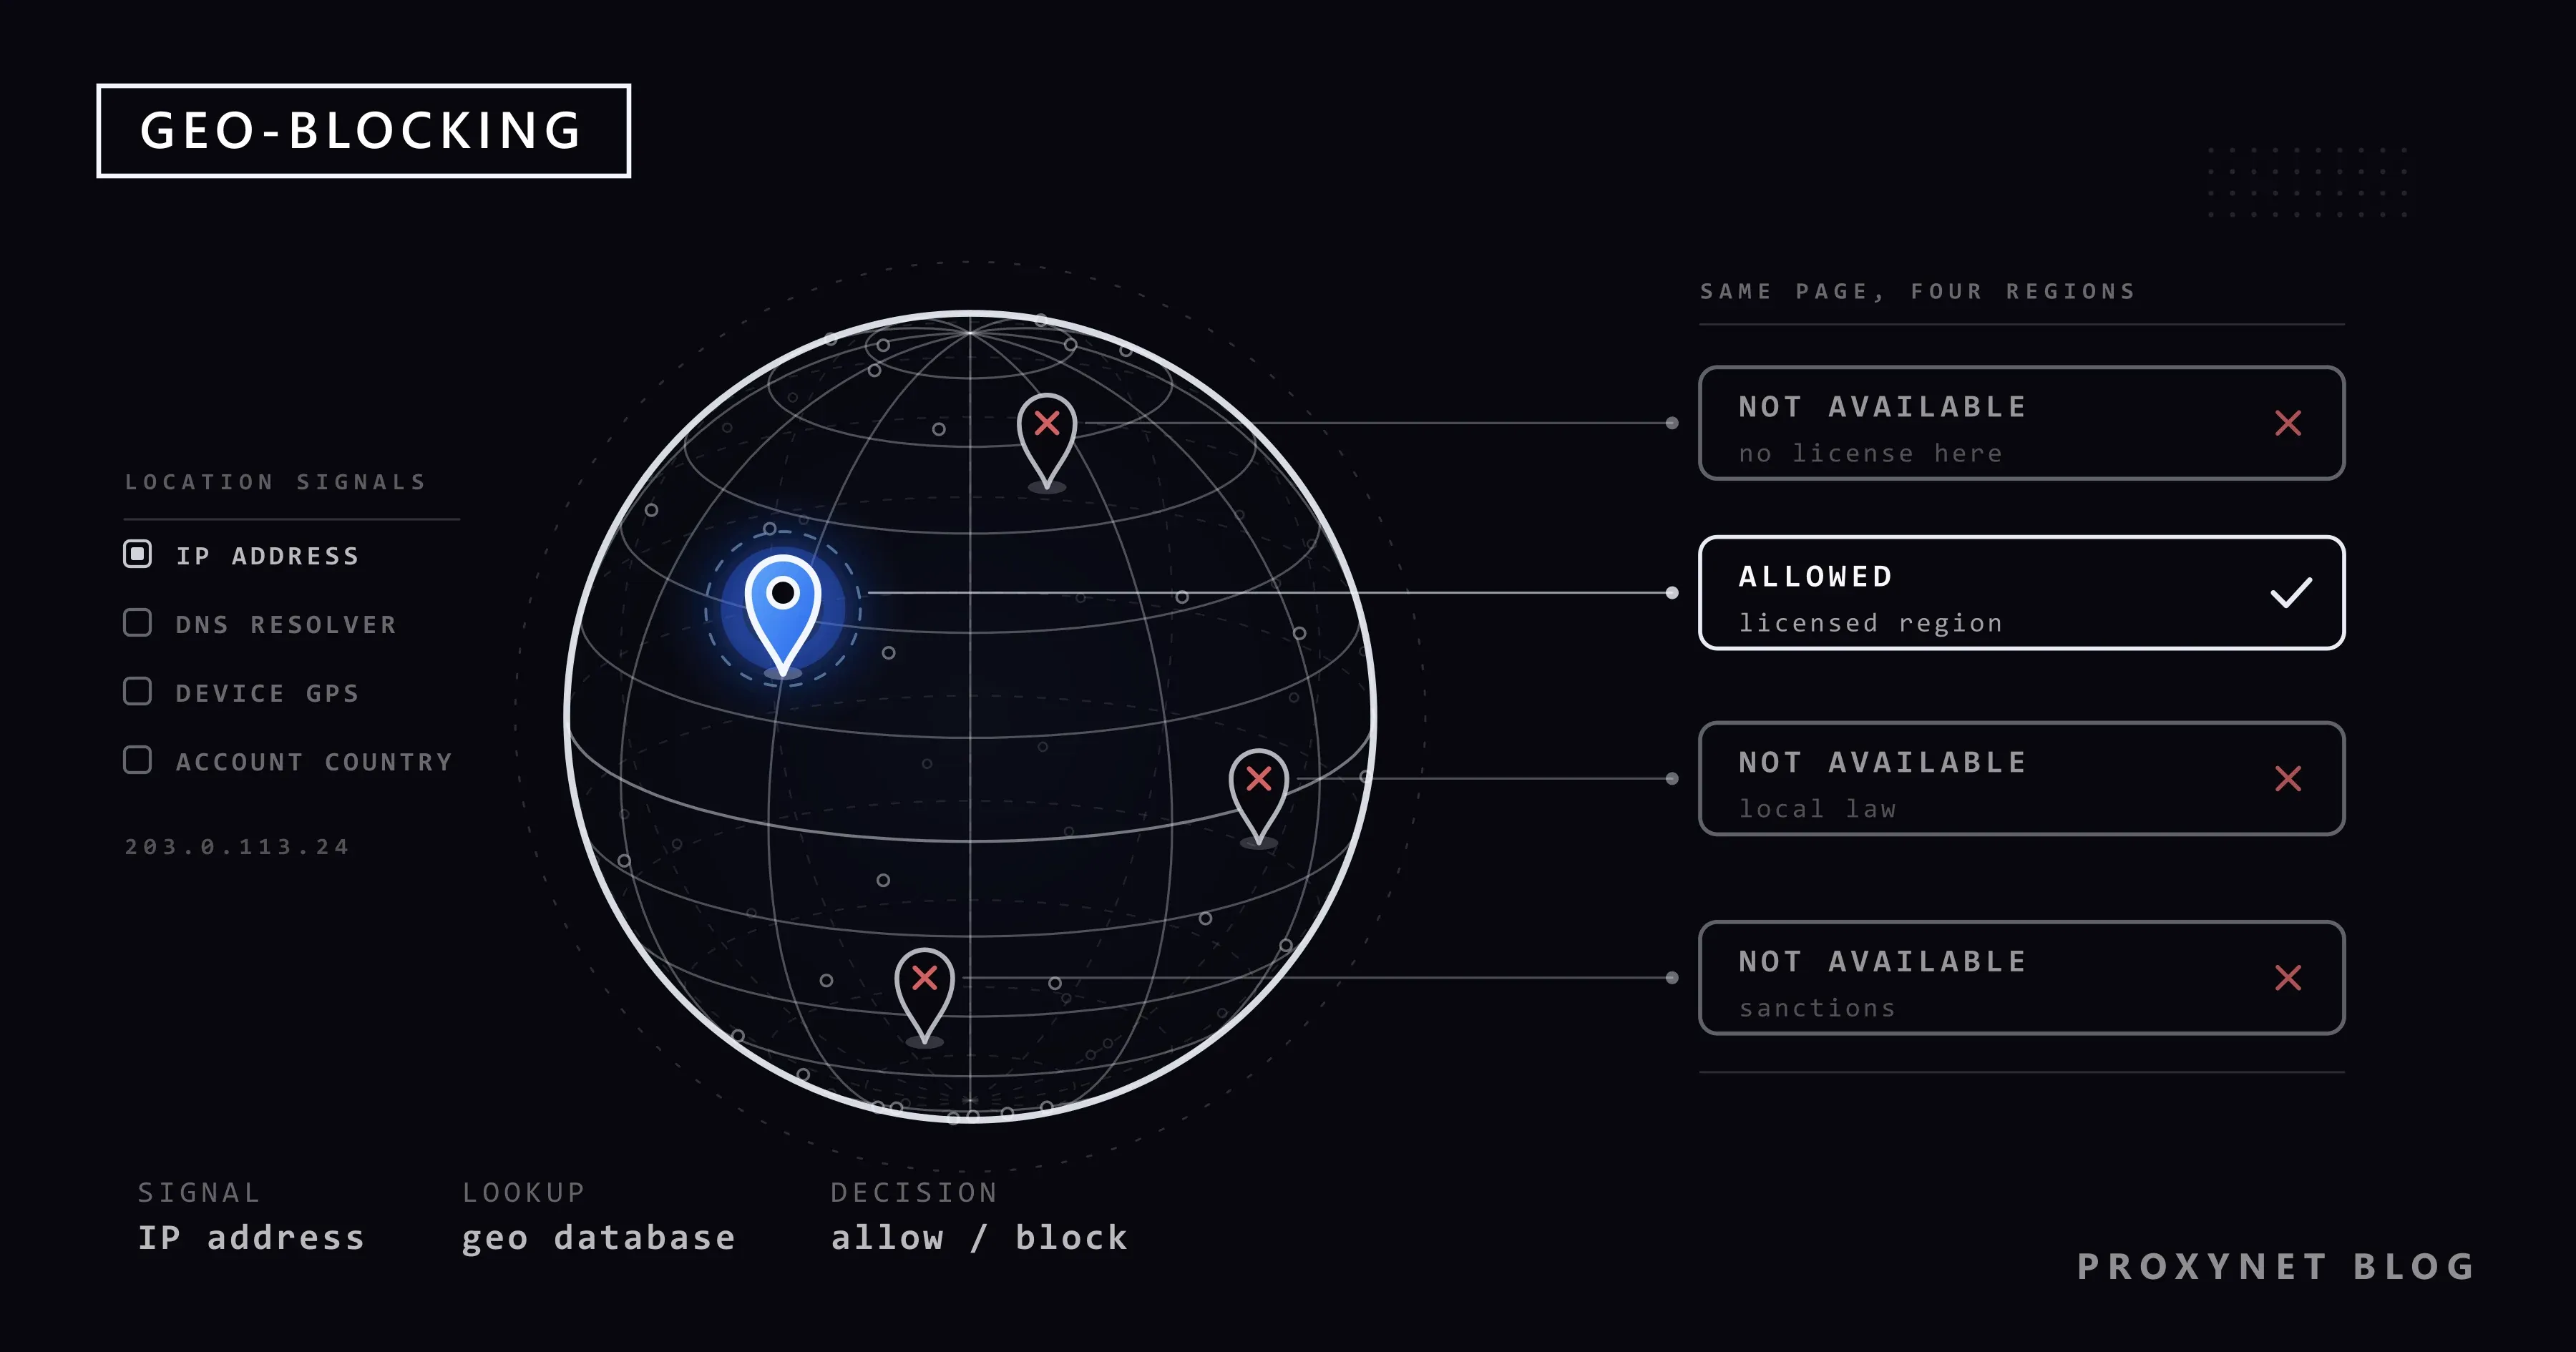
What Is Geo-Blocking and How Do Sites Know Your Location?
Geo-blocking means a site limits content by the country it reads from your connection. Why services do it, how they detect location and what EU law says.
Written by: Acar Diveroli
Published
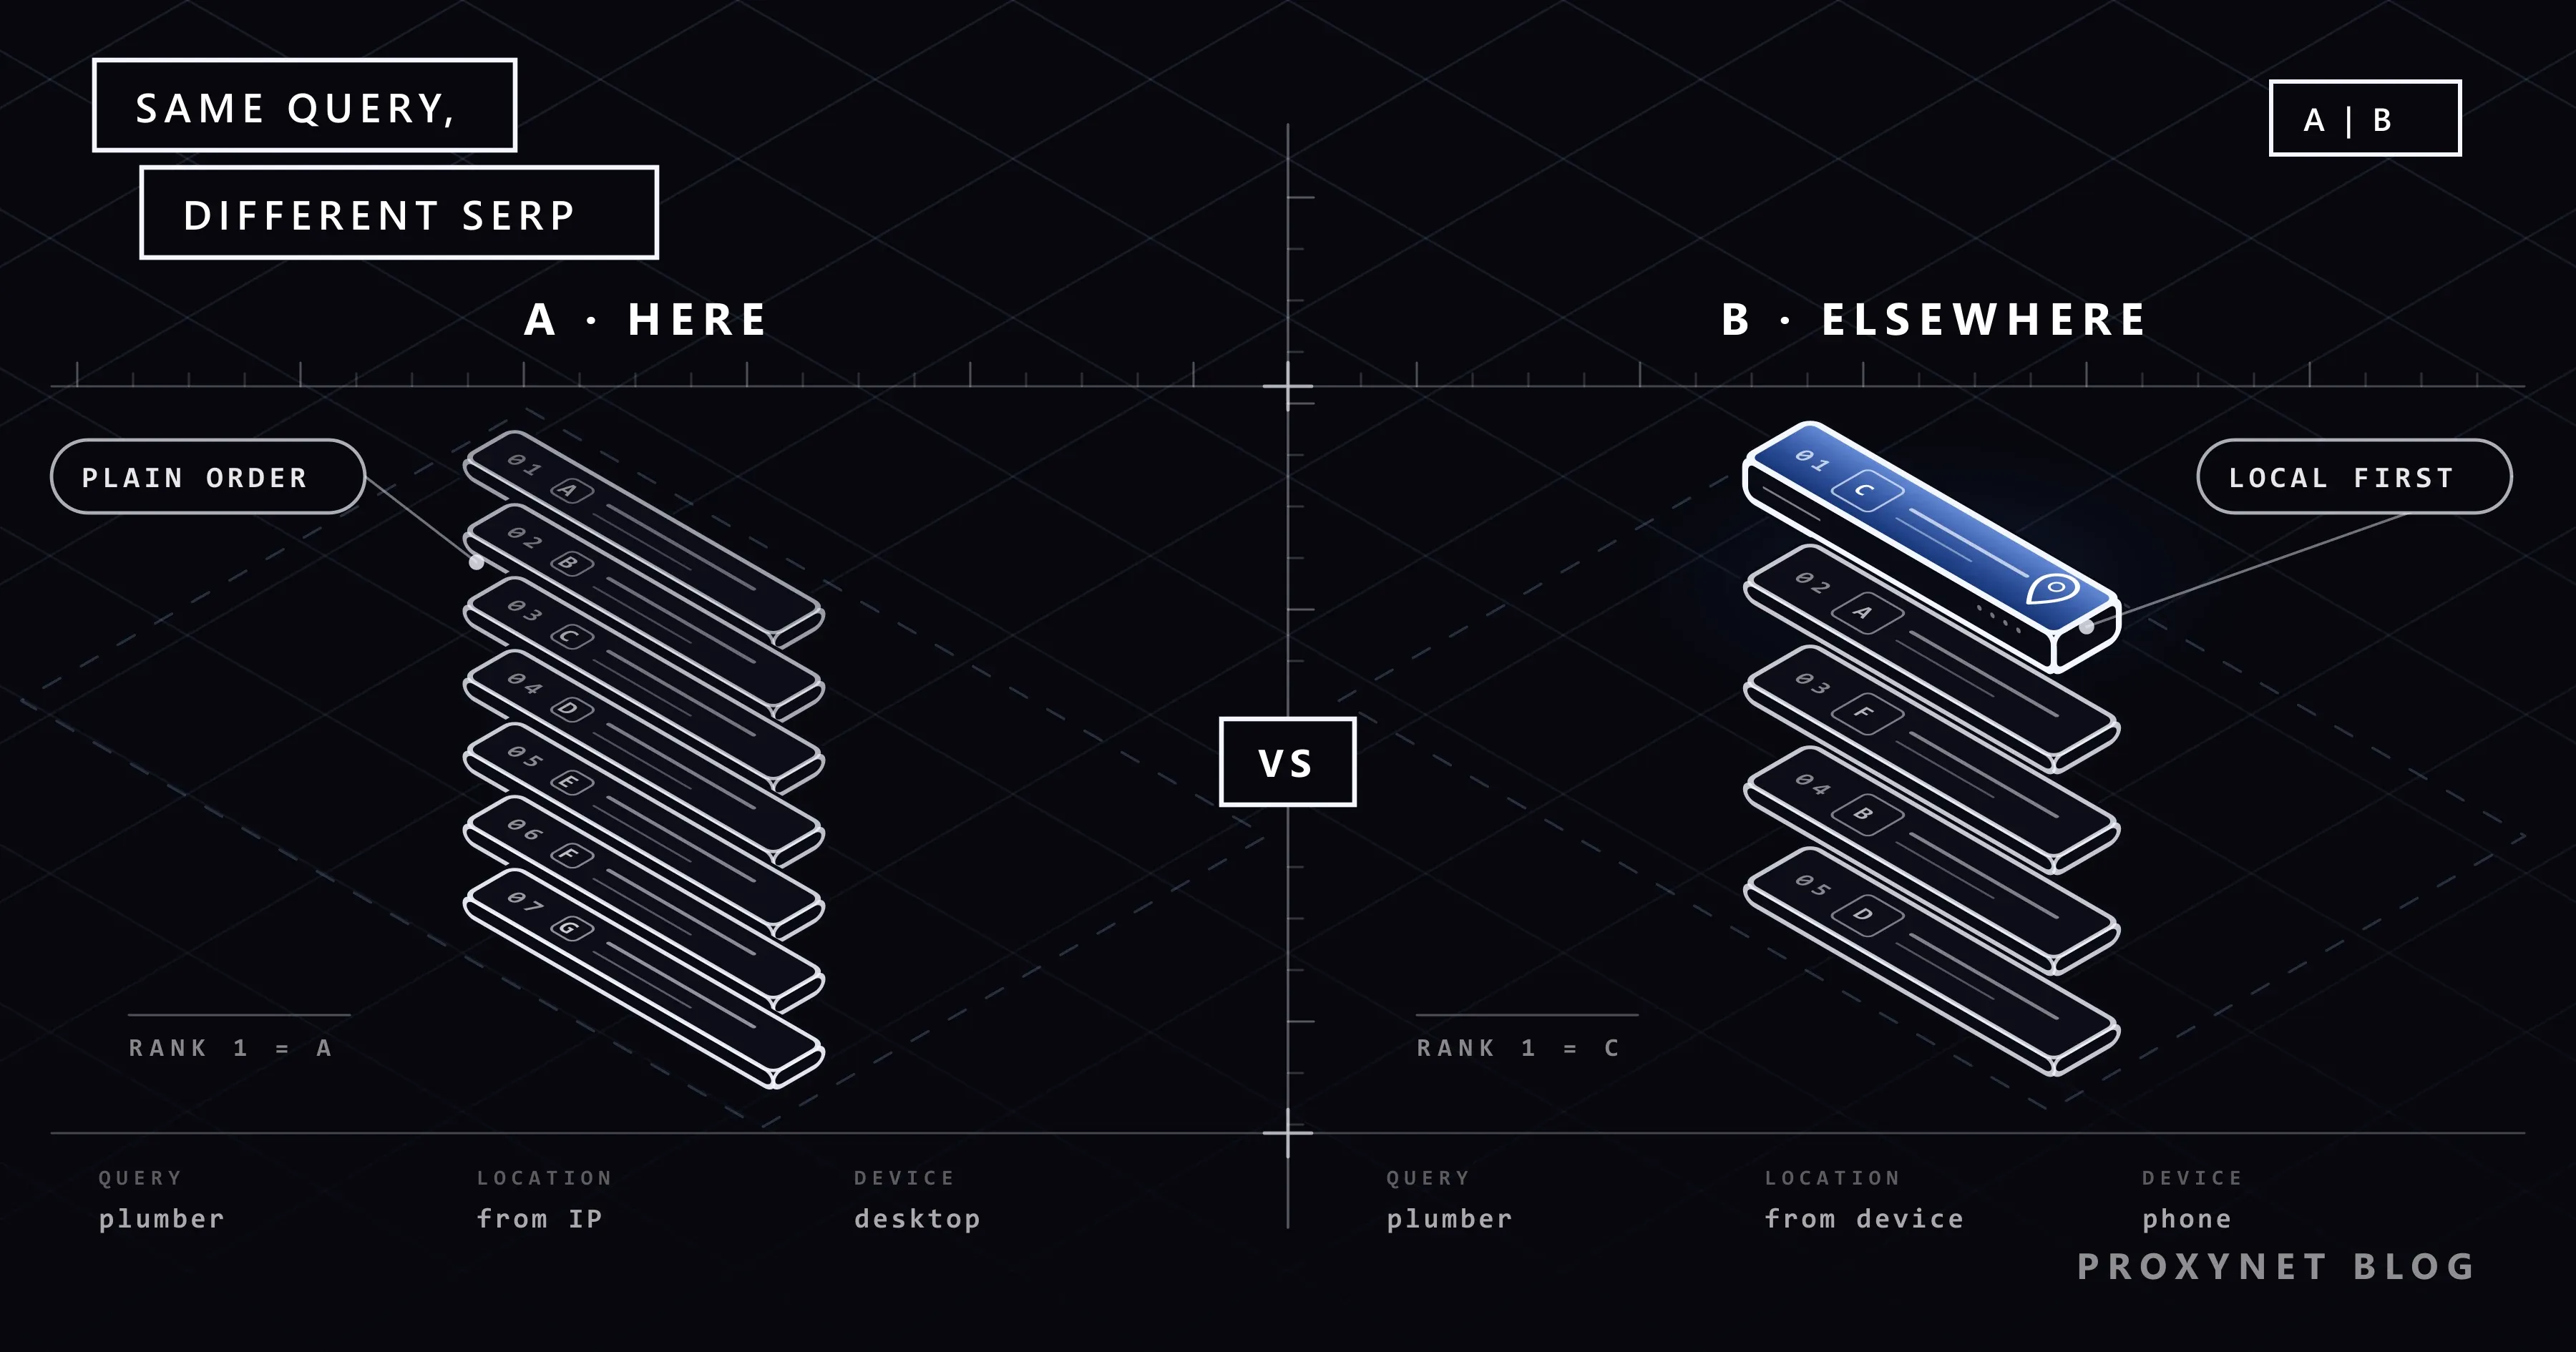
Why Are My Google Search Results Different from Others?
Location, language, account history, device and Google's own tests change the results for the same query. We explain each factor and how to see what others see.
Written by:Acar Diveroli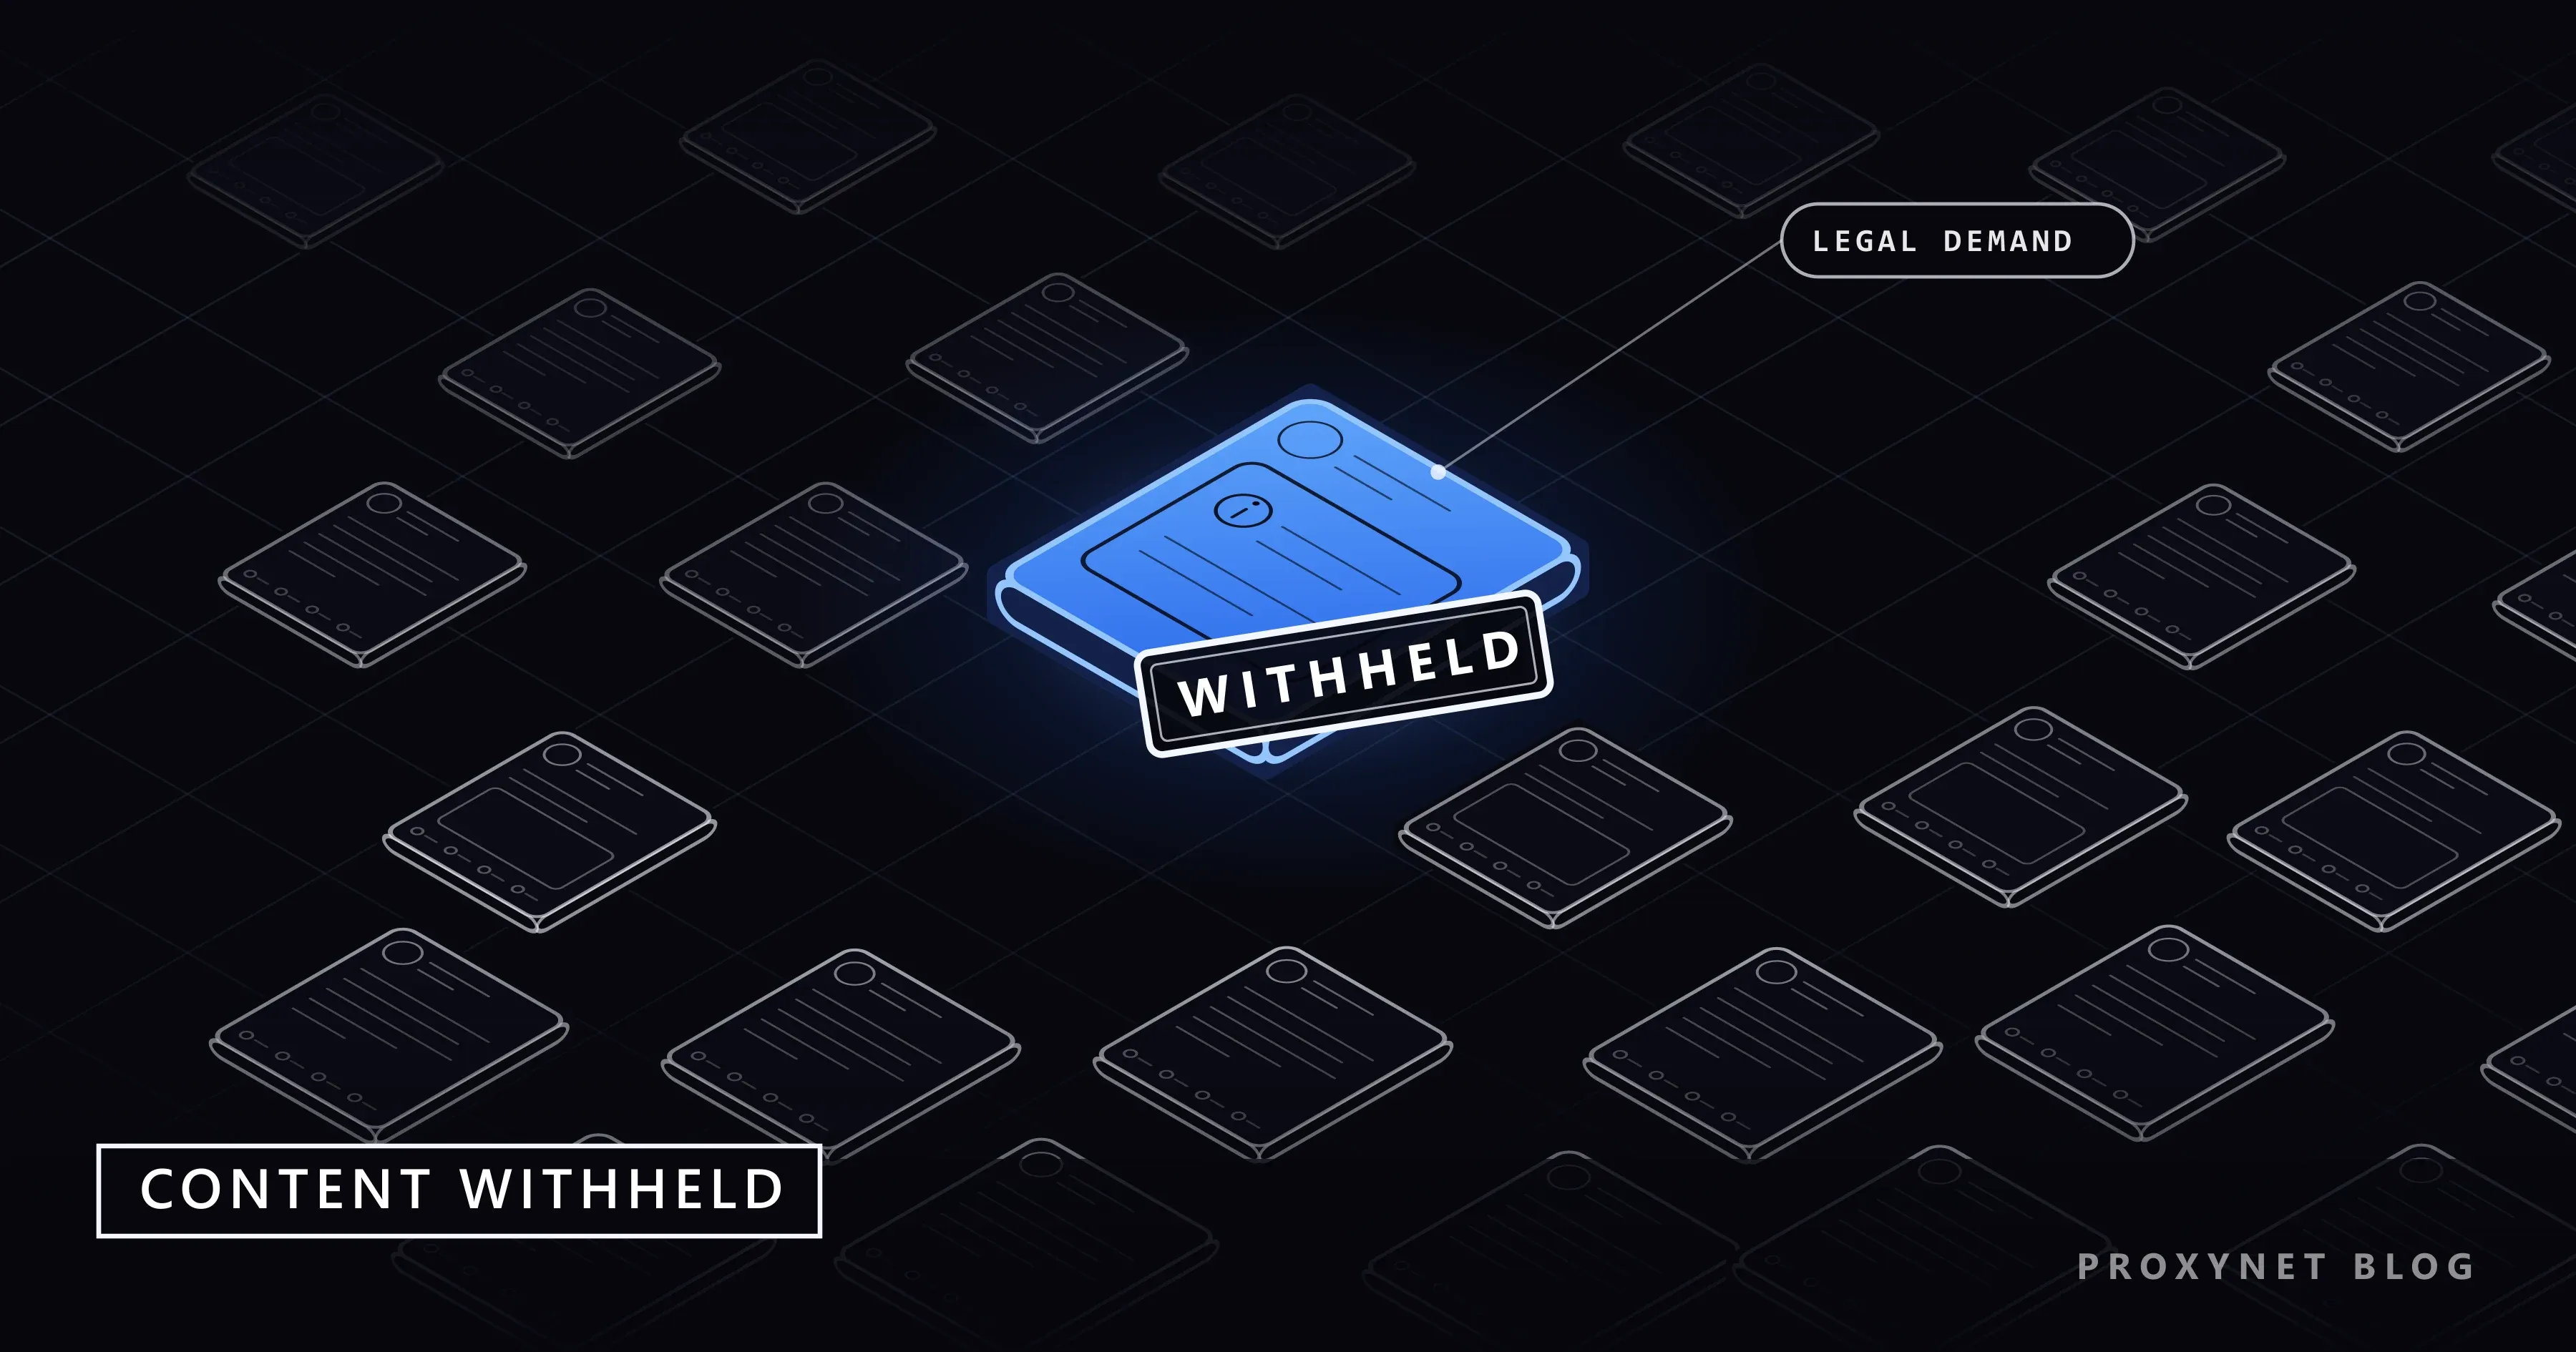
Published
X Post Withheld in Your Country: What It Means
A withheld post on X was blocked in your country because of a legal demand or local law. See how X decides your country and what you can legitimately do.
Written by:Acar Diveroli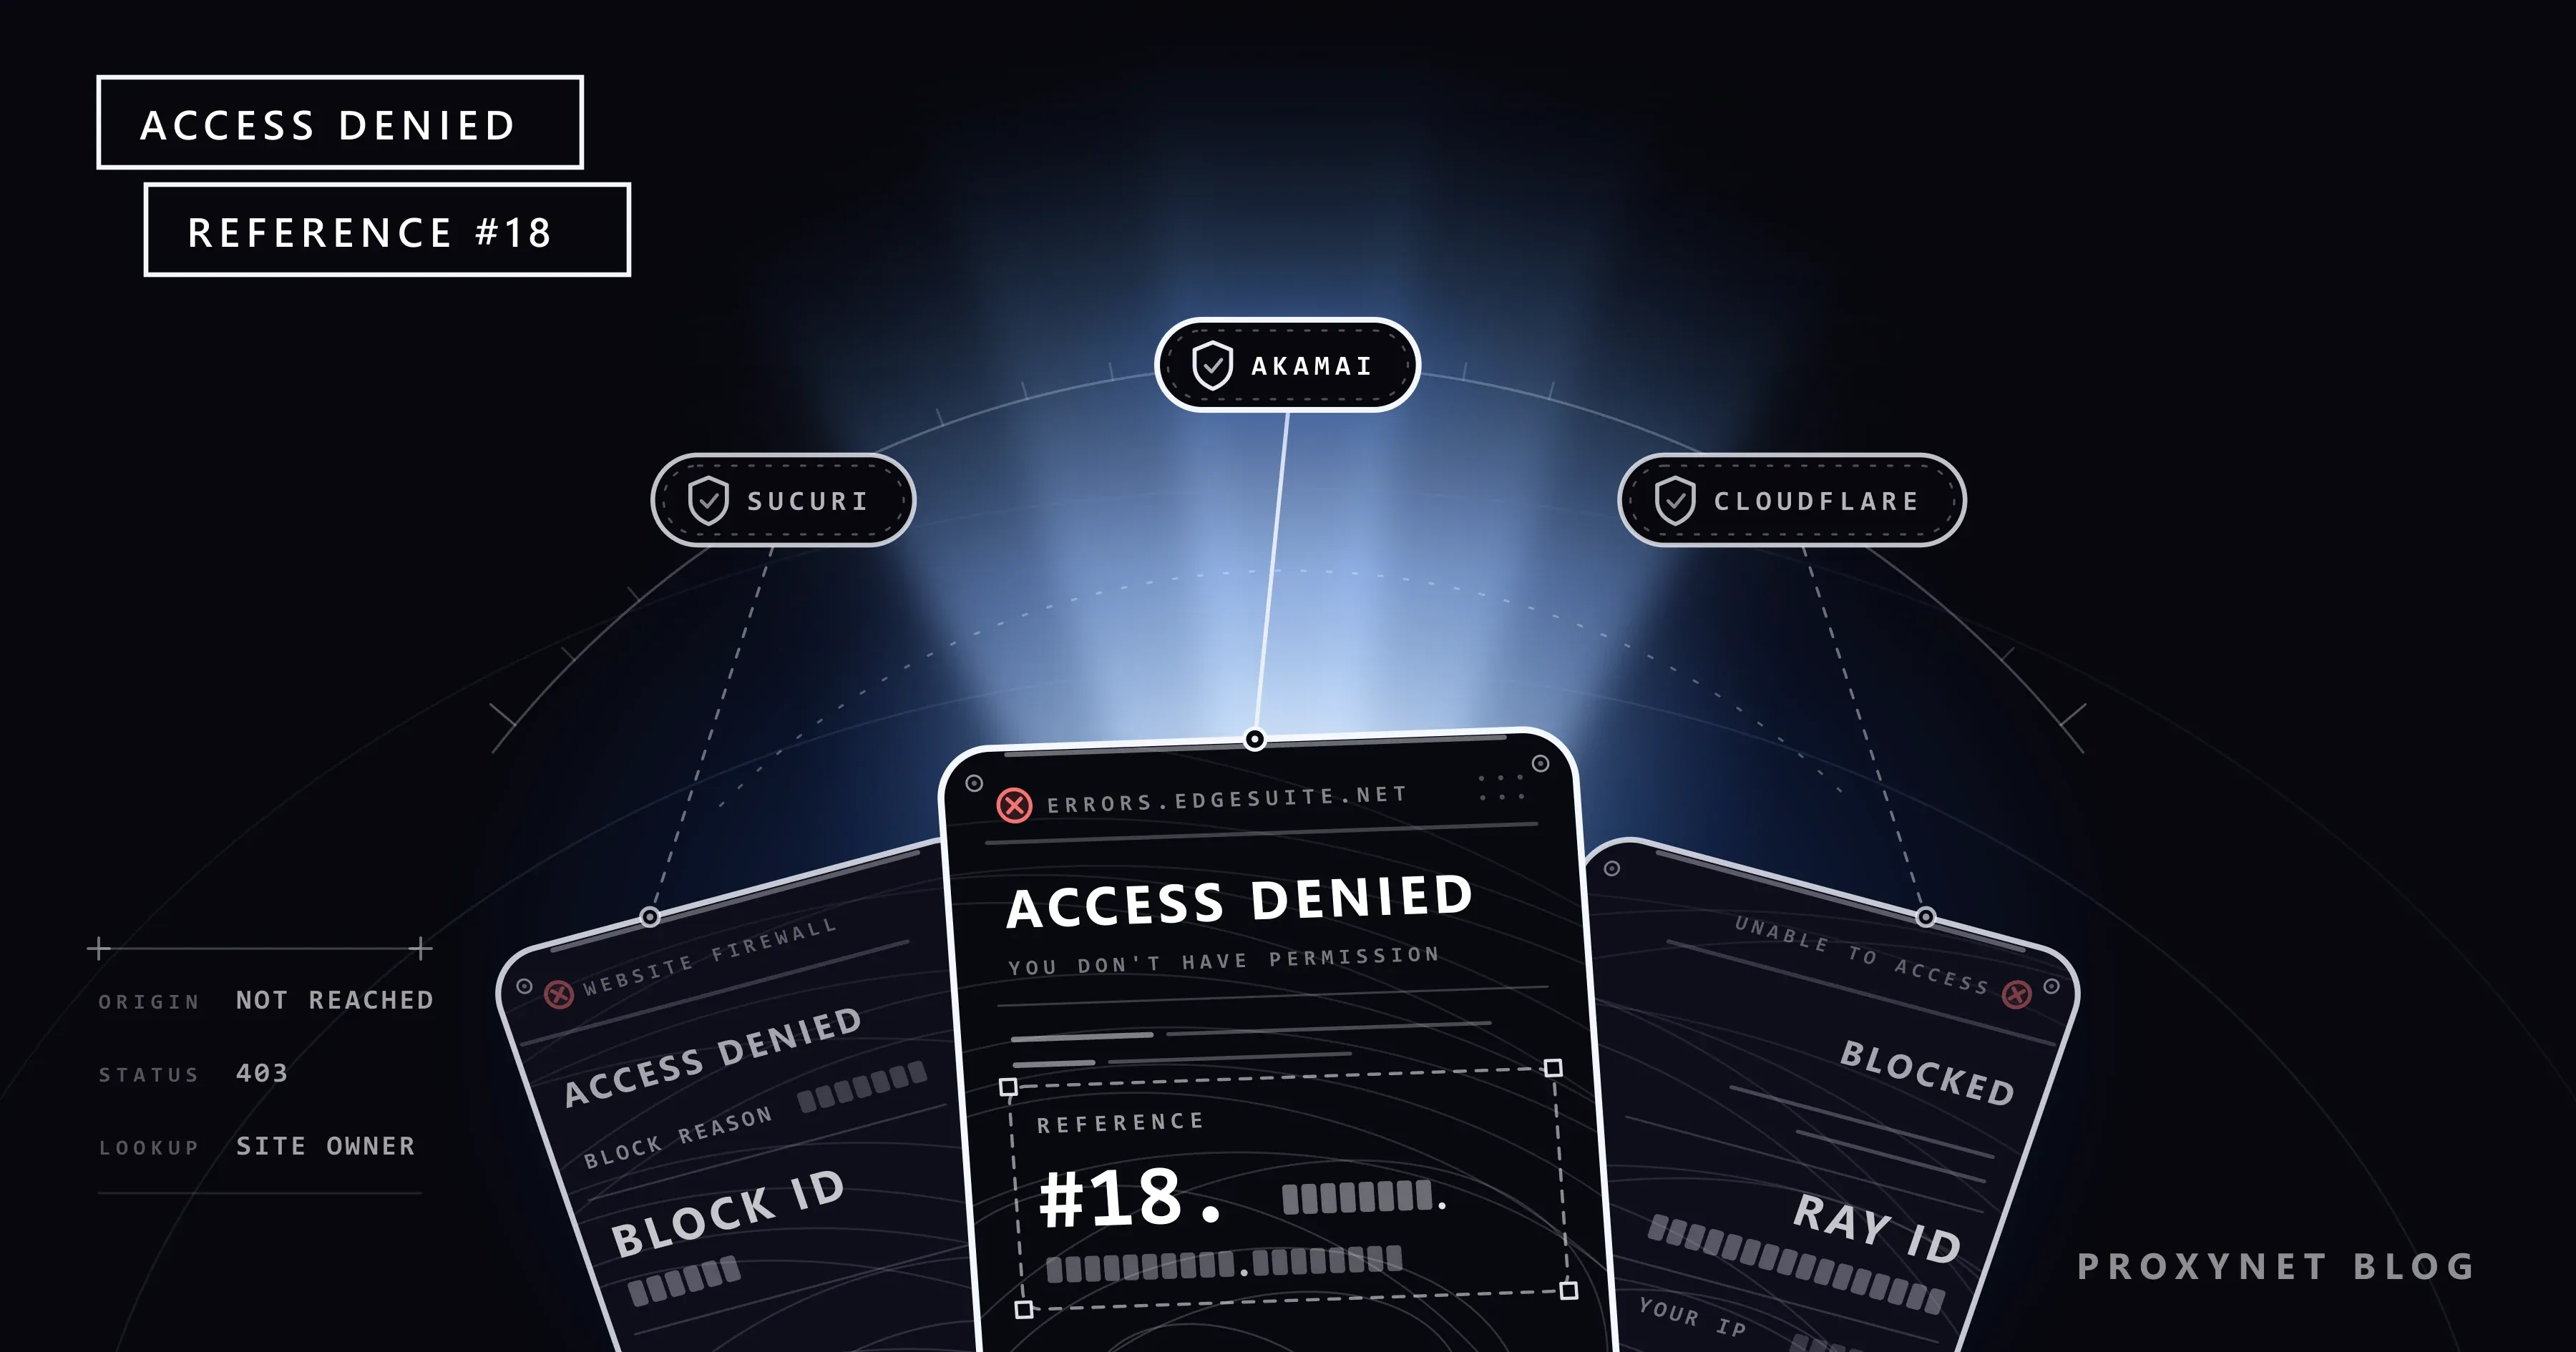
Published
Access Denied Error on Websites: What Reference #18 Means
The Access Denied page comes from the security layer in front of a site; a Reference #18 line points to Akamai. Here is what “You Don't Have Permission” means.
Written by: Enver Kaya
Published
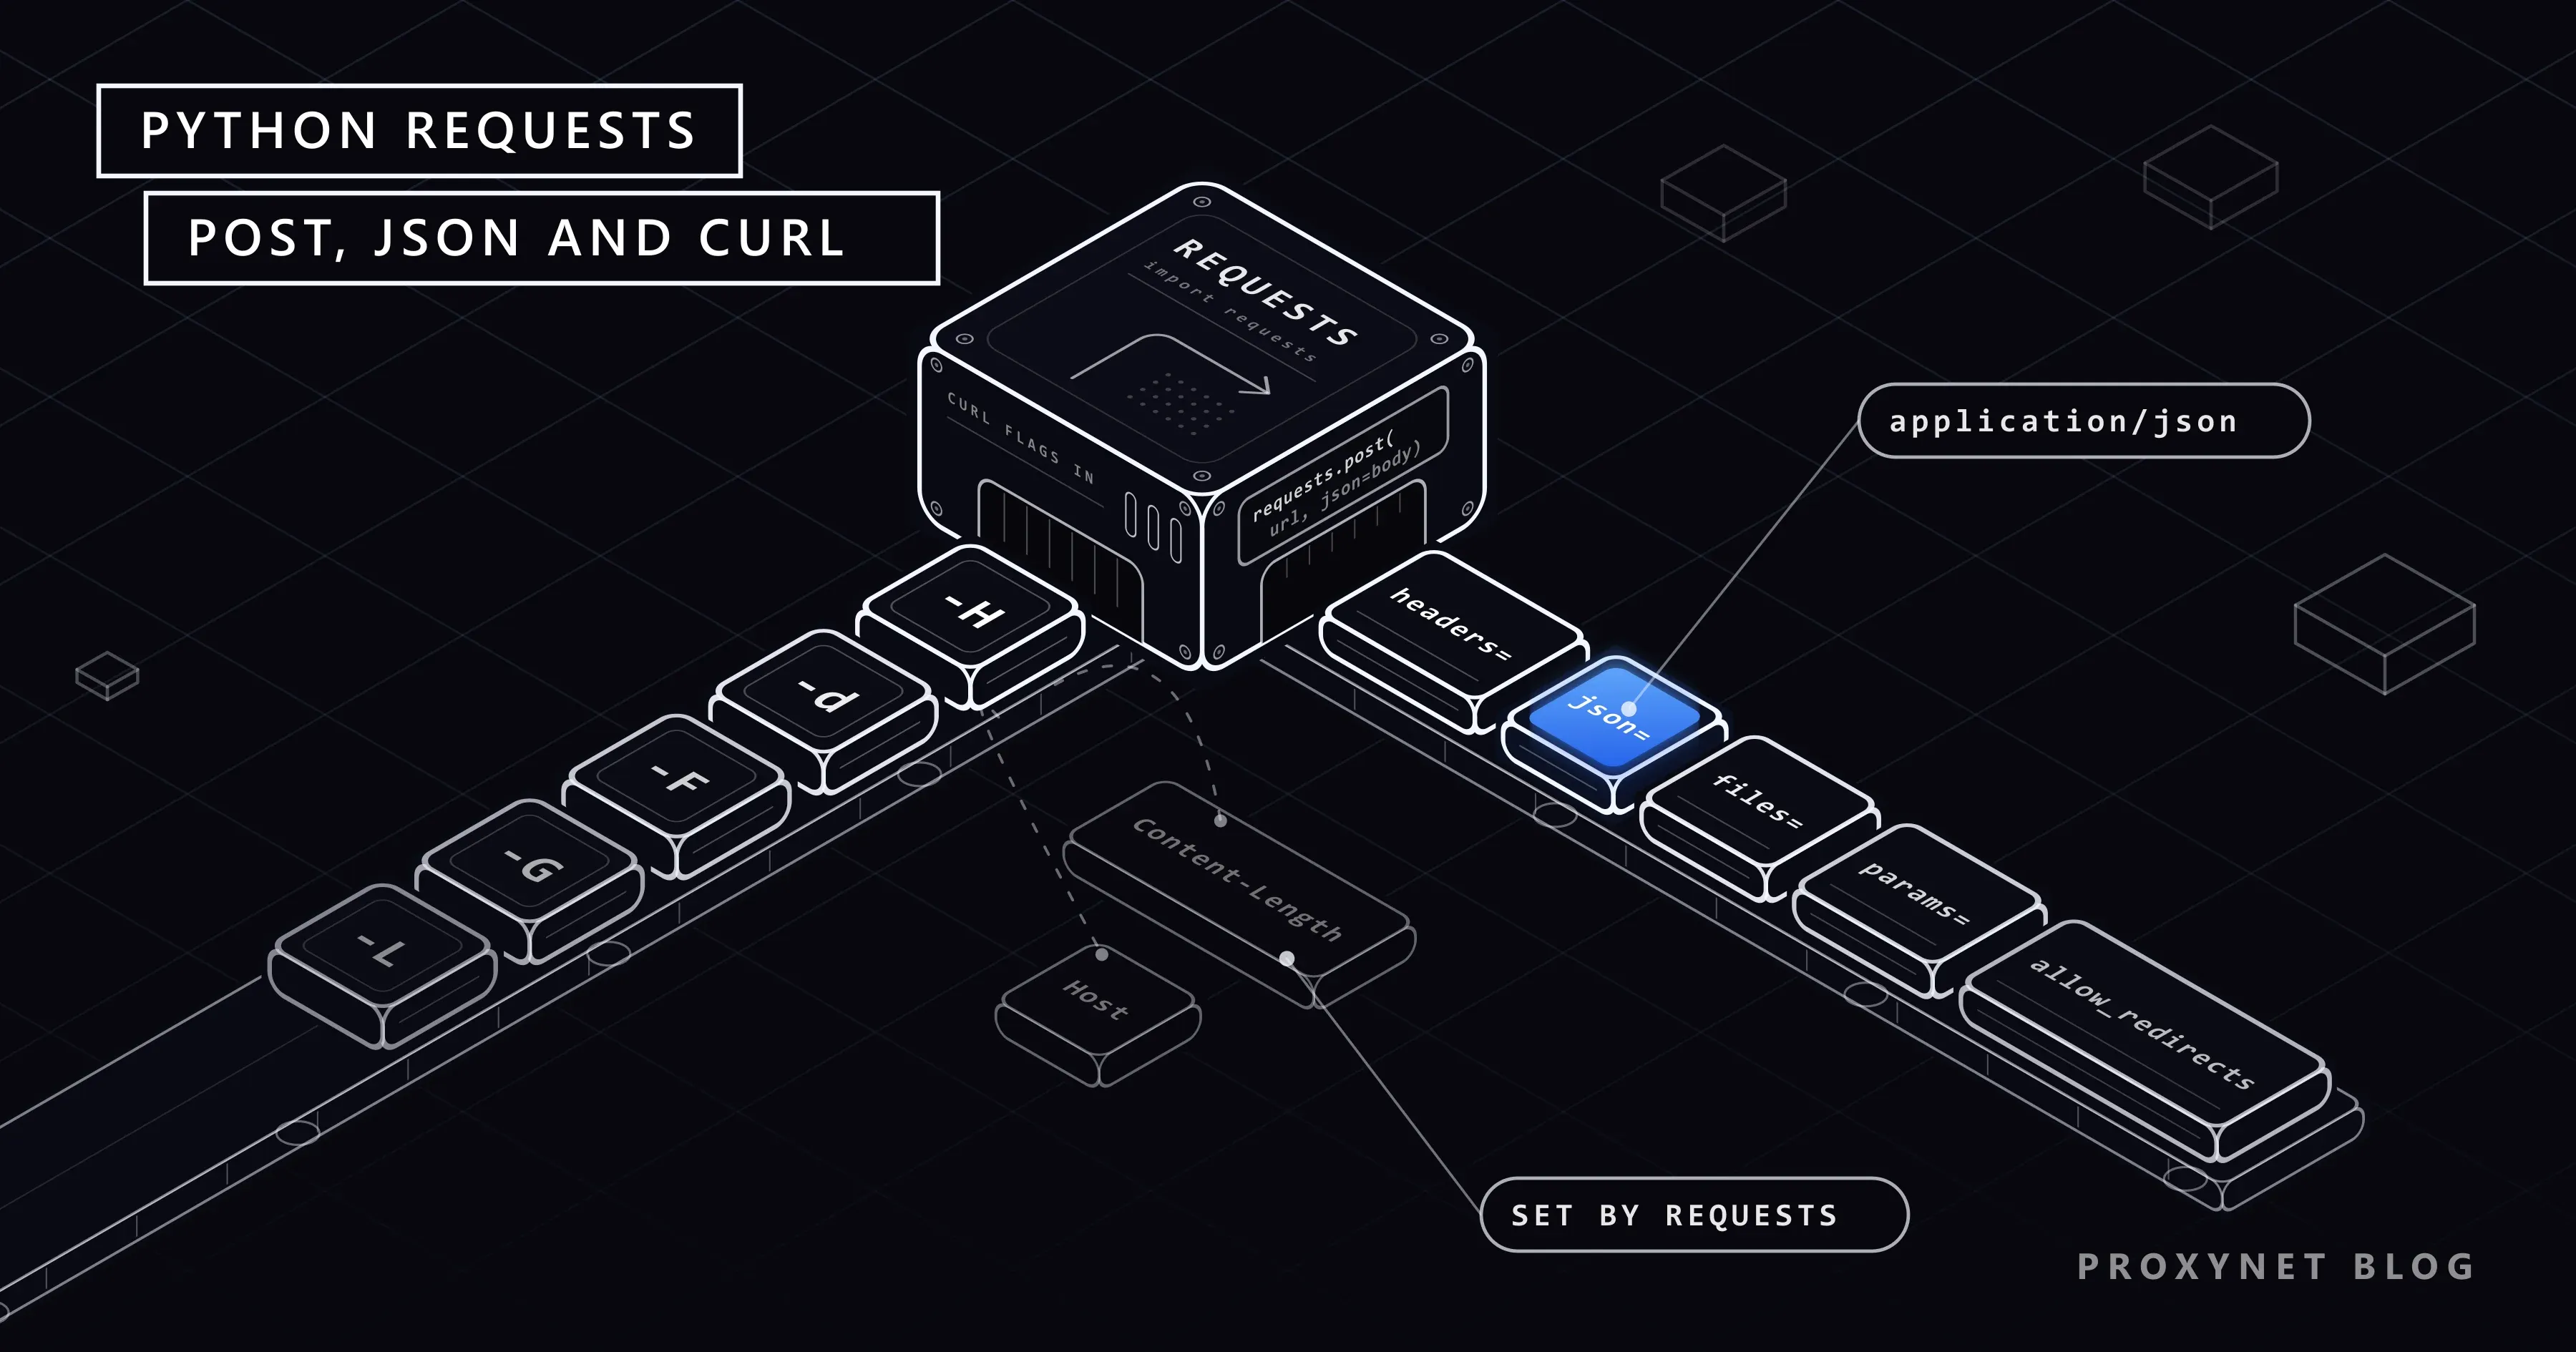
How to POST JSON with Python Requests: cURL Equivalents
To POST JSON with Python Requests, call requests.post(url, json=data) and the Content-Type is set for you. See how data=, params=, headers and cURL flags map.
Written by:Acar Diveroli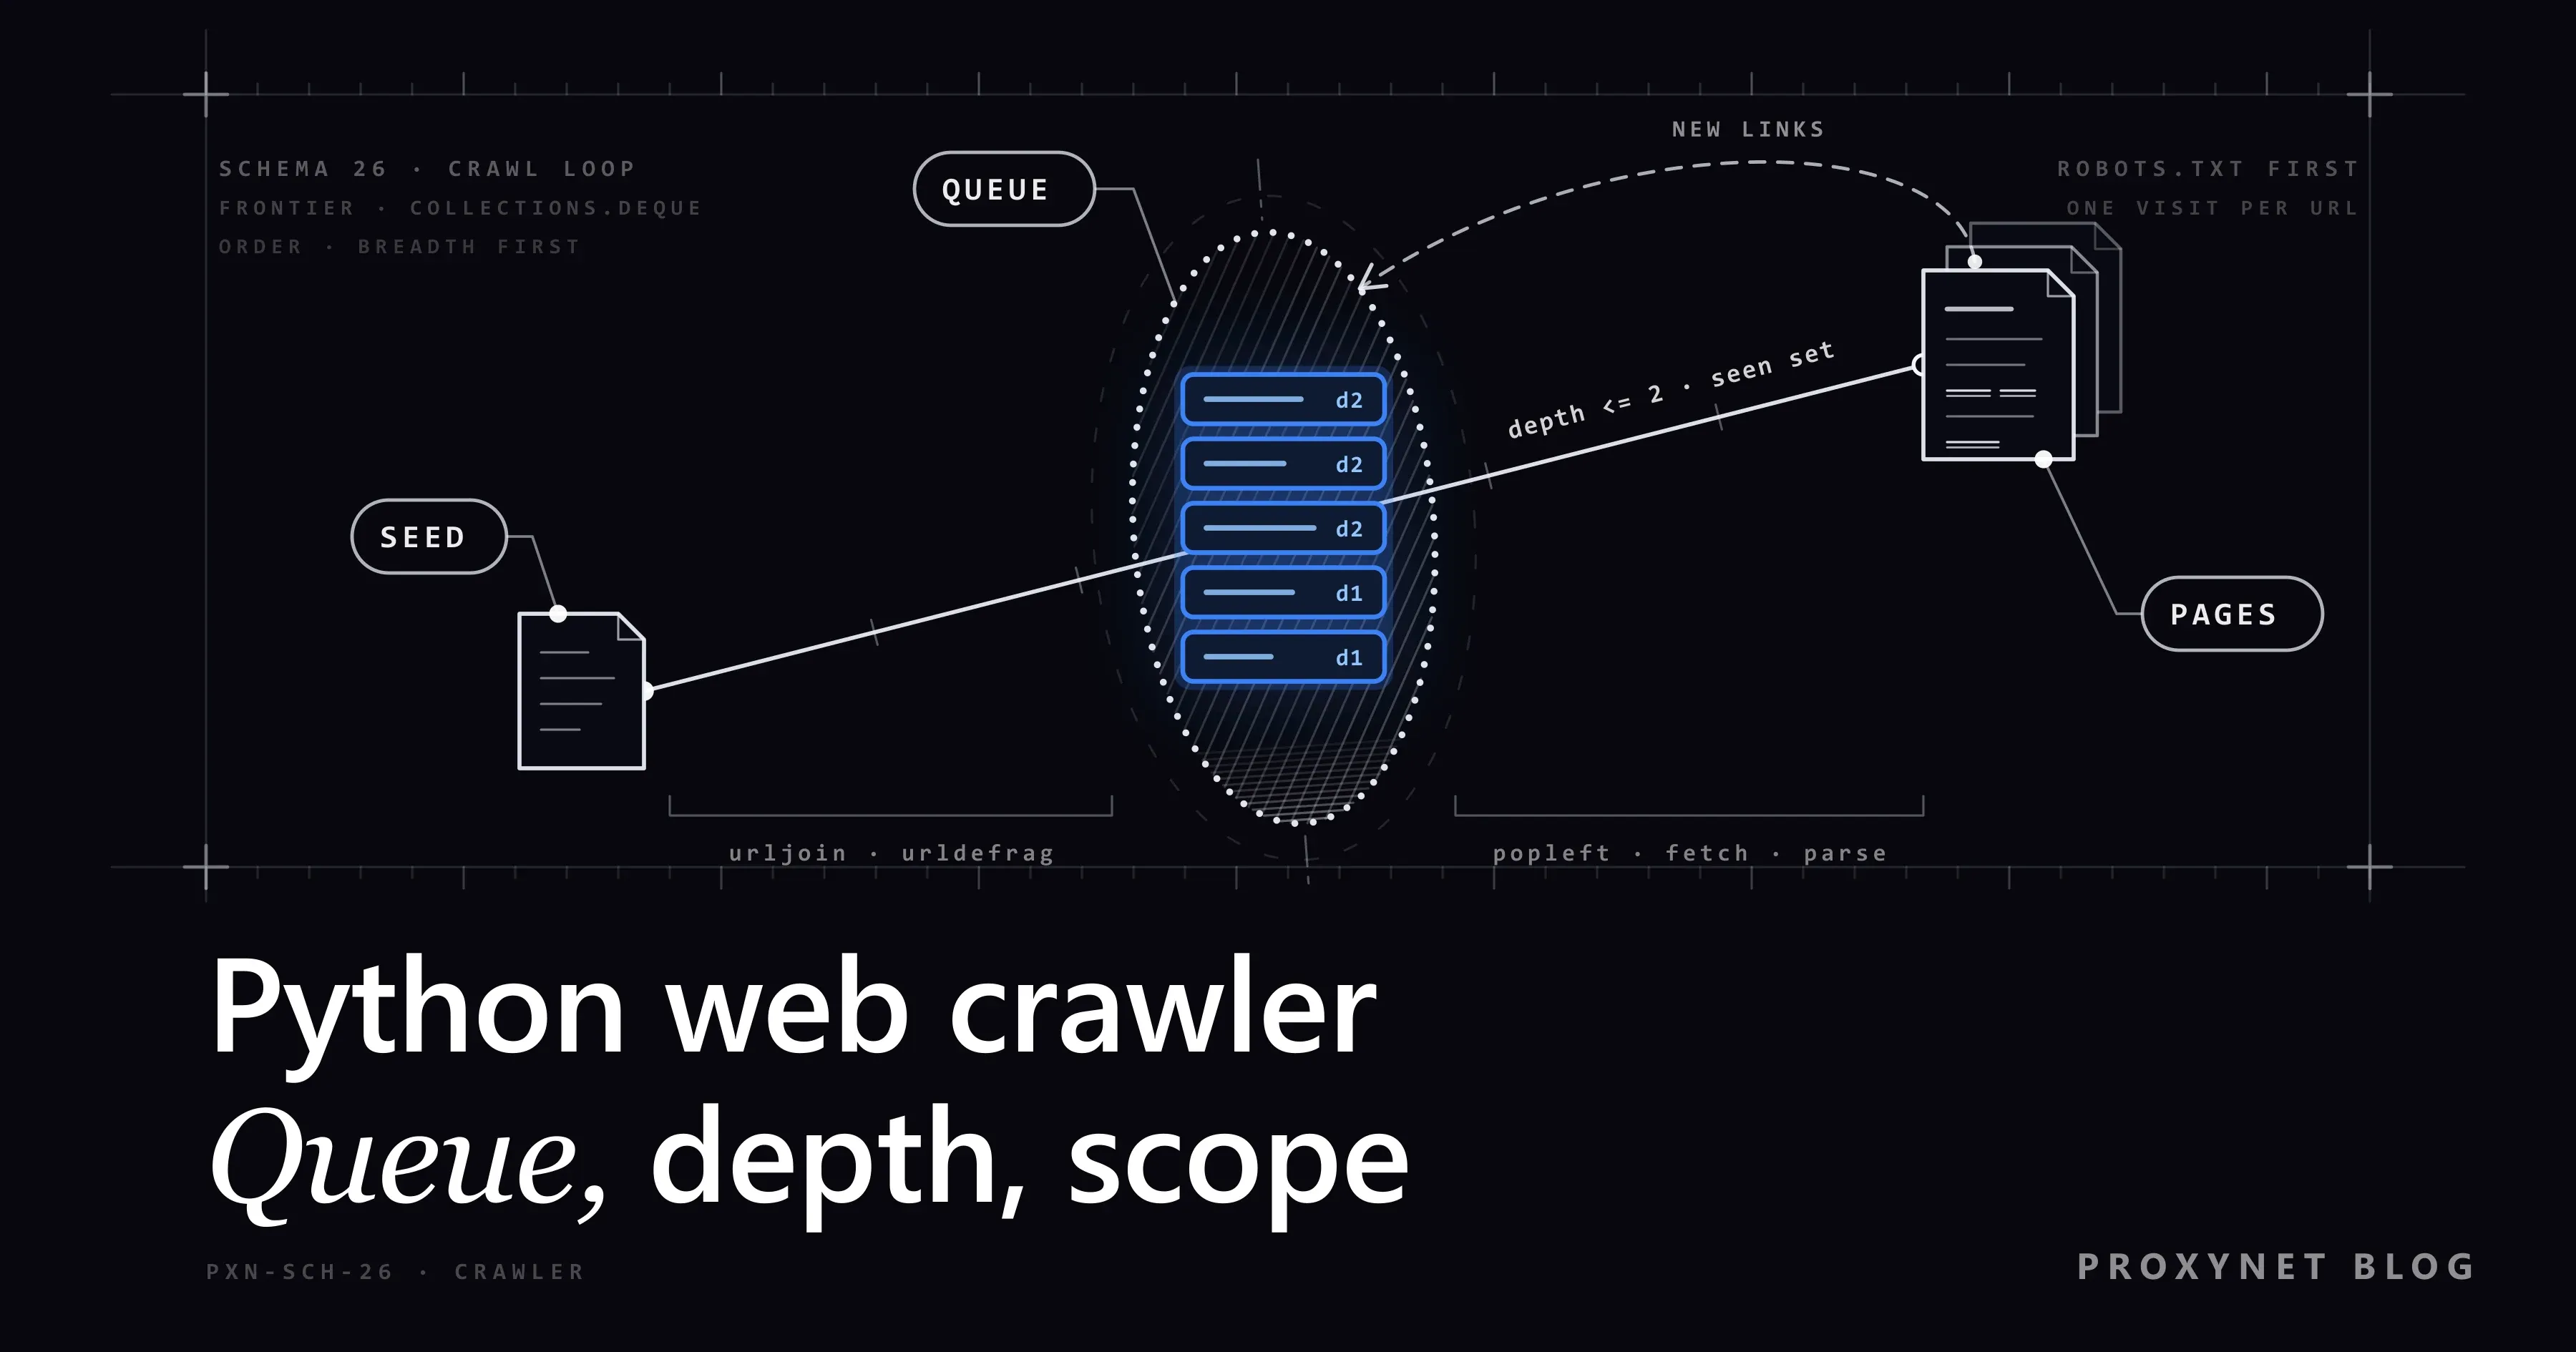
Published
How to Build a Web Crawler in Python, Step by Step
A Python web crawler queues the links it finds from a start URL and visits each page once. We build the queue, URL normalization, depth limit and scope in code.
Written by:Acar Diveroli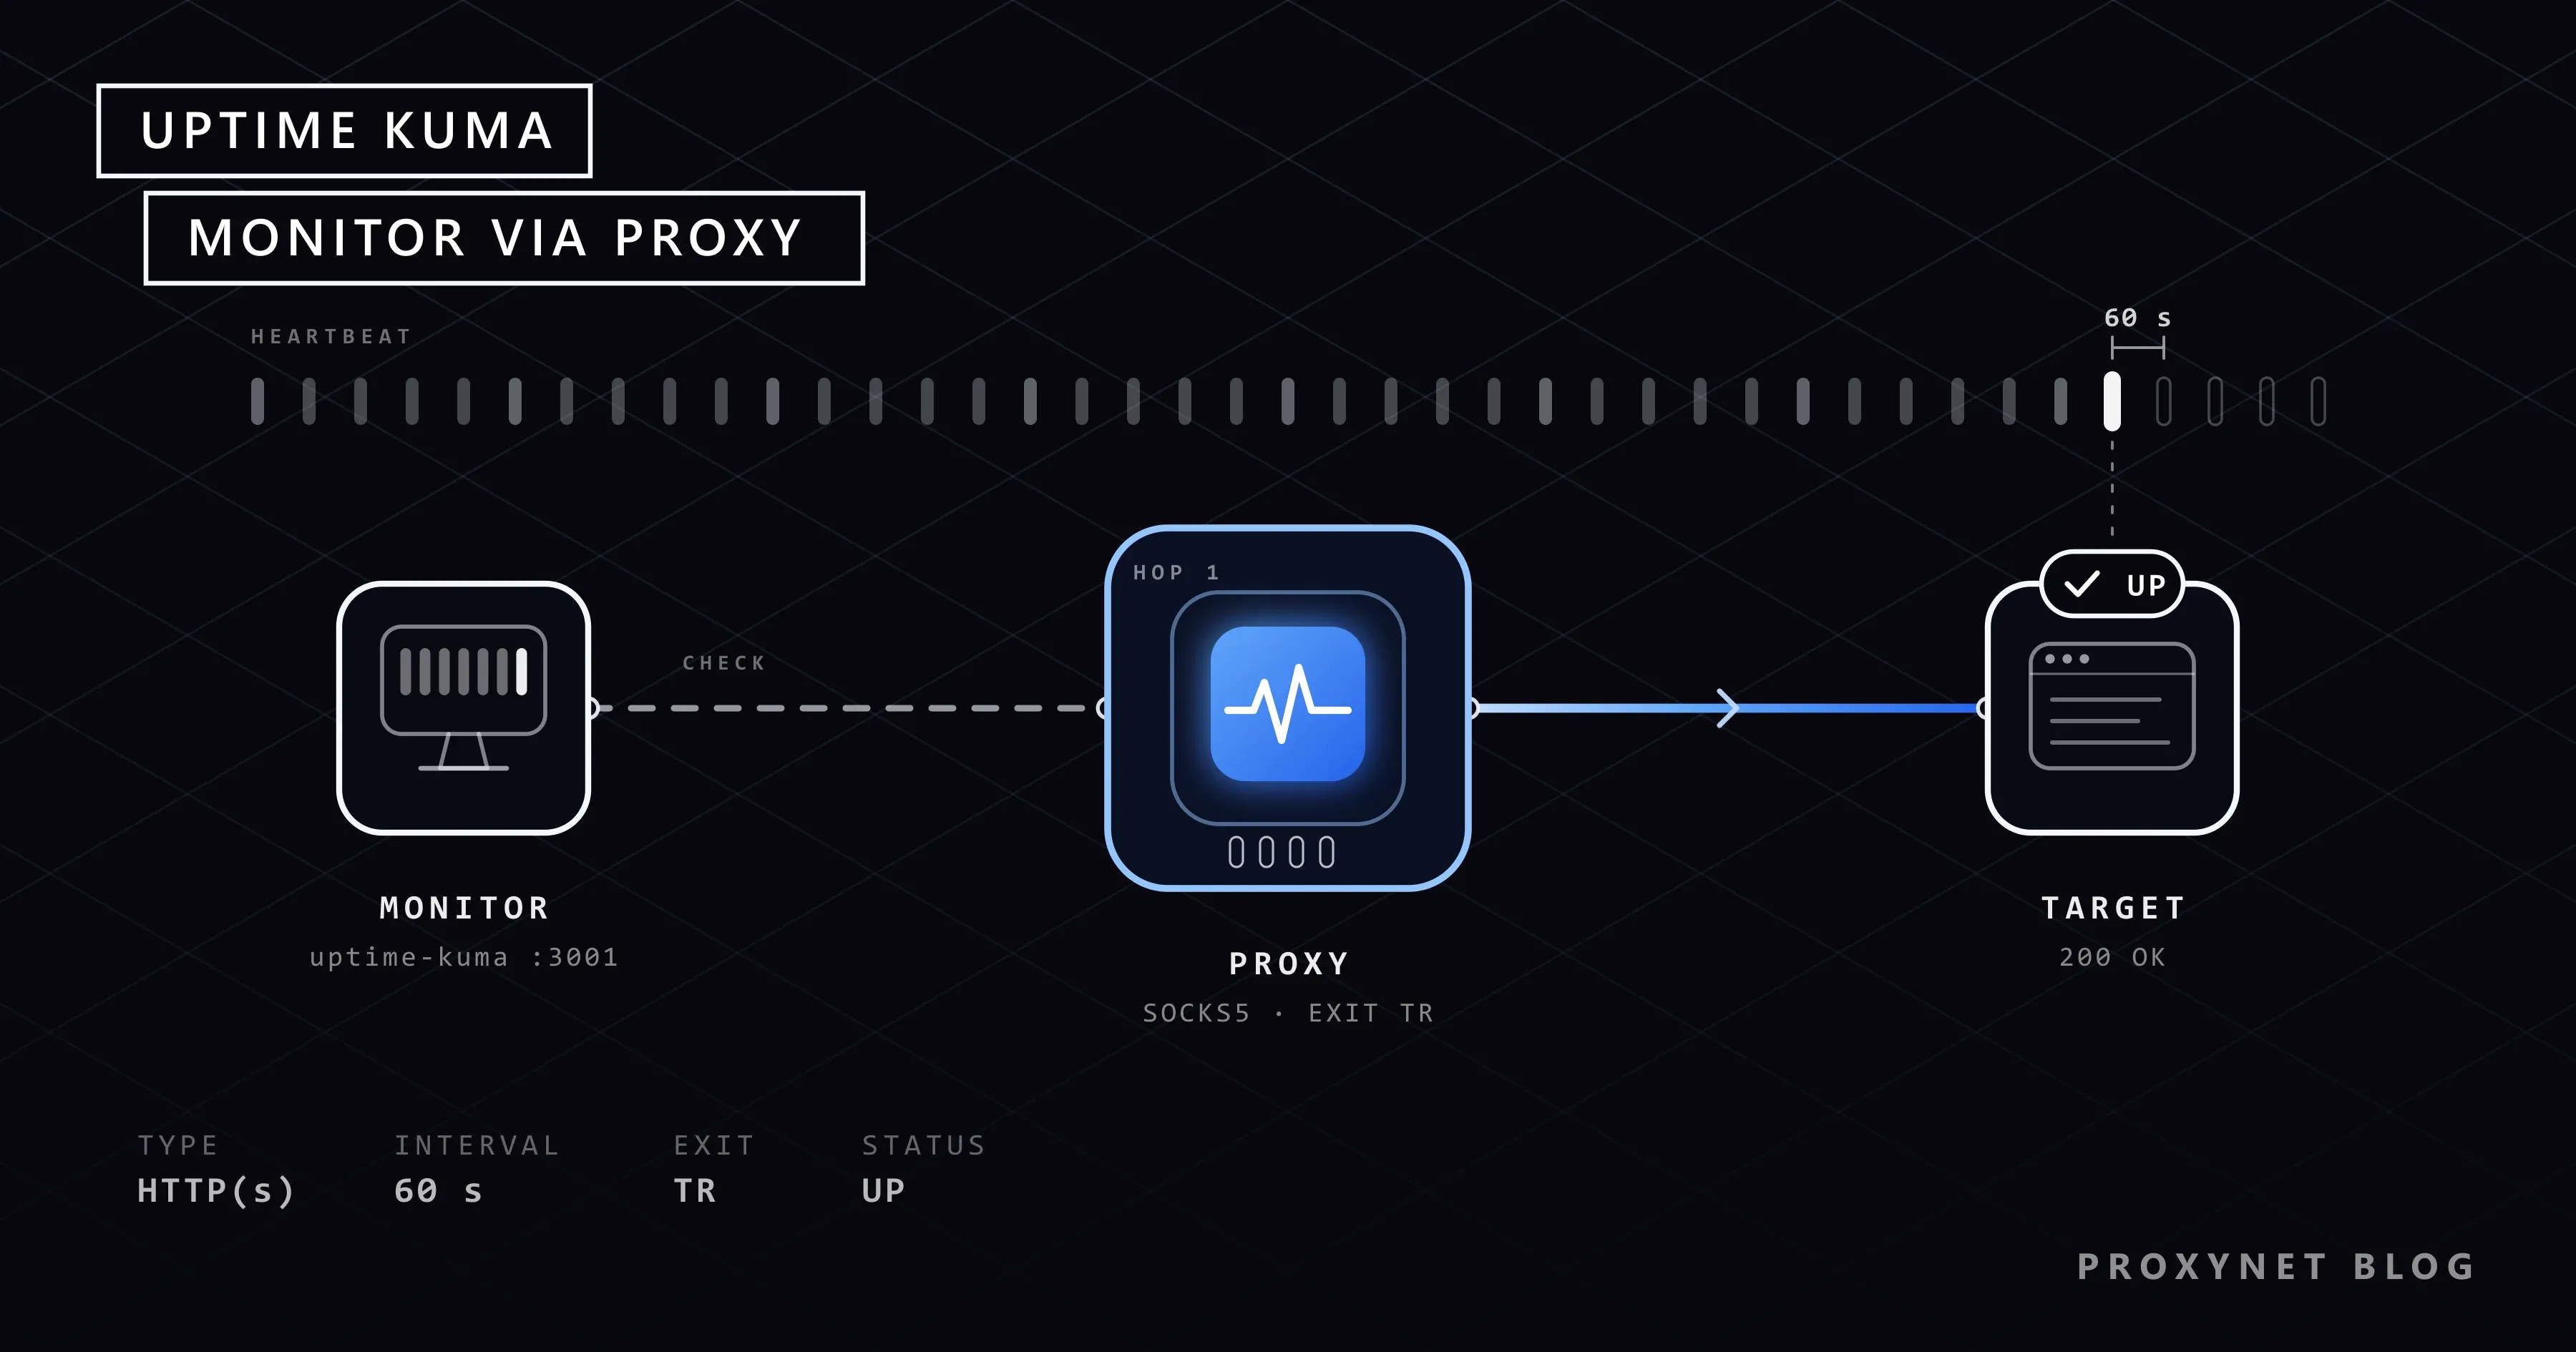
Published
What Is Uptime Kuma? Setup and Monitoring Through a Proxy
Uptime Kuma is a free, open-source tool that checks your site at a set interval and alerts you when it goes down. We cover Docker setup and proxy settings.
Written by:Enver Kaya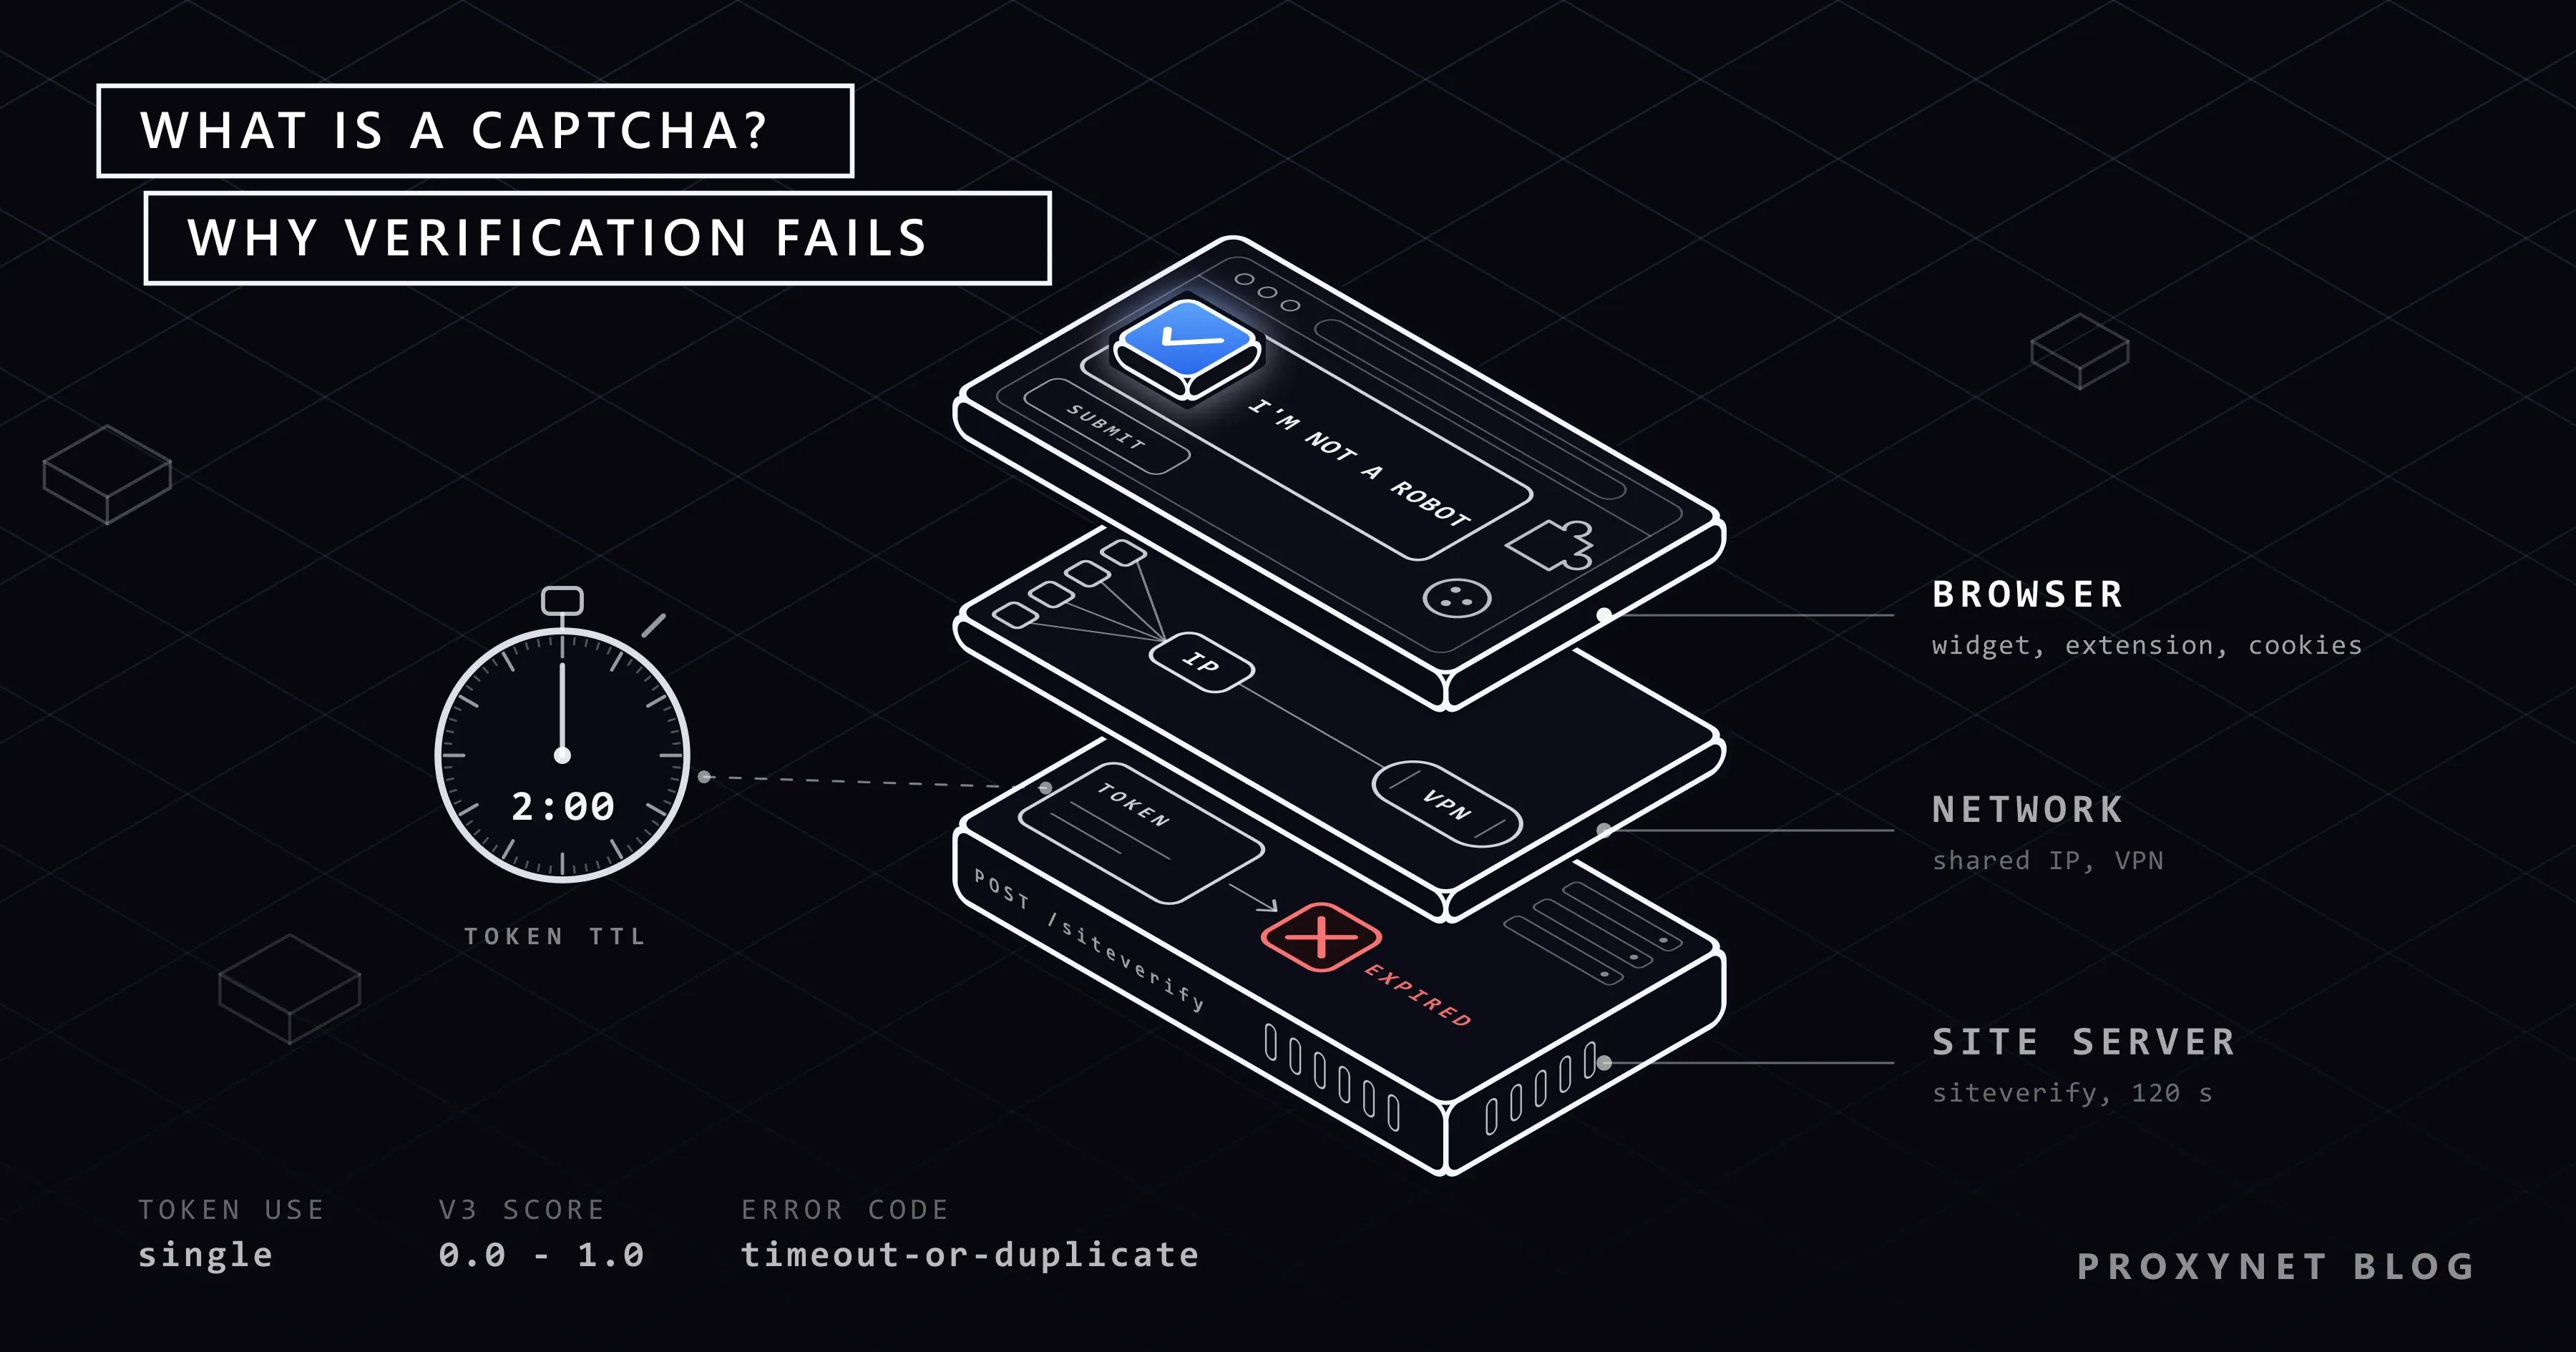
Published
What Is CAPTCHA? Why Does Verification Fail?
CAPTCHA is a short test a site uses to tell people from bots. We explain reCAPTCHA, Verification Failed, Invalid and Expired messages, and what to try first.
Written by:Enver Kaya
Published
What Is BeautifulSoup and How Do You Use It in Python?
BeautifulSoup is a Python library that turns downloaded HTML into a searchable tree. We cover parser choice, find_all versus select, and reading HTML tables.
Written by:Acar Diveroli
Published
What Is Crawl4AI? Setup and Proxy Configuration
Crawl4AI is an open-source Python crawler that turns web pages into LLM-ready Markdown. We cover pip and Docker setup and proxy configuration with ProxyConfig.
Written by:Acar Diveroli
Published
How to Download All Images From a Website Without Code
To download all images from a web page, save it in Chrome as "Webpage, Complete" or use a bulk image extension. We also explain why some come out small.
Written by:Enver Kaya
Published
How to Find a Website's Sitemap and List All Its Pages
Check the Sitemap line in robots.txt first, then common paths like /sitemap.xml. We show how to read sitemap indexes, .gz files and lastmod with Python.
Written by:Acar Diveroli
What Is Geo-Blocking and How Do Sites Know Your Location?
Written by: Acar DiveroliProxiesPublished
Why Are My Google Search Results Different from Others?
Written by: Acar DiveroliProxiesPublished
X Post Withheld in Your Country: What It Means
Written by: Acar DiveroliProxiesPublished
Access Denied Error on Websites: What Reference #18 Means
Written by: Enver KayaTutorialPublished
How to POST JSON with Python Requests: cURL Equivalents
Written by: Acar DiveroliTutorialPublished
How to Build a Web Crawler in Python, Step by Step
Written by: Acar DiveroliWeb ScrapingPublished
What Is Uptime Kuma? Setup and Monitoring Through a Proxy
Written by: Enver KayaUse CasesPublished
What Is CAPTCHA? Why Does Verification Fail?
Written by: Enver KayaProxiesPublished
What Is BeautifulSoup and How Do You Use It in Python?
Written by: Acar DiveroliWeb ScrapingPublished
What Is Crawl4AI? Setup and Proxy Configuration
Written by: Acar DiveroliAIPublished
How to Download All Images From a Website Without Code
Written by: Enver KayaWeb ScrapingPublished
How to Find a Website's Sitemap and List All Its Pages
Written by: Acar DiveroliWeb ScrapingPublished
No posts match
Published
Published